> This is part 1 of 2 of the full documentation (pages 1–100 of 150).
> The content is paginated: fetch every part to see all of it.
> Next part: https://docs.reorc.com/llms-full.txt/1
> Page index: https://docs.reorc.com/llms.txt

# About ReOrc

## What is ReOrc?

ReOrc is a unified data platform that delivers seamless analytics and high-quality data at scale. The Reorc platform empowers all stages of data lifecycle, allowing data practitioners to build and maintain robust transformation pipelines.

## Key modules

As an all-in-one solution for data needs, ReOrc contains the following key modules:

* **Data ingestion**: ReOrc offers a wide range of built-in connectors to effortlessly load data from sources into a common destination. You can also create your own connectors to customize ingestion scheme.
* **Data modeling**: ReOrc supports data transformation through SQL and Python models, leveraging the best practices of data modeling with version control and lineage tracking to ensure transparency and consistency.
* **Semantic modeling**: ReOrc semantic layer enables organization to create a unified and business-friendly representation of data, such as key metrics and their relationships. End-users can then query from semantic models to make decision based on the data.
* **Data orchestration**: Build end-to-end pipelines that cover the entire data life cycle, including ingestion, transformation, semantics, with out-of-the-box operators and intuitive visual graphs.
* **Quality control**: ReOrc is built with quality control in mind, that's why tests and quality checks are applied to all types of assets to make sure your data meet predefined standards.

While embracing the modern data stack's innovation, ReOrc also helps data practioners solve key challenges in modern data systems:

* Tangled pipelines: With data of high volume and complexity, comes the need for intricate ETL processes, models, and tools. Managing these disparate components is challenging without a centralized control system.
* Insufficient governance: Control is scattered across multiple tools and users, making it difficult to enforce consistent, secure, and compliant data practices.
* Fragmented observability: Without a unified view of your data flow, cataloging assets, tracking lineage, monitoring quality, and troubleshooting issues are significantly hindered.
* Siloed knowledge: Knowledge silos are inevitable when teams and individuals become more specialized in isolated tools. This cripples collaboration and cross-functional communication, leading to missed opportunities and less effective data solutions.


# Philosophy


# Set up and deployment

This section provides the information and guidelines on setting up ReOrc.

## Architecture overview

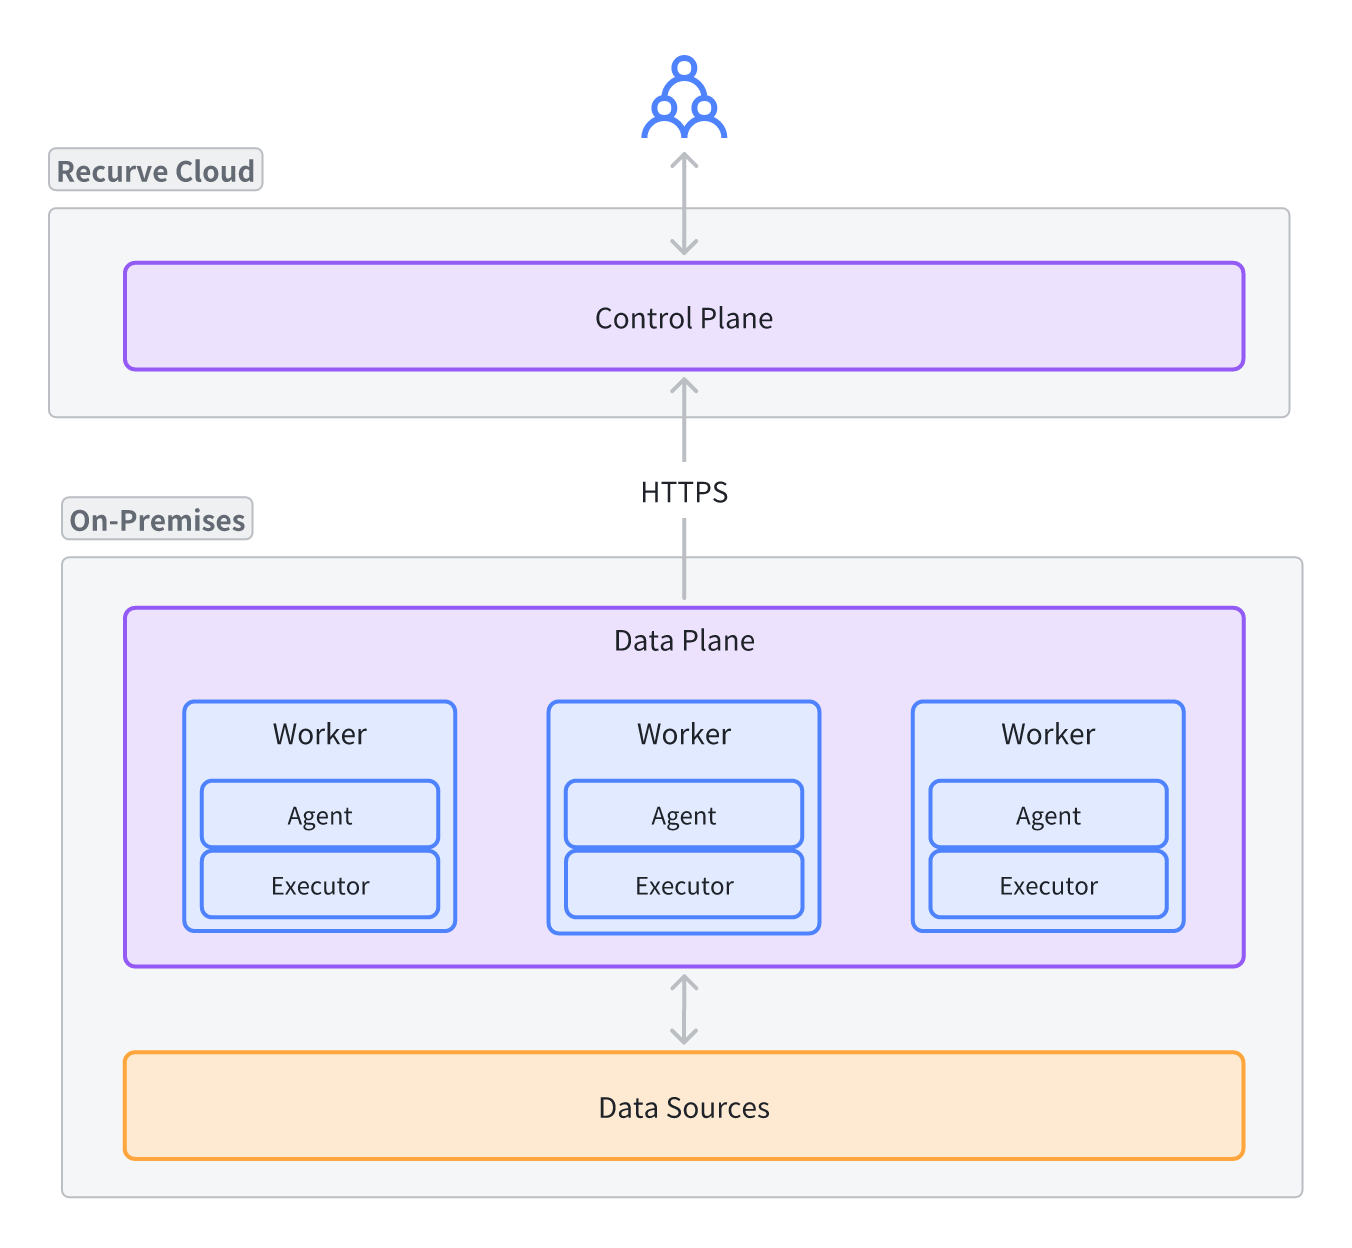
Recurve services are structured into two parts:

* **Control Plane**: Runs within the Recurve cloud system and provides the web interface for users to manage projects and pipelines.
* **Data Plane**: Receives instructions from Control Plane and runs the actual data jobs, which include data ingestion, transformation, pipeline tasks, or delivery to other systems. The Data Plane consists of multiple worker hosts that are orchestrated by the Control Plane.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FKcqeuN5jwhRTOZp7QUXb%2FRecurve_high_level_architecture.png?alt=media&amp;token=f189ac59-4c3e-40ea-9de4-6d744635da05" alt="" width="563"><figcaption></figcaption></figure>

This separation offers flexibility in deployment, where worker hosts of Data Plane can be installed in different locations to fit your organization's requirements in performance, maintainability, security, and compliance.&#x20;

The current version of Recurve supports setting up Data Plane services within users' infrastructure.

Follow these two guides to set up your organization and install Recurve agent (the core Data Plane service):

1. [Set up organization](/set-up-and-deployment/set-up-organization)
2. [Install Recurve agent](/set-up-and-deployment/install-reorc-agent)


# Set up organization

In ReOrc, organization is the highest structure that include multiple projects and users. The organization owner can manage billing information, user permissions, and other resources.

This guide shows you how to set up an organization.

{% hint style="info" %}
**Prerequisite:** You already have a ReOrc account. Otherwise, visit [ReOrc](https://recurve.cloud/login) to create one.
{% endhint %}

## Create an organization

1. In the **Welcome** dialog after you've created an account, select **Create Organization**.
2. Provide the name and domain for your organization. This domain name is the unique identity for your organization and the destination when you access ReOrc.

## Set up environments

A ReOrc organization always needs two types of environment: development and production.

Similar to the practice in software engineering, environments refer to the separate setups used for different stages of a project's lifecycle. Development is the playground where data engineers build, experiment, and test new setups and transformations. Meanwhile production contains the fully tested, stable data workflows.&#x20;

When you create an organization, ReOrc already sets **dev** and **prod** by default.

To access environment setup, on the left sidebar, click on the ![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F51zaoCWOFicQbz4UQdTX%2FaddAfter.jpg?alt=media\&token=0fae735d-2646-4b94-ad71-88592df04419) icon and select **Environments & Workers**.&#x20;

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F4DGwU3z6HYW6TqMvEd8E%2FRecurve_environments_and_workers.png?alt=media&amp;token=3431a0d9-80ed-4273-9b10-054f9319ccde" alt=""><figcaption></figcaption></figure>

Once you've set up the environments, the next step is to [install reorc-agent](/set-up-and-deployment/install-reorc-agent).


# Install ReOrc agent

Data Plane of ReOrc consists of multiple worker hosts to run the data jobs orchestrated from the Control Plane.&#x20;

Each worker contains a service called ReOrc Agent that communicates with Control Plane and manages execution environments on the host. Some rules for setting workers are as follows:

* Multiple workers can be set up for horizontal scalability.
* Workers can be installed in different places across the Internet.
* Workers that are meant for a single environment must be able to communicate with each other. Therefore, it is recommended that workers for the same environment be located in the same local network, for maximum connection stability and minimum latency.

This guide shows you how to set up ReOrc agent.

## Requirements

Your worker hosts should meet these requirements.

**Hardware**:

Depending on the usage, your setup can follow these configuration ranges to optimize the performance with ReOrc.

<table data-full-width="false"><thead><tr><th width="161"></th><th>Number of workers</th><th>CPU (cores / worker)</th><th>Memory (GB / worker)</th><th>Disk (GBs/worker)</th></tr></thead><tbody><tr><td>Minimum</td><td>1</td><td>2</td><td>4</td><td>20</td></tr><tr><td>Recommended</td><td>2+</td><td>4</td><td>16</td><td>100</td></tr></tbody></table>

**Software**:&#x20;

* Operating System: Linux (RHEL and Ubuntu are tested).
* Python: 3.9+, we recommend using a newer version and virtual environment if feasible.
* [Docker](https://docs.docker.com/engine/): 20.10.0+, with Docker Compose installed.

{% hint style="info" %}
Make sure the user runs the ReOrc agent has access to docker cli. This command might be helpful. You may need to logout and re-login to the terminal session after modifying the user's group.

```bash
sudo usermod -aG docker $USER 
```

{% endhint %}

## Set up ReOrc Agent

Follow these steps:

1. On the left sidebar of ReOrc, click on the *Organization* icon and select **Environment & Workers**.
2. Click **Deploy Agent** and follow the on-screen instructions to deploy the agent.

   Alternatively, follow the steps below.

<details>

<summary>Install ReOrc agent in CLI</summary>

1. On the worker host: Install the agent package.

```bash
pip install -U reorc-agent
```

You can verify the installation by running the `reorc version`.

2. On the worker host: Register the host to the Control Plane

```bash
reorc login
```

3. On the **Environments & workers** page, click **Deploy Agent**, copy the API key, and paste it to the host.
4. On the worker host: Start the agent; it will keep sending heartbeats to the Control Plane.

```bash
reorc agent start
```

5. [#run-the-agent-in-background](#run-the-agent-in-background "mention").

   It is essential to maintain persistent functionality and connection of the agent.

</details>

3. Refresh the page to see the newly deployed host. The status should be **Online**.
4. Allocate the agent to an environment.&#x20;

   Once the agent is running with the **Online** status, click *action* > **Join Environment** and select the environment to allocate. When the agent successfully joins the environment, you should see the **Active** status.

{% hint style="info" %}
**Note:**&#x20;

* The `reorc agent start` command starts the agent in the foreground, and will terminate after the terminal session closed. For production deployment, you should let the agent run in the background. For more details, refer to [Run Agent in Background](#run-the-agent-in-background).
* Both `dev` and `prod` must have at least one agent running.
  {% endhint %}

## Actions on an agent

Once the agent is up and running, there are some key actions that you can perform with the service. Click on the *action* button of an agent:

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FyR6xzUAlZGMoamyM0PBX%2FRecurve_actions_on_agent.png?alt=media&amp;token=ada52ec3-b0d9-41fe-9f07-efdb127d3031" alt=""><figcaption></figcaption></figure>

Here you can:&#x20;

* **Upgrade Service**: Upgrade the worker service to the latest version.
* **Restart Service**: restart the agent service; the agent will still join the environment after restarting.
* **Stop Service**: stop the agent service; the agent will become inactive.
* **Leave Environment**: remove the agent service from the current environment.

## Run the agent in the background

There are multiple ways to run an agent in the background with [systemd](https://systemd.io/).

<details>

<summary>systemd</summary>

1. Install the ReOrc service with the following command line, and the service will be started automatically after it has been installed.

```bash
reorc service install
```

2. Use the following command to manage the service

```bash
systemctl start reorc-agent
systemctl stop reorc-agent
systemctl status reorc-agent
```

</details>

## Upgrade the agent

Keeping the reorc-agent updated is always recommended.

To upgrade the agent , follow these steps:

1. Stop the agent service.

   Depending on the way you manage the service, you may need to run one of these commands to stop the process:

```bash
# if managed by Systemd
sudo systemctl stop reorc-agent

# if managed by Supervisor
supervisorctl stop reorc-agent
```

2. Upgrade and re-login.

```bash
# Upgrade to the latest version
pip install -U reorc-agent

reorc login
```

3. Start the agent.

```bash
# if managed by Systemd
sudo systemctl start reorc-agent

# if managed by Supervisor
supervisorctl start reorc-agent
```


# Getting started

This guide shows you how to get started with ReOrc

This guide covers the capabilities currently available in the beta release, allowing you to connect to a database, create data models using sources and SQL models, build pipelines incorporating these models, and schedule job runs directly from the pipeline.

{% hint style="info" %}
**Prerequisites:**

* You have a Recurve account. If not, you can sign up here: [ReOrc](https://reorc.cloud/signup)
* You have been invited to an organization, with environments and workers running. For instructions, see: [Set up and deployment](/set-up-and-deployment).
  {% endhint %}

## Step-by-step workflow

Follow these steps to get started with Recurve:

1. [**Set up a connection**](/getting-started/1.-set-up-a-connection)
   * Connect ReOrc to your data sources (relational database, data warehouse).
   * Authenticate and configure the connection details.
2. [**Create a project**](/getting-started/2.-create-a-project)
   * Set up a project as a collaborative space for your team.
   * Configure an analytics database to store and process the transformed data of the project.
3. [**Create data models**](/getting-started/3.-create-data-models)
   * Reference your raw data as sources.
   * Define your transformation logic using models.
   * Add tests to validate that your models are working properly.
4. [**Build the models in console**](/getting-started/4.-build-models-in-console)
   * Execute model builds in console and run associated data tests to verify transformations.
   * Debug failed tests, optimize performance, and iterate models based on validation results.
5. [**Set up a pipeline**](/getting-started/5.-set-up-a-pipeline)
   * Automate the workflow in a pipeline by chaining together your data models.
   * Configure the pipeline execution and schedule in a job.
   * Monitor the pipeline through the Health Tracking dashboard.

Throughout these guides, we'll introduce you to the key components of Recurve and provide necessary links for more detailed information on each step. Let's get started!


# 1. Set up a connection

Before you can begin transforming your data, you'll need to establish connections to your data destinations - the "L" (Load) in the ELT (Extract, Load, Transform) pipeline. These destinations are where your ingested data will ultimately reside, whether it's a database, data warehouse, or data lake.

The **Destinations** section in Recurve serves as your centralized hub for managing these crucial connection points. Here you can configure and maintain connections to various data storage systems.

For a simple, first-time connection, we recommend you set up connection to a relational database or a data warehouse, so that the raw tables are ready for data modeling without extra transformation.

To access **Destinations**, from Recurve left sidebar, select **Connections** -> **Destinations**.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FYhTIU1IDIRjrjR2iCQVg%2FRecurve_destinations_button.png?alt=media&amp;token=ccc6daea-8a68-4985-9743-81dcf14ecea6" alt=""><figcaption></figcaption></figure>

In the **Destinations** page, click **+ Create Connection**.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FqWsW7emIcUuiBQRK7bDM%2FRecurve_destinations_create_connection_button.png?alt=media&amp;token=2199e32e-5bbe-41df-8db2-8641eac1005f" alt=""><figcaption></figcaption></figure>

Select the connector to your data source and click **Set up**.

Each connector has its own set of authentication fields and configuration parameters. You can check out the list of available data sources here: [Destinations](/connections/destinations).

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FEtIQ670FkNp0Ozkv7WqD%2FRecurve_choose_your_destination.png?alt=media&amp;token=d9ffd80c-9788-4968-a14c-f938fd694e40" alt=""><figcaption></figcaption></figure>

For a practical demo, you can follow the setup guide for specific data warehouse:

* [BigQuery setup](/getting-started/1.-set-up-a-connection/bigquery-setup)
* [Snowflake setup](/getting-started/1.-set-up-a-connection/snowflake-setup)


# BigQuery setup

Recurve's BigQuery connector enables you to seamlessly integrate your BigQuery data warehouse as a destination for your analytics database. This guide walks you through establishing a secure connection using Google Cloud service accounts, from initial setup to your first successful connection.

You'll learn how to:

* Prepare a sample dataset in your Google Cloud Project (GCP).
* Create and configure a service account with sufficient permissions.
* Establish a connection between Recurve and BigQuery.

### Prerequisites

* You already join a Recurve organization.
* You've already created a [GCP project](https://developers.google.com/workspace/guides/create-project).

### Prepare sample dataset

To demonstrate the connetion process, we'll be using the `jaffle_shop` dataset — a fictional e-commerce store's data provided by the dbt community. This dataset offers a practical example of typical e-commerce data structures that mirror real-world scenarios.&#x20;

You can use the [jafgen](https://github.com/dbt-labs/jaffle-shop-generator) CLI tool generate synthetic data for any specified year range.

The dataset includes these tables:

* Customers (who place Orders)
* Orders (from those Customers)
* Products (the food and beverages the Orders contain)
* Order Items (of those Products)
* Supplies (needed for making those Products)
* Stores (where the Orders are placed and fulfilled)
* Tweets (Customers sometimes issue Tweets after placing an Order)

Or simply download the generated data below:

{% file src="/files/oYDfqEhOrOPCXZBLY5sJ" %}

### Ingest sample data

Follow these steps to ingest the data:

1. Go to your [GCP project console](https://console.cloud.google.com/bigquery).
2. Create a new dataset:
   1. Expand the *Actions* option and select [**Create dataset**](https://cloud.google.com/bigquery/docs/datasets#create-dataset).&#x20;
   2. Enter provide a name for the dataset in **Dataset ID**. You can leave the other fields as default.
   3. Click **Create dataset**.

      <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FFl5yeuKv6HPoIW7Y7b7I%2FBigQuery_create_dataset.png?alt=media&amp;token=7474ab1f-21a2-450c-b813-f6484a828919" alt=""><figcaption></figcaption></figure>
3. Create tables for the dataset.
   1. Click on the *Actions* option of the dataset and select **Create table**.
   2. Choose **Upload** as the creation method, select the CSV file, and name the table after the file name. For example, we upload the `raw_orders.csv` and name the table `raw_orders`.
   3. In **Schema**, check **Auto detect** to automatically generate the schema for the table.
   4. Click **Create table**.

      <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FNmJXNYB0mPaBvT5vcwhu%2FBigQuery_create_table.png?alt=media&amp;token=69c21d35-8682-4c77-a875-bdb8cebf733b" alt="" width="375"><figcaption></figcaption></figure>
   5. Repeat the four steps above to create and upload the other tables.

### Create a service account

After loading data into the project, you need to create a Google Service Account. This account represents the identity and permissions that the connector can use to authenticate and interact with BigQuery.

Follow these steps:

1. Go to the [GCP credentials wizard](https://console.cloud.google.com/apis/credentials/wizard) and select your project.
2. Enable BigQuery API:
   1. Select **BigQuery API** from the dropdown.
   2. Choose **Application data** for data processing type.
   3. Click **Next**. This navigates to to the **Create service account** section.
3. Configure your service account:
   1. Provide a descriptive name for your service account.
   2. Click **Create and continue**.
   3. Assign the two following roles:
      * BigQuery Job User.
      * BigQuery Data Editor.
   4. Click **Done**.

      <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FUNuxUYr8jarD7sT82DyK%2FBigQuery_create_service_account.png?alt=media&amp;token=a61e203e-0366-46e8-bc4d-27c0eebc999e" alt="" width="375"><figcaption></figcaption></figure>
4. After the service account is created, the console navigates you to the [Credentials](https://console.cloud.google.com/apis/credentials) page, where you can generate keys to authenticate the account. Locate the **Service Accounts** rows and click on the account
   1. Navigate to the **Keys** tab.
   2. Click the **Add key** ->  **Create new key**.
   3. Select **JSON** as the **Key type** and click **Create**. This will download the JSON file that contains authentication credentials and metadata.

      <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FY1dXob1JANTkIAIsZ5Q2%2FBigQuery_create_private_key.png?alt=media&amp;token=71eca027-56b8-48a8-a462-b83bd590fa82" alt="" width="563"><figcaption></figcaption></figure>

### Connect Recurve to BigQuery

With the Google Service Account key, you now can set up a connection to BigQuery from Recurve.

Follow these steps:

1. Open the left sidebar.
2. Navigate to  **Connections** -> **Destinations**.
3. Click **+ Create connection**.
4. Select **Google BigQuery**.
5. Fill in the fields with the information from the JSON key file.&#x20;
   * **Destination name**: the name to identify this specific connection in your organization.
   * **Auth Type**: `service_account`&#x20;
   * **Google Project ID**: the unique identifier for your GCP project
   * **Google Auth Private Key ID**: the unique identifier for your service account's private key
   * **Google Auth Private Key**: the actual private key used for authentication
   * **Client ID**: your service account's unique identifier
   * **Client Email**: the email address associated with your service account
6. Select **Development environment** and click **Test connection**.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FbzympnZ3CYJPkevGzaEu%2FRecurve_bigquery_connection_tested.png?alt=media&amp;token=661fd608-6792-4f7d-a8a1-cdf70a94011e" alt="" width="563"><figcaption></figcaption></figure>
7. Once the connection is successfully tested, click **Create Destination**.

The connection is now ready to be used in a project.


# Snowflake setup

The Snowflake connector enables you to quickly establish a connection with your Snowflake warehouse to load data and seamlessly run transformation models.

In this guide, you'll learn how to:

* Prepare a sample dataset in Snowflake
* Set up a connection from Recurve to Snowflake

### Prerequisites

* You already join a Recurve organization.
* You have a Snowflake account. If you don’t have one, sign up for a free trial here: [Snowflake Signup](https://signup.snowflake.com/).

### Prepare sample dataset

To demonstrate the connetion process, we'll be using the `jaffle_shop` dataset — a fictional e-commerce store's data provided by the dbt community. This dataset offers a practical example of typical e-commerce data structures that mirror real-world scenarios.&#x20;

You can use the [jafgen](https://github.com/dbt-labs/jaffle-shop-generator) CLI tool generate synthetic data for any specified year range.

The dataset includes these tables:

* Customers (who place Orders)
* Orders (from those Customers)
* Products (the food and beverages the Orders contain)
* Order Items (of those Products)
* Supplies (needed for making those Products)
* Stores (where the Orders are placed and fulfilled)
* Tweets (Customers sometimes issue Tweets after placing an Order)

Or simply download the generated data below:

{% file src="/files/oYDfqEhOrOPCXZBLY5sJ" %}

### Load data

With the sample data prepared in the CSV files, we can use the Snowflake web interface to load them into your database.

Follow these steps:

1. Go to your [Snowflake web interface](https://app.snowflake.com/).
2. From the homepage, click **Upload local files** to open the data loading wizard:
   1. Click **Browse**, and select a CSV file from the prepared dataset.
   2. Click **+ Database** to create a dedicated database for our use case.

      Here we can name it `RECURVE_DEMO`.
   3. Select **+ Create new table** from the dropdown and enter the corresponding table name. For example, for `raw_customers.csv`, name the table `raw_customers`.

      <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FPlx5ZUYh4yvWZk9kZqwi%2FSnowflake_create_upload_and_create_table.png?alt=media&amp;token=31e9341a-1469-4591-a7fb-b6163797179c" alt=""><figcaption></figcaption></figure>
   4. Click **Next**.

      At this step, Snowflake automatically detects table schema and presents it in the interface. You can verify if the columns' names and data types are correctly detected and adjust accordingly. For our sample CSV files, make sure that the first row is considered the header, containing column names.

      <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FNno2nfNRDbR5AODUDF6w%2FSnowflake_upload_and_create_table_2.png?alt=media&amp;token=9f979b60-e42e-48bc-9a06-989369e69c47" alt=""><figcaption></figcaption></figure>
   5. Click **Load** to confirm and wait for the loading process to complete.
3. Repeat *step 2* to load all the tables into the same database.

## Get Snowflake credentials

## Connect Recurve to Snowflake


# Redshift setup

Recurve's Redshift connector enables you to seamlessly integrate your Amazon Redshift data warehouse as a destination for your analytics database. This guide walks you through establishing a secure connection using Redshift credentials, from initial setup, data preparation, to your first successful connection.

You'll learn how to:

* Set up a sample dataset in your Amazon Redshift cluster
* Establish a connection between Recurve and Redshift

## Prerequisites

* You already belong to a Recurve organization
* You have an AWS account with administrative access
* You have an existing Redshift cluster or permissions to create one

## Prepare sample dataset

To demonstrate the connetion process, we'll be using the `jaffle_shop` dataset — a fictional e-commerce store's data provided by the dbt community. This dataset offers a practical example of typical e-commerce data structures that mirror real-world scenarios.&#x20;

You can use the [jafgen](https://github.com/dbt-labs/jaffle-shop-generator) CLI tool generate synthetic data for any specified year range.

The dataset includes these tables:

* Customers (who place Orders)
* Orders (from those Customers)
* Products (the food and beverages the Orders contain)
* Order Items (of those Products)
* Supplies (needed for making those Products)
* Stores (where the Orders are placed and fulfilled)
* Tweets (Customers sometimes issue Tweets after placing an Order)

Or simply download the generated data below:

{% file src="/files/oYDfqEhOrOPCXZBLY5sJ" %}

## Create a Redshift cluster

Redshift cluster is the managed data warehouse solution of AWS. We'll be setting the cluster and S3 storage using AWS CloudFormation.

Follow these steps:

1. Sign in to your AWS Management Console as a root user or an IAM user depending on your level of access.
2. Navigate to the CloudFormation section to set up Redshift. AWS CloudFormation lets you create AWS resources using code instead of clicking through the AWS console. You can use a template file (in YAML or JSON) that describes your desired infrastructure. You can just click [**Create stack**](https://console.aws.amazon.com/cloudformation/home?region=us-east-1#/stacks/new?stackName=dbt-workshop\&templateURL=https://tpch-sample-data.s3.amazonaws.com/create-dbtworkshop-infr) and use the [create-dbtworkshop-infr](https://github.com/aws-samples/aws-modernization-with-dbtlabs/blob/main/resources/cloudformation/create-dbtworkshop-infr) template provided by the AWS-dbt community.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FH02MOOnL4k18C2iYpxEt%2FAWS_cloudformation_create_stack.png?alt=media&amp;token=30803d58-653b-4ff4-949b-358b96872f72" alt=""><figcaption></figcaption></figure>
3. Click **Next** for the next three steps. You leave the other options by default.
4. Submit the information and you should see the stack page displays CREATE\_IN\_PROGRESS status.
5. Once the stack creation is done (CREATE\_COMPLETE), switch to the **Outputs** tab to view the credentials. These credentials will be used to access Redshift data warehouse.
6. Now that Redshift cluster is set up via CloudFormation, you can navigate to the [Redshift dashboard](https://console.aws.amazon.com/redshiftv2/home#/dashboard) to confirm the change.&#x20;

   &#x20;

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FIgOlLzUL7BVinSCD2KSy%2FAWS_redshift_cluster.png?alt=media&amp;token=c4283b21-e044-4340-a9fd-d8eb6d3ec820" alt=""><figcaption></figcaption></figure>
7. Click on the cluster and select query data to access the query editor. Here we choose the **Query editor v2**. You might be asked to configure account. This is where you can use the credentials generated from stack creation:
   * Authentication (select Database username and password)
   * Database
   * User name
   * Password
8. Click **Create connection**.

## Load data

Now that the infrastructure is ready, we can start loading the data.

The CloudFormation stack already creates an S3 bucket, where we can upload the CSV files.

Follow these steps:

1. Navigate to the S3 dashboard and select the `dbt-data-lake-xxxx` bucket.

2. Click **Upload** > **Add files** and select all the CSV files of [the Jaffle Shop dataset](/getting-started/1.-set-up-a-connection/redshift-setup#prepare-sample-dataset). Click **Upload**.

3. Once the upload process is done, you can select each object and click **Copy S3 URI**. This URI will be later used to refer to these S3 objects in the query editor.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Fn2PgBnHuXRbuGRT5pber%2FAWS_S3_copy_S3_URI.png?alt=media&amp;token=1dfe4ec1-4a89-43c3-aeea-8b70470b354b" alt=""><figcaption></figcaption></figure>

4. Navigate back to the query editor, in a query tab, input and run the following script to create the database and table schemas:

<details>

<summary>Create schemas</summary>

```sql
create schema if not exists jaffle_shop;

-- create customers table
create table jaffle_shop.customers (
    id varchar(36),
    name varchar(100)
);

-- create items TABLE
create table jaffle_shop.items (
    id varchar(36),
    order_id varchar(36),
    sku varchar(10)
);

-- create stores table
create table jaffle_shop.stores (
    id varchar(36),
    name varchar(100),
    opened_at timestamp,
    tax_rate decimal(5,4)
);

-- create products table
create table jaffle_shop.products (
    sku varchar(50),
    name varchar(100),
    type varchar(50),
    price decimal(10,2),
    description text
);

-- create orders table
create table jaffle_shop.orders (
    id varchar(36),
    customer varchar(36),
    ordered_at timestamp,
    store_id varchar(36),
    subtotal decimal(10,2),
    tax_paid decimal(10,2),
    order_total decimal(10,2)
);

-- create supplies table
create table jaffle_shop.supplies (
    id varchar(36),
    name varchar(100),
    cost decimal(10,2),
    perishable boolean,
    sku varchar(50)
);

-- create tweets table
create table jaffle_shop.tweets (
    id varchar(36),
    user_id varchar(36),
    tweeted_at timestamp,
    content varchar(1000)
);
```

</details>

5. Next we need to populate the tables with data from the S3 bucket. Open another query tab, input and run the script below. Replace the S3 URIs and IAM role with your own.

<details>

<summary>Populate data</summary>

```sql
-- Load customers data
copy jaffle_shop.customers(id, name)
from 's3://dbt-data-lake-xxxx/raw_customers.csv'
iam_role 'arn:aws:iam::XXXXXXXXXX:role/RoleName'
region 'us-east-1'
delimiter ','
ignoreheader 1
acceptinvchars;

-- Load stores data
copy jaffle_shop.stores(id,name,opened_at,tax_rate)
from 's3://dbt-data-lake-xxxx/raw_stores.csv'
iam_role 'arn:aws:iam::XXXXXXXXXX:role/RoleName'
region 'us-east-1'
delimiter ','
timeformat 'YYYY-MM-DDTHH:MI:SS'
ignoreheader 1
acceptinvchars;

-- Load products data
copy jaffle_shop.products(sku,name,type,price,description)
from 's3://dbt-data-lake-xxxx/raw_products.csv'
iam_role 'arn:aws:iam::XXXXXXXXXX:role/RoleName'
region 'us-east-1'
delimiter ','
ignoreheader 1
acceptinvchars
CSV QUOTE '"';

-- Load orders data
copy jaffle_shop.orders(id,customer,ordered_at,store_id,subtotal,tax_paid,order_total)
from 's3://dbt-data-lake-xxxx/raw_orders.csv'
iam_role 'arn:aws:iam::XXXXXXXXXX:role/RoleName'
region 'us-east-1'
delimiter ','
timeformat 'YYYY-MM-DDTHH:MI:SS'
ignoreheader 1
acceptinvchars;

-- Load items data
copy jaffle_shop.items(id,order_id,sku)
from 's3://dbt-data-lake-xxxx/raw_items.csv'
iam_role 'arn:aws:iam::XXXXXXXXXX:role/RoleName'
region 'us-east-1'
delimiter ','
ignoreheader 1
acceptinvchars;

-- Load supplies data
copy jaffle_shop.supplies(id,name,cost,perishable,sku)
from 's3://dbt-data-lake-xxxx/raw_supplies.csv'
iam_role 'arn:aws:iam::XXXXXXXXXX:role/RoleName'
region 'us-east-1'
delimiter ','
ignoreheader 1
acceptinvchars;

-- Load tweets data
copy jaffle_shop.tweets(id,user_id,tweeted_at,content)
from 's3://dbt-data-lake-xxxx/raw_tweets.csv'
iam_role 'arn:aws:iam::XXXXXXXXXX:role/RoleName'
delimiter ','
timeformat 'YYYY-MM-DDTHH:MI:SS'
ignoreheader 1
acceptinvchars
CSV QUOTE '"';
```

</details>

6. You can verify that the data is loaded successfully by running queries like:

```sql
select * from jaffle_shop.customers;
select * from jaffle_shop.stores;
select * from jaffle_shop.items;
```

## Connect Recurve to Redshift


# 2. Create a project

Once you've configured your connections in **Destinations**, the next step is to create a project. A project in ReOrc serves as a collaborative workspace where your team can organize and manage all data workflows, models, and transformations relevant to a specific data development goal.

Here you also select the connections created in the previous step and assign them to your project as project connection. This setup defines the data sources needed for building your data transformation workflows.

## About project connections

Project connections are data connections linked to a specific project in ReOrc. For each project connection, you can define the connection type and specify separate target databases for **development** and **production** environments. This setup provides smooth transitions when promoting changes from development to production.

While a project can have multiple project connections, only one connection can be set as the primary database at a time. This primary database, also called the **analytics database**, is optimized for reading and aggregating data in large volumes. All models in your project will be executed and built under the analytics database.

## Set up a project

Follow these steps:

1. From ReOrc left sidebar, select **Data development** -> **Data design hub**.

   This opens up the **Data design hub**, where all projects are listed.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F0gmwOQIxW1FOybZWKJyV%2FRecurve_project_data_design_hub.png?alt=media&amp;token=5ce4a6a9-6581-4233-b974-b4c9deb0f800" alt=""><figcaption></figcaption></figure>
2. Click **+Add Project**.
3. Provide the necessary information for the new project.

{% tabs %}
{% tab title="1. General information" %}
Provide the name, tags, and description to help organize your project.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FDg12emioLAfUUWFclzEF%2FRecurve_create_project_1.png?alt=media&amp;token=bd244e33-9860-48b2-b3d2-a25ab7367629" alt=""><figcaption></figcaption></figure>
{% endtab %}

{% tab title="2. Set up environments" %}
A project must have a pair of development and production environments.

{% hint style="info" %}
In the current beta release, environment setup is limited to the default development and production environments only.
{% endhint %}

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FuRjBt4WkoSUnpmm7Evm5%2FRecurve_create_project_2.png?alt=media&amp;token=fda424cc-09bf-41b0-8f66-13e8a0358136" alt=""><figcaption></figcaption></figure>
{% endtab %}

{% tab title="3. Project connections" %}
Click **+Add** and specify the connection for the project. Use the connection that you set up in [1. Set up a connection](/getting-started/1.-set-up-a-connection).

Only development environment connection is required.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Ffl5YNnWIOKiCh852ICHU%2FRecurve_create_a_project_3.png?alt=media&amp;token=45acf7d2-d11e-4de1-9a48-4a2ebe267a0f" alt=""><figcaption></figcaption></figure>
{% endtab %}

{% tab title="Set analytics database" %}
Next, you need to check the connection as the **analytics database**:

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F1A2X7ien3vHMPOOCxYuj%2FRecurve_create_project_3_set_analytics_database.png?alt=media&amp;token=b6c4a9df-9361-4b9f-91f8-53a834ffa370" alt=""><figcaption></figcaption></figure>

{% endtab %}
{% endtabs %}

4. Click **Create**.

The new project will be displayed in the **Data development** dashboard.


# 3. Create data models

This section introduces the core concepts of data modeling. You'll learn how to create a simple data transformation use case with ReOrc.

## Assets in ReOrc

Assets are the building blocks of your data workflow in ReOrc. You can think of assets as the essential components you'll create and manage throughout your data transformation process. Each type of asset serves a specific purpose, working together to turn your raw data into valuable insights.

In **Data modeling**, you mainly work with these types of assets:

* **Sources**: references to your raw data, allowing you to connect and document your data origins.
* **Models**: queries that process this data, applying transformations to create structured, analytics-ready datasets.
* **Jinja macros and variables**: Jinja templating artefacts that add programming logic to SQL, allowing you to write more dynamic and maintainable transformations.

## Data modeling process

The data modeling process in ReOrc follows a logical flow that helps you build and validate your transformation workflow.

1. **Define your sources**: Start by defining sources that represent your raw data tables. Sources help you describe and document the origins of your data.
2. **Create data models**: With your sources defined, create data models to transform your raw data into useful analytics datasets. Each model represents a specific transformation step that builds on previous steps.
3. **Configure materialization**: Specify how the results of your models will be materialized in your data warehouse.
4. **Add data tests**: Add data tests to the models to ensure they're working correctly. These tests associated with a model are automatically executed every time the model is successfully built.

Your development cycle should include these steps to ensure that transformations work properly before applying them to production data.&#x20;

## Prerequisites

The following walkthrough uses the `jaffle_shop` dataset (a fictional e-commerce store) provided by the dbt Community. You can follow the guide in this repository to generate the data and load it into your target database: [jaffle-shop-generator](https://github.com/dbt-labs/jaffle-shop-generator).

## Walkthrough

Let's go through the data modeling process of ReOrc with hands-on steps.

To begin, from the **Data development** dashboard, open the project that you've created. By default, ReOrc navigates you to the **Design** section, where all transformation activities happen.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FpBMarNsJBxTjY6EVnAH5%2FRecurve_project_data_section.png?alt=media&amp;token=7cc32c3c-6af7-4c36-8cfe-78e3889eb40b" alt=""><figcaption></figcaption></figure>

### Define your sources

Follow these steps:

1. In the **Models** tab, click on the **+** icon and select **Add source**.&#x20;
2. In the opened modal:
   1. Select the connection type.&#x20;
   2. Select the target connection. This is the project connection that you've set up in [2. Create a project](/getting-started/2.-create-a-project)
3. Click **Next**. ReOrc then displays all the tables available from the target connection.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FYqM2IyzMSSNa7D23digG%2FRecurve_add_source_select_tables.png?alt=media&amp;token=de8959e9-b741-4ba0-8143-f343e1172e6a" alt=""><figcaption><p>Select tables from a connection</p></figcaption></figure>

4. Select the desired raw tables or models.&#x20;

   Here we select all tables organized in the `jaffle_shop` schema.

<details>

<summary>jaffle_shop tables</summary>

The `jaffle_shop` schema includes these tables:

* Customers (who place Orders)
* Orders (from those Customers)
* Products (the food and beverages the Orders contain)
* Items (of those Products)
* Supplies (needed for making those Products)
* Stores (where the Orders are placed and fulfilled)

</details>

5. Click **Add source**.

The selected tables will then be added to the **Sources** folder and grouped by the schema name.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F3ZNHgjxhVpArYQmI52tf%2FRecurve_added_sources.png?alt=media&amp;token=a0de20f3-0518-418b-8dfb-def68ff4735d" alt=""><figcaption></figcaption></figure>

### Create data models

To demonstrate the dynamics and modularity of data models, here we're going to create three models:

{% tabs %}
{% tab title="stg\_customers" %}
This stage model standardizes customer data by selecting relevant fields (`customer_id`, `first_name`, and `last_name`) from the raw `customers` table.&#x20;

This uses the Jinja  [`{{ source() }}`](/data-modeling/jinja-templating) function to reference the raw tables defined in the previous section.

```sql
select 
    id as customer_id,
    name as customer_name

from {{ source('jaffle_shop', 'raw_customers') }}
```

{% endtab %}

{% tab title="stg\_orders" %}
Similar to `stg_customers`, this stage model standardizes order data by selecting and renaming relevant fields (`order_id`, `customer_id`, `order_date`, `status`) from the raw `orders` table.

```sql
select 
    id as order_id,
    customer as customer_id,
    ordered_at as order_date

from {{ source("jaffle_shop", "raw_orders") }}
```

{% endtab %}

{% tab title="customers" %}
This model consolidates customer data with order history.

Here we use the [`{{ ref() }}`](/data-modeling/jinja-templating) function to make reference to the two staging models.

{% code overflow="wrap" %}

```sql
-- Reference the staged data (stg_customers and stg_orders) to gather customer information.

with customers as (

    select * from {{ ref('stg_customers') }}

),

orders as (

    select * from {{ ref('stg_orders') }}

),

-- Aggregate the order data to calculate metrics per customer

customer_orders as (

    select
        customer_id,

        min(order_date) as first_order_date,
        max(order_date) as most_recent_order_date,
        count(order_id) as number_of_orders

    from orders

    group by 1

),

-- Join aggregated data with the customer information to produce details about each customer and their order history

final as (

    select
        customers.customer_id,
        customers.customer_name,
        customer_orders.first_order_date,
        customer_orders.most_recent_order_date,
        coalesce(customer_orders.number_of_orders, 0) as number_of_orders

    from customers

    left join customer_orders using (customer_id)

)

select * from final
```

{% endcode %}
{% endtab %}
{% endtabs %}

Follow these steps to create each model:

1. In the **Models** tab, click on the **+** icon and select **New SQL model**.
2. Provide the model name and click **Create**.

   The new model is then placed in the **Models** folder.
3. Open the model in the editor and paste in the query.&#x20;

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FhbxmHe7sgwMGc4LmA5WD%2FRecurve_query_pasted.png?alt=media&amp;token=9c820f46-0734-4309-9ca1-17b166fe5812" alt=""><figcaption></figcaption></figure>
4. Click **Save** to confirm the changes.
5. Click **Preview** to view the query output in the **Result** tab.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FniawLrtX2kYKydHZnxOv%2FRecurve_preview_results.png?alt=media&amp;token=c172e310-cf2b-4caa-a339-2f735f8d8816" alt=""><figcaption></figcaption></figure>
6. Perform the steps above to create the other two models.

Now that we've created two staging models that standardize raw data, and one model that aggregates and consolidates the results, we can view them in **Data linage** to better understand the relationship.

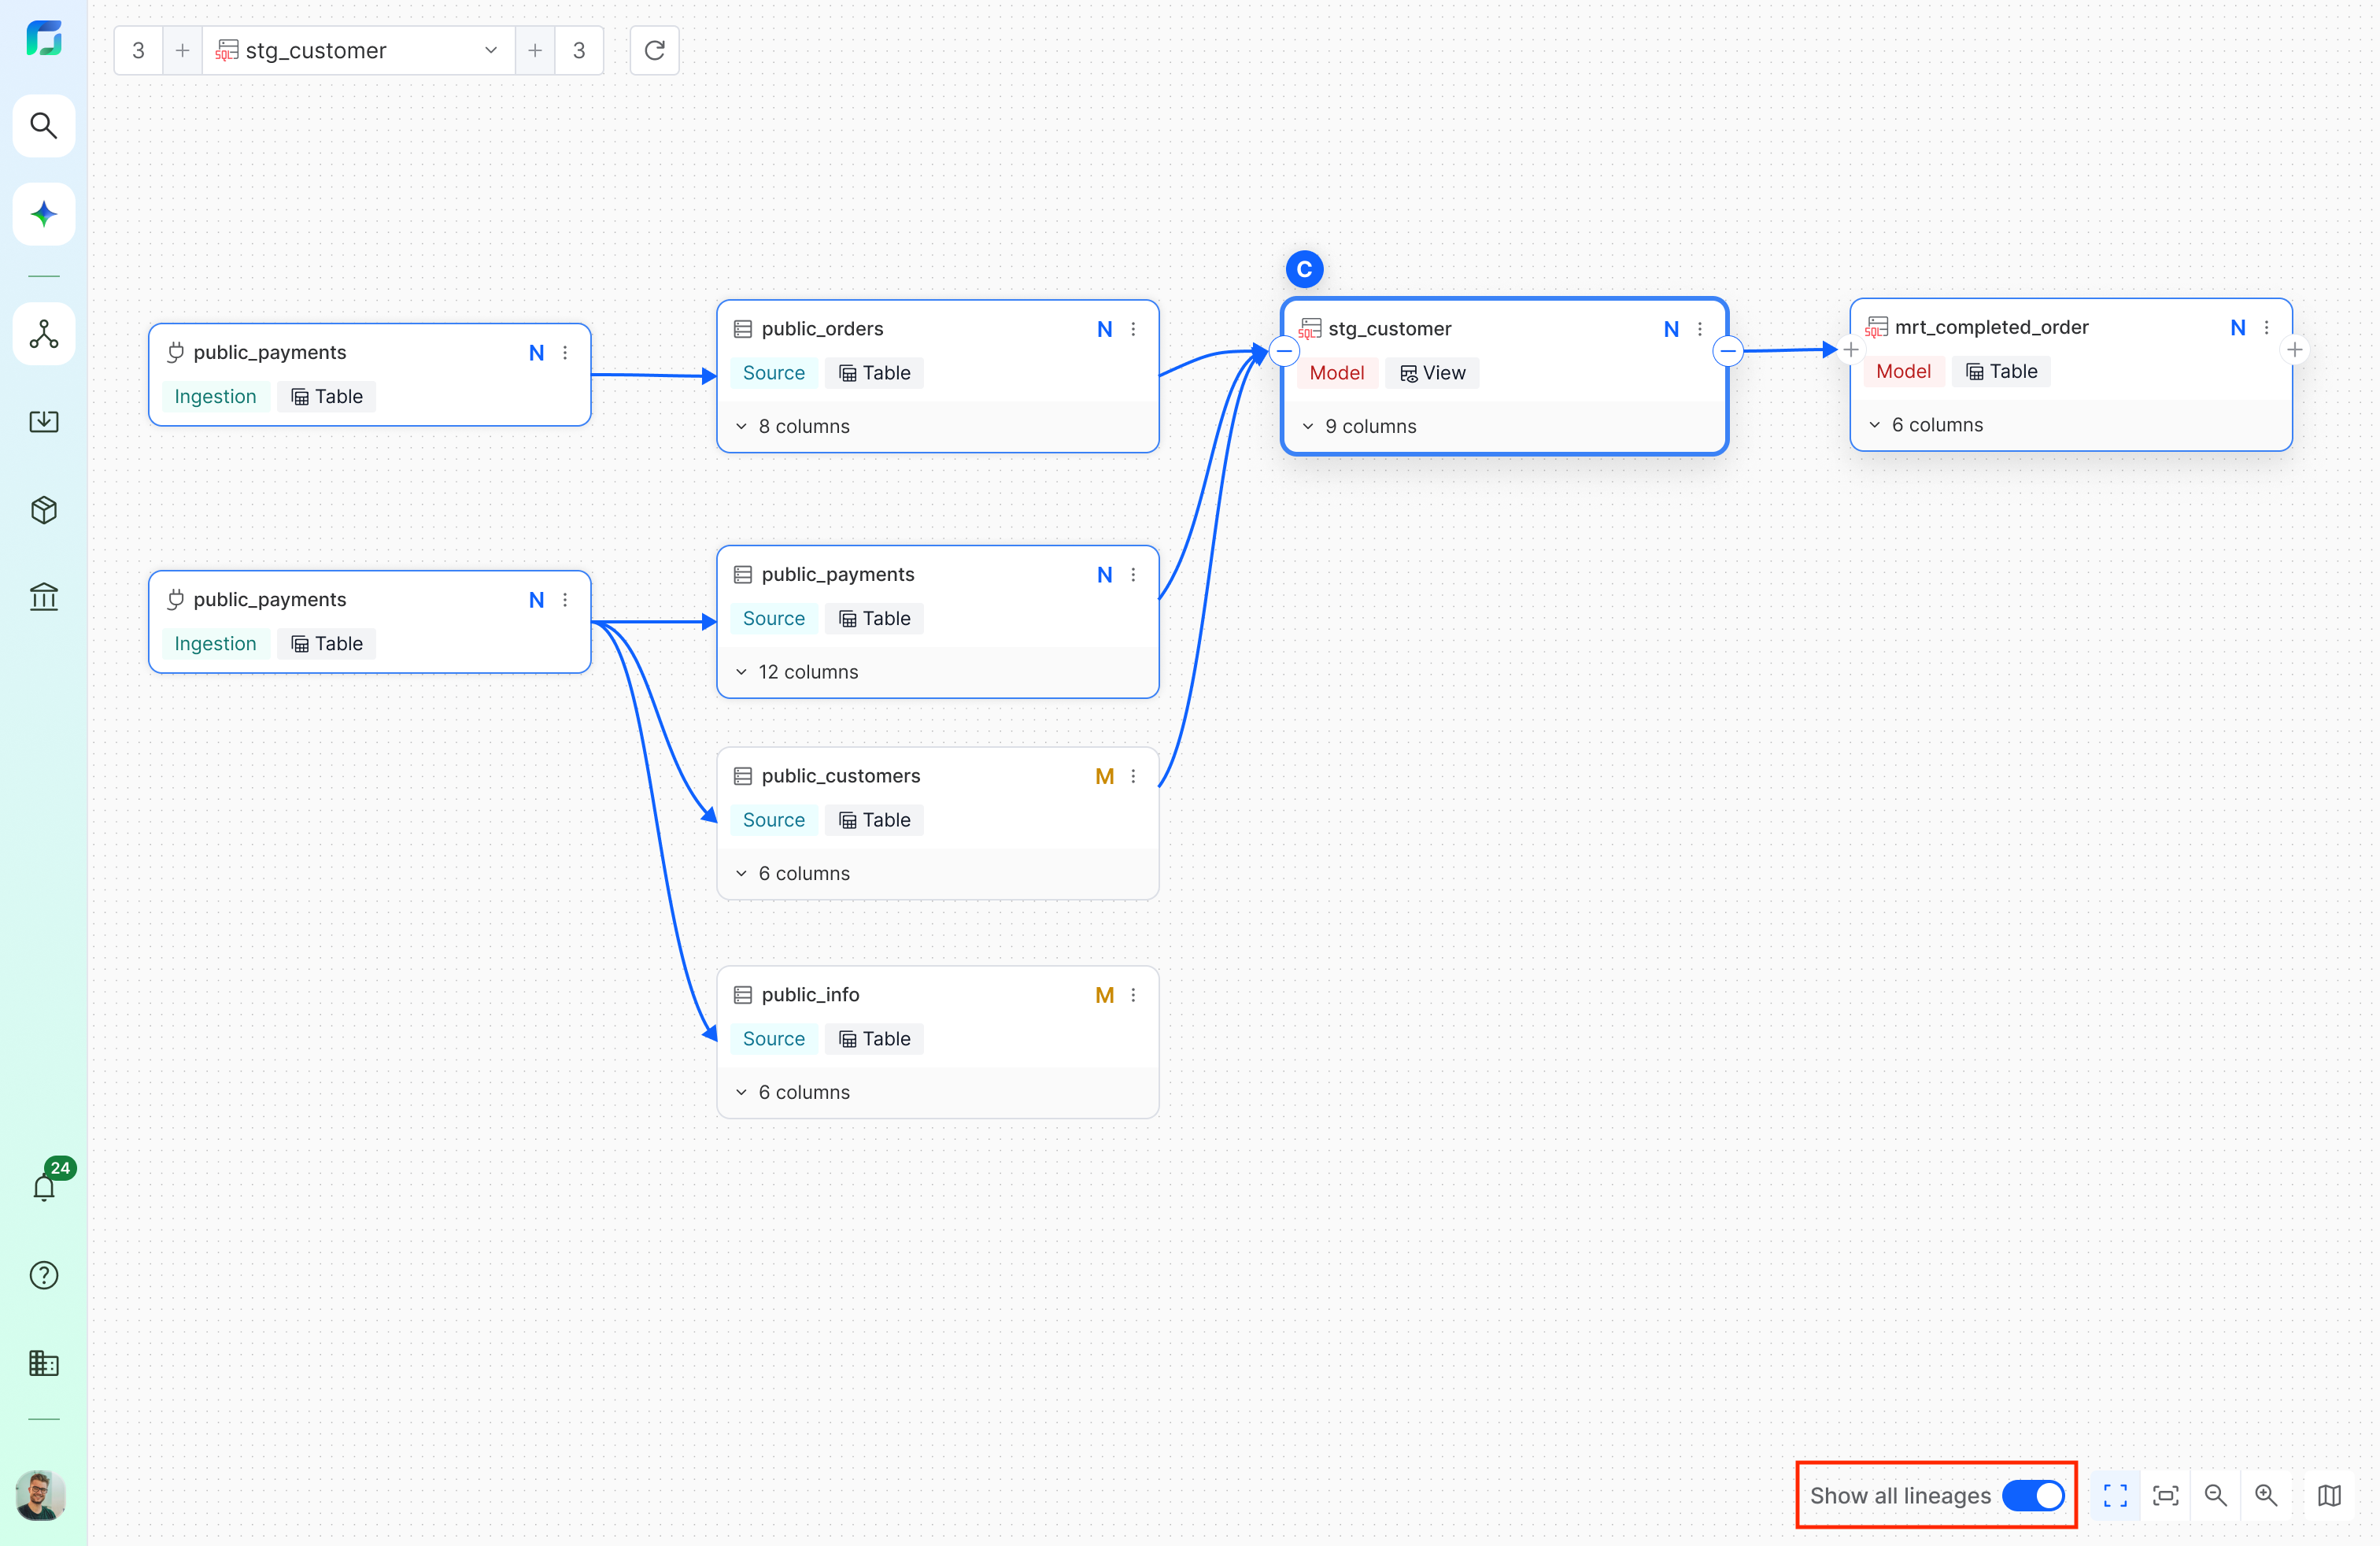
Open a model and toggle on the **Lineage view** option. This will display a DAG (directed acyclic graph) showing the relationship of assets, from raw data to the final downstream model.

Data lineage is achieved through the use of `source()` and `ref()` functions, which automatically track dependencies of assets.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FpsIvZUoVwmAM4Gn3rBJP%2FRecurve_customers_data_lineage.png?alt=media&amp;token=64944e39-840d-4354-baf6-90bf2da86d99" alt=""><figcaption></figcaption></figure>

### Configure materialization

You can specifically configure how a model is materialized within your warehouse.

By default, all models have the **table** materialization.

Follow these steps:

1. Open a model in the editor.
2. Click on ![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FG92nawkXZhXwxMEsVCya%2FRecurve_info_button.png?alt=media\&token=bf4cf02e-a67b-4898-8975-211410cbfff4).
3. In the **Materialization** field, select a materialization option.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FhqsVLRnpiPJWqaORNnQk%2FRecurve_change_model_materialization.png?alt=media&amp;token=f3532594-063f-4695-b847-218b847fcdf0" alt=""><figcaption></figcaption></figure>

Continuing with our three example models, we can materialize the staging models as views to ensure they reflect the latest source data and minimize storage costs. On the other hand, the consolidated model can be materialized as table as it is the final model and is queried more frequently.

### Add data tests

{% hint style="info" %}
**Coming soon:** Data tests will be available in the next release.
{% endhint %}

Data tests are simply SQL queries that return failing records, based on the condition that you set. These tests validate the correctness of the transformed data and ensure results from the model meet predefined standards.&#x20;

ReOrc provides a list of built-in tests that you can quickly add to your models.

To add a test to a model, follow these steps:

1. Open a model in the editor.

2. Switch to the **Test cases** tab.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FG6bb6oAyM73FJWxecoaV%2FRecurve_test_case_tab.png?alt=media&amp;token=765bb74b-b078-482e-b6ad-bbea78f06dde" alt=""><figcaption></figcaption></figure>

3. Click **+Add new**.

4. Select a template and specify the values.

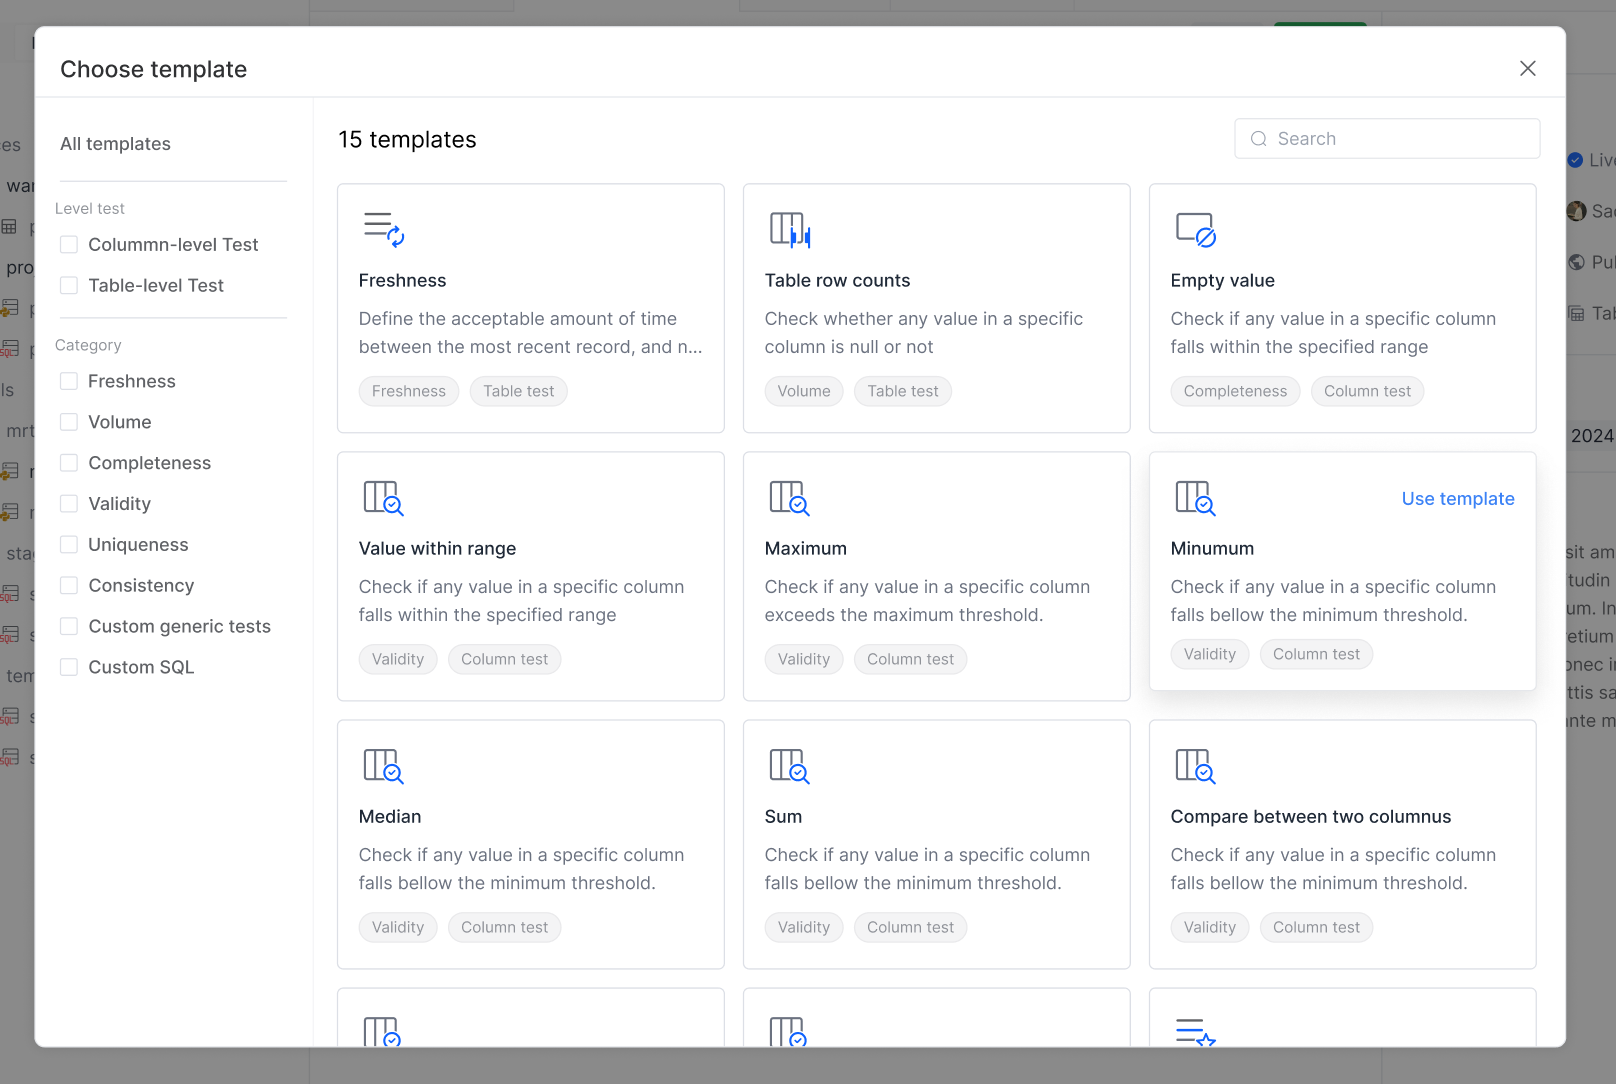
   For example, with the `stg_orders` model, we can add the Empty Value test to verify that no `null` value exists in the date column.&#x20;

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Ft2m4OIUNM7eYPhisuH2S%2FRecurve_not_null_check.png?alt=media&amp;token=c4ed2f40-188e-40b6-8f1e-e264eca4b31d" alt=""><figcaption></figcaption></figure>

5. Click **Add**.

The new test is added to the model's test case list and is executed every time the model runs in the console or as part of a pipeline.


# 4. Build models in console

ReOrc Console provides a convenient way to run and troubleshoot executable assets like models and pipelines.

Before publishing and deploying the changes to production, you can verify your data models and pipelines by executing sample runs through the console against the ***development*** environment.

The console builds the models and automatically executes all associated data tests. You can inspect the generated data and test results to iteratively improve the transformations.

## Use the console

Let's build the models and run the tests that we've established in the previous step.

1. In **Design**, at the bottom toolbar, click on **Console**.

   This opens up the console section.
2. Click **Choose assets or pipeline**.
3. In the opened pop-up, choose **Model** and specify the models.

   We can select the three models to verify them all.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Fs97duiZYcnnG2ZcSM4OY%2FRecurve_console_pop_up.png?alt=media&amp;token=62221050-95ef-4cff-b3af-ec9fc10cc5b6" alt=""><figcaption></figcaption></figure>
4. Click **Save**.
5. Click **Run**.

   This will run the models as separate tasks, in the order determined by their dependencies.

## Execution Result

The tasks will take a moment to run. You can monitor the execution status of each task corresponding to its model.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FL2gyZ2odm0TAnSoEi82v%2FRecurve_console_results.png?alt=media&amp;token=3b310c0d-222b-43e3-9675-1d244246f2f4" alt=""><figcaption></figcaption></figure>

If there is any error, click on the task to view the detailed log. In **Run logs** tab, you can check for the error log of the model build process and the test case results.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FOJMZ5CdddjvA65kix6NJ%2Fimage.png?alt=media&amp;token=6bb45bb6-85aa-4fa1-b1ef-8418aaed9025" alt=""><figcaption></figcaption></figure>


# 5. Set up a pipeline

After you've done creating and polishing the models, you can finally wrap the workflow in a pipeline and create a job to schedule the execution of the workflow. This ensures your transformations are reproducible and reliable every time they run.

## Publish the models

Before creating a pipeline from the models, you need to publish them. Publishing models or any assets before using them in pipelines ensures reproducibility, makes dependencies clear, and enables parallel development across teams.

Open each model in the editor and follow these steps:

1. In the top-right corner, click **Publish**.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F3RomrBSYKzpD9tTqy2C7%2FRecurve_editor_publish_button.png?alt=media&amp;token=a68205d1-2209-4608-ae98-6315504c21d1" alt=""><figcaption></figcaption></figure>

2. Provide a version number and description.

   For the first publish, we'll leave it as default.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FpK3qc1XpsrK9fsmVftHk%2FRecurve_publish_model_pop_up.png?alt=media&amp;token=e074cc6d-b7d1-4191-986a-d5d183e9393e" alt="" width="375"><figcaption></figcaption></figure>

3. Click **Publish**.

The models are now ready for use in a pipeline.

## Create a pipeline

Follow these steps:

1. Switch to the **Pipelines** tab.
2. Click on the **+** icon and select **Creating modeling pipeline.**

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F6lMol4uwSTo3azdCC3qH%2FRecurve_create_new_modeling_pipeline.png?alt=media&amp;token=594355a3-6d4d-4c9c-bf4e-8e2c3625fc2a" alt=""><figcaption></figcaption></figure>
3. Provide the name for your pipeline.
4. Select the models that the pipeline should contain.&#x20;

   Here we add the three models set up in the previous step.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FylSgQ8DjjbF5SCDVmRvI%2FRecurve_modeling_pipeline_customers.png?alt=media&amp;token=8dc1593b-baba-4736-a35f-7979f1f3fda4" alt=""><figcaption></figcaption></figure>
5. Click **Confirm**.

   The new modeling pipeline is then added under the **Models** folder and presented in the DAG view.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FQmWsCT5oYJKC7zTqnTtO%2FRecurve_modeling_pipeline_example.png?alt=media&amp;token=47f085df-8dd2-4597-ada6-75e8e6ae7b43" alt=""><figcaption></figcaption></figure>
6. Click **Publish**.&#x20;

## Create a job

Now that the pipeline is created and published, you can create a job to schedule execution time. Follow these steps:

1. Open the pipeline that you've created.
2. Switch to the **Jobs** tab and click **+ Create a job**.
3. Provide the configuration for the job.

{% tabs %}
{% tab title="1. Detail" %}
Provide the name, select the target environment, and customize the associated model variables.

Since we've executed and verified the models using the console. We now can select the **Production** environment to run the transform against the production database.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FazAq7cfd8fRm52xKr549%2FRecurve_job_create_step_1.png?alt=media&amp;token=3a650448-d753-4d57-b8dc-40e1d85a3812" alt=""><figcaption></figcaption></figure>
{% endtab %}

{% tab title="2. Schedule" %}
Provide the time schedule for the job and the trigger type:

* Standard setup: trigger the run at a specific time between certain intervals.
* Advanced setup: specify the schedule in crontab format, for those familiar with the `cron` scheduler. See: [Cron](https://en.wikipedia.org/wiki/Cron).
* Manually trigger: no scheduling and can be manually triggered in the **Pipeline Health** dashboard. See: [Pipeline health](/health-tracking/pipeline-health).

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FFOdoSpqfNNQXp3fRQTNc%2FRecurve_job_creation_step_2.png?alt=media&amp;token=2dbb4f0f-eed4-4ae6-b5a7-4b0f483f7fb0" alt=""><figcaption></figcaption></figure>
{% endtab %}

{% tab title="3. Notification" %}
Here you can configure notifications on job failure. By default, notifications are sent by email.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FoEuJEgOL0SNyD6fBuk00%2FRecurve_job_creation_step_3.png?alt=media&amp;token=6cd60466-deb6-4a65-b9cc-2b2858d40ae4" alt=""><figcaption></figcaption></figure>
{% endtab %}
{% endtabs %}

4. Click **Create**.&#x20;

The new job will be displayed in the **Jobs** section. ReOrc will execute the job at the scheduled time.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FUM84u0d6dK1N6jcxf26Y%2FRecurve_pipeline_jobs_tab_created_job.png?alt=media&amp;token=9c3da3fa-c7ac-48eb-91ee-9872d4f69399" alt=""><figcaption></figcaption></figure>

You can the execution status and progress of the job in the [**Pipeline health** dashboard. ](/health-tracking/pipeline-health)

{% hint style="success" %}
Congratulations! You have completed building a data workflow with ReOrc.
{% endhint %}

For the next step, you can explore in detail each feature and module:

<table data-view="cards"><thead><tr><th></th><th></th><th></th><th data-hidden data-card-target data-type="content-ref"></th></tr></thead><tbody><tr><td><strong>Connections</strong></td><td>Learn about the available connections</td><td></td><td><a href="/connections/destinations">Connections</a></td></tr><tr><td><strong>Data modeling</strong></td><td>Learn about the core assets in data modeling</td><td></td><td><a href="/data-modeling/overview">Overview</a></td></tr><tr><td><strong>Health tracking</strong></td><td>Explore the health tracking dashboard</td><td></td><td><a href="/health-tracking/pipeline-health">Pipeline health</a></td></tr></tbody></table>


# Destinations

The Destination section contains all the connections to data sources that you can use in your project. ReOrc provides a wide range of connectors to data sources for the flexible needs and objectives for your businesses.

Each data source / provider can require specific authentication method and parameters.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FLxwU5ZwK6KO9JAVf6oc3%2FRecurve_all_destinations.png?alt=media&amp;token=7d743033-4930-4f29-8e6f-5d7317d217fa" alt=""><figcaption></figcaption></figure>

Below is the list of available data sources.

## Data warehouses

* Azure Synapse
* Big Query
* Hive
* Impala

## Databases

* ClickHouse
* Apache Doris
* ElasticSearch
* MongoDB
* Microsoft SQL Server
* MySQL
* Phoenix
* PostgreSQL
* Redshift
* Spark
* StarRocks
* TiDB

## Data storages

* Azure Blob
* FTP
* Google Cloud Storage
* Aliyun OSS
* ownCloud
* Amazon S3
* SFTP
* Tencent COS

## How the connections work

In [ReOrc architecture](/set-up-and-deployment), ReOrc agent is the component that receives instructions from the Control Plane and executes the corresponding tasks in the Data Plane. This also involves registering and maintaining the connections to data sources.

When you set up connections within your organization, you direct the agent to establish secure links to your data sources. Therefore, all data transformations and persistence occur directly between the agent and your data sources.

## Database permissions

When setting up a database connection in ReOrc, you must configure it with user credentials that have sufficient permissions. Each data provider may have a different approach to granting permissions, but generally, the database user must have:

* **Read permissions** (SELECT): To access and query source data tables.
* **Write permissions** (CREATE, INSERT, UPDATE): To save transformed data and model results.

Ensure these permissions are granted specifically for the target schema where you plan to query and transform data.


# Google Service Account

A Google Service Account is a special type of Google account designed for applications and services to interact with Google Cloud resources without human intervention. Unlike your regular user accounts, service accounts are used in machine-to-machine communication, allowing applications to authenticate and authorize themselves when accessing Google APIs and services.

ReOrc uses Google service accounts to interact with various Google Cloud storage solutions. This enables connections to BigQuery, Google Sheets, and Google Cloud Storage for data loading and management operations.

This guide shows you how to set up a Google Service Account and create a key to for use in ReOrc.

## Prerequisites

* You've already created a [Google Cloud Project](https://console.cloud.google.com/).

## Set up a service account

Follow these steps:

1. Go to the [Service Accounts](https://console.cloud.google.com/projectselector2/iam-admin/serviceaccounts) page and select your project.
2. Click **+ Create Service Account**.
3. Enter the service account name and the description, then click **Create And Continue**.
4. Assign a role to your service account. Here we select **Owner** to provide sufficient permisisons for loading and dumping data in services. Then click **Continue**.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FQQVxIuMqnCCqtGIBqtmO%2FGCP_create_service_account_owner_role.png?alt=media&amp;token=b441d07b-f116-4bff-83dc-945e3423de19" alt="" width="375"><figcaption></figcaption></figure>
5. Click **Done**.&#x20;

## Generate a service account key

Follow these steps:

1. Go to [APIs & Services / Credentials](https://console.cloud.google.com/apis/credentials), locate and click on the email of the account you just created.
2. Switch to the **Keys** tab, then click **Add Key > Create new key**.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F9Aw6ZScrQk0aRRE0CI6T%2FGCP_create_key.png?alt=media&amp;token=47d59d65-b63d-4f15-991e-2f366fcaf198" alt="" width="563"><figcaption></figcaption></figure>
3. &#x20;In the opened dialog, select JSON as the key type and click **Create**. This generates and downloads a JSON file containing the authentication credentials.

## Configure Google Service Account in ReOrc

You can now use the credentials in the JSON file to authenticate from ReOrc. Follow these steps:

1. Log in to your ReOrc organization and go to **Destinations.**
2. Click **+ Create Destination**.
3. Select *Google Service Account* and click **Set up**.
4. Fill in the required fields with using the information from the download JSON file.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FfiNZq6RoKiSFIooHMIfh%2FRecurve_google_service_account.png?alt=media&amp;token=eac7bc8f-b926-4558-b995-a5f53da71552" alt="" width="563"><figcaption></figcaption></figure>
5. Test the connection in an environment.
6. After the connection is successfully tested, click **Create Destination**.


# Integrations

Recurve allows you to integrate with third-party services to set up notifications upon pipeline job failure:

* [Slack](/connections/integrations/slack)


# Slack

You can create a Slack app and integrate with ReOrc to send notifications to your Slack workspace upon certain pipeline execution event, such as job completion or failure.

ReOrc uses Slack APIs and bot authentication token to connect with your Slack app. This allows you to flexibly select the channels and users to send the notifications.

## Create a Slack app

1. Go to the [Slack API page](https://api.slack.com/apps) and click **Create New App**.
2. Select a creation method: From a manifest or From scratch.

   For a quick setup, select **From a manifest**.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FbmKgUahnXBv66j4b96Ju%2FSlack_create_app_from_manifest.png?alt=media&amp;token=09ee5dd9-99fd-4873-98f4-8ced7f3dfa47" alt=""><figcaption></figcaption></figure>
3. Select the workspace to install the app and click **Next**.
4. Input the manifest content.&#x20;

   This manifest provides the complete description of the app.&#x20;

```yaml
display_information:
  name: ReOrc Notifications
features:
  bot_user:
    display_name: ReOrc Notifications
    always_online: true
oauth_config:
  scopes:
    bot:
      - channels:manage
      - channels:read
      - chat:write
      - chat:write.public
      - groups:read
      - groups:write
      - im:write
      - mpim:read
      - mpim:write
      - users:read
      - users:read.email
```

5. Review the scope and click **Create**.

## Install the app to workspace

Once you've created the app, you need to install it to your workspace.&#x20;

1. Open the app in Slack site, in **Install App**, click on **Install to \<workspace name>**.&#x20;
2. In the opened confirmation page, click **Allow**.

   This will install the app to your workspace and create a **Bot User OAuth Token** which you can use to authenticate the app in ReOrc.

## Bot User OAuth Token

After installing the app to the workspace, Slack will navigate you back to the **Install App** section. Here under **Bot User OAuth Token**, you can find the generated bot user authentication token. You need to copy this token to use in ReOrc.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FS5Jntuf8KECx2SmiqXsU%2FSlack_bot_token_created.png?alt=media&amp;token=f236b544-b70f-48ba-9dda-440a70fe0e19" alt=""><figcaption></figcaption></figure>

## Configure Slack integration

1. In your ReOrc organization, go to **Connections** > **Integrations**, locate Slack option and click **Connect**.
2. Input the bot authentication token that you copied and click **Confirm**.

   ReOrc will try to authenticate the app.

## Add Slack notification to jobs

With the Slack app integrated, you can select the Slack option as notification destination for a job execution.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FHTh8lk7so37lWl2CRCNq%2FRecurve_job_notification_slack.png?alt=media&amp;token=79f7134f-c0b8-4bf1-87c0-87c74dfd9321" alt=""><figcaption></figcaption></figure>

Upon job failure, ReOrc will send the notifications to the designated Slack user or channel.


# Feishu

If your organization uses Feishu for communication, you can integrate with the Feishu bot to send notifications upon job completion or failure.

## Create Feishu bot

You can follow this guide from Feishu documentation to create a bot and retrieve the bot credentials (Bot App ID and Feishu Bot App Secret):  [Send messages via Feishu bot](https://www.feishu.cn/hc/en-US/articles/348229340087-send-messages-via-feishu-bot).

## Configure Feishu integration

1. In your Recurve organization, go to **Connections** > **Integrations**, locate the Feishu option and click **Connect**.
2. Input Feishu Bot App ID and Feishu Bot App Secret, then click **Confirm**.

   Recurve will try to authenticate the bot.

## Add notification to jobs

With the bot integrated, you can select the Feishu option as notification destination for a job execution.


# Project connections

Project connections are data connections linked to a specific project in Recurve. For each project connection, you can define the connection type and specify separate target databases for **development** and **production** environments. This setup provides smooth transitions when promoting changes from development to production.

While a project can have multiple project connections, only one connection can be set as the primary database at a time. This primary database, also called the **analytics database**, is optimized for reading and aggregating data in large volumes. All models in your project will be executed and built under the analytics database.

This guide shows you how to create a project connection and set the analytics database.

## Create a project connection

Follow these steps:

1. Open your project and go to **Settings** > **Data connections**.
2. In the **Define connection** section, click **+ Add connection**.
3. Provide the connection name and the connection type for development and production environments.

   Note that the connection type must be the same for both development and production environments.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FHIWIkFXXOaIn11LlpTSo%2FRecurve_project_creation_3_project_connection.png?alt=media&amp;token=48bac091-769a-4360-8e3c-08fef90a1a8a" alt=""><figcaption></figcaption></figure>
4. Click **Create**.

## Set analytics database

To set connection as the analytics database, follow these steps:

1. Open your project and go to **Settings** > **Data connections.**
2. Click on the option button of the desired connection.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FdvvlGNSbv3BdodELE8DN%2FRecurve_set_analytics_database_confirm.png?alt=media&amp;token=22f62532-a329-4fe4-8499-fa3b4d181985" alt=""><figcaption></figcaption></figure>
3. In the opened pop-up, click **Confirm**.


# Overview

A introduction to the data modeling module of ReOrc.

Transforming data is one of the crucial steps in building an effective data pipeline. At this stage, raw data, loaded from a centralized database or data warehouse, is converted into a desired structure and format, enabling analysts to extract valuable insights that serve business needs.

Modern data transformation tools like [*dbt*](https://www.getdbt.com/) (Data Build Tool) are becoming more efficient by applying software engineering principles to analytics. Such principles include modular SQL scripting, version control, validation, and integration with orchestration platforms. This approach makes data transformation more reliable and scalable.

ReOrc adopts best practices from the open-source dbt library and elevates them with its own design elements. This provides a powerful, integrated data transformation workspace, all presented within the **Data modeling** module.

## Components

If you have used dbt before, some concepts in ReOrc's data modeling module may be familiar. ReOrc leverages several data transformation techniques and artifacts from open-source dbt, and enhances them with an intuitive asset management system.

Take a look at these guides to get started with data modeling in ReOrc.

* [**Sources**](/data-modeling/sources): Sources are references to raw tables from a database or to models defined in other projects. These sources act as the input for data transformation.
* [**Models**](/data-modeling/models): Queries that process data, apply transformations, and output structured datasets. ReOrc currently supports models in SQL.
* [**Jinja templating**](/data-modeling/jinja-templating): Jinja is a templating language originally used in the Python ecosystem. With Jinja, you can enhance SQL transformation by adding programming features, such as loops, variables, and functions (or macros).
* [**Data lineage**](/data-modeling/data-lineage): Data lineage provides a visual representation of data flows throughout various transformations, from sources to destination. This feature helps you understand how transformation can impact downstream output.
* [**Data tests**](/data-modeling/data-tests): Data tests are assertions that you make about models and resources in a project. These tests validate the correctness of the transformed data, ensuring that standards for integrity and quality are met before delivering the data to downstream analytics.


# Sources

A source is a reference to raw tables from database that you can use in your models.&#x20;

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FhdAhximkn5juMwKCGxhH%2Fdb_source_model_diagram.jpg?alt=media&amp;token=1b2db732-0d12-4aa1-ad1e-45d0d39c591f" alt=""><figcaption></figcaption></figure>

In traditional SQL transformation, raw tables are typically referenced directly by their names. This leads to a few challenges, such as code readability and dependency management between tables. In contrast, sources introduce a more structured and modular way to reference raw tables, providing several benefits:

* **Clear data lineage**: Sources help you explicitly identify raw tables as external data sources. This helps establish clear data lineage, making it easier to trace data from raw tables to the transformed models.
* **Data testing**: Declaring raw tables as sources allows you to implement data tests. You can validate assumptions about the data quality, ensuring transformations applied later are based on trusted data.
* **Improved communication**: In source metadata, you can add descriptions, owners, and other information to clearly express your use cases. This creates transparency and improves communication across teams.

## Create a source

To create a source, follow these steps:

1. In the **Models** tab, click on the **+** icon and select **Add source**.&#x20;
2. In the opened modal:
   1. Select the connection type. Currently, ReOrc supports referencing from a warehouse.
   2. Select the target connection. If you haven't set up the project connection, refer to: [Project connections](/connections/project-connections).
3. Click **Next**. ReOrc then displays all the tables available from the target connection.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FYqM2IyzMSSNa7D23digG%2FRecurve_add_source_select_tables.png?alt=media&amp;token=de8959e9-b741-4ba0-8143-f343e1172e6a" alt=""><figcaption><p>Select tables from a connection</p></figcaption></figure>

4. Select the desired raw tables or models.
5. Click **Add source**.

The selected tables will then be added to the **sources** folder and grouped by connection name.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F3ZNHgjxhVpArYQmI52tf%2FRecurve_added_sources.png?alt=media&amp;token=a0de20f3-0518-418b-8dfb-def68ff4735d" alt=""><figcaption></figcaption></figure>

You can view the schema of a source by opening it in the editor. A schema contains field name (or column name), data type, and comment.&#x20;

## Select from a source

With raw tables organized by sources, you can reference them in a model using the `{{ source() }}` Jinja function. For more details, see: [Models](/data-modeling/models).

The function requires two arguments:

* `source_name`: the folder name that contains the source.
* `table_name`: the name of the table.

For example, with the `raw_orders` table added under the `jaffle_shop` folder, we can reference it as follows:

```sql
select 
    id as order_id,
    customer as customer_id,
    ordered_at as order_date

from {{ source("jaffle_shop", "raw_orders") }}
```

The above model is then compiled to:

```sql
SELECT
  id AS order_id,
  customer AS customer_id,
  ordered_at AS order_date
FROM
  `jaffle_shop`.`raw_orders`
```


# Models

A model is a query that processes data from sources, applies transformations, and outputs structured datasets.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FXc5mu3aba3g9l38ahJs2%2Fincremental_model_diagram.jpg?alt=media&amp;token=9f3e6c63-2c6d-492f-9874-1fcc94f57b83" alt=""><figcaption></figcaption></figure>

Models are the fundamental building blocks in the data modeling module, with each model representing a discrete unit of transformation. This approach shifts development from monolithic SQL scripts toward a more modular, maintainable structure that supports incremental development.

ReOrc currently supports writing models in SQL.&#x20;

As an example, the following snippet showcases the basic syntax of SQL models:

* At its core, models are regular queries to data sources.
* Transformation is finalized with a single SELECT statement.
* Jinja is integrated to make references and enhance logic. See: [Jinja templating](/data-modeling/jinja-templating).

```sql
-- Select the total number of orders per customer
select
    customers.customer_id,
    customers.first_name,
    customers.last_name,
    count(orders.order_id) as total_orders
from
    {{ source('jaffle_shop', 'raw_customers') }} as customers
join
    {{ source('jaffle_shop', 'raw_orders') }} as orders
on
    customers.customer_id = orders.customer_id
group by
    customers.customer_id,
    customers.first_name,
    customers.last_name
order by
    total_orders desc
```

When ReOrc runs your SQL models, it goes through a process of compiling them into executable SQL queries. This means parsing all Jinja expressions, resolving model and source dependencies based on `ref()` and `source()` calls, and combining with configurations (like materialization types) to produce the final SQL.

Implementing data transformation logic as models provides several benefits:

* Simplicity: Complex transformation can be broken down into smaller, manageable steps.
* Modularity and reusability: Some transformations can be extracted into foundational models that are referenced in multiple places. This allows you to build transformation incrementally, rather than start from scratch.
* Data lineage and transparency:  Linkage between models are automatically tracked and presented in data lineage. This helps you understand the dependencies between models and make debugging easier. See: [Data lineage](/data-modeling/data-lineage).
* Testing and validation: You can write tests and apply them to each model to ensure data quality. A model is run together with its tests to ensure data issues are caught early. See: [Data tests](/data-modeling/data-tests).

## Create a SQL model

To create a SQL model, follow these steps:

1. In the **Models** tab, click on the **+** icon and select **New SQL model**.
2. Provide a name for your model and click **Create**.

   The created model will be organized in the **models** folder.
3. In the model editor, input your SQL query.&#x20;

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FhbxmHe7sgwMGc4LmA5WD%2FRecurve_query_pasted.png?alt=media&amp;token=9c820f46-0734-4309-9ca1-17b166fe5812" alt=""><figcaption></figcaption></figure>

For example:&#x20;

```sql
-- select customers from raw_customers table
select 
        id as customer_id
        name as customer_name
from {{ source('jaffle_shop', 'raw_customers') }}
```

4. Click **Save** to confirm the changes.
5. Click **Preview** to view the query output in the **Result** tab.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FniawLrtX2kYKydHZnxOv%2FRecurve_preview_results.png?alt=media&amp;token=c172e310-cf2b-4caa-a339-2f735f8d8816" alt=""><figcaption></figcaption></figure>

6. To inspect the compiled code of your model, click on the **Compiled code** tab.

## Reference a model

Referencing one model in another allows you to build on existing transformations without rewriting. This modular approach streamlines your transformations, making the logic more maintainable and readable.

Within a model, you can reference another model using the `ref()` function. This function establishes dependencies between models, ensuring that the models are built in the correct order.

Here's an example:

```sql
-- model: stg_orders
select
    id as order_id,
    user_id as customer_id,
    order_date,
    status,
    amount
from {{ source('jaffle_shop', 'orders') }}
```

```sql
-- model: mart_daily_revenue

select
    date_trunc('day', order_date) as date,
    count(*) as number_of_orders,
    sum(amount) as daily_revenue
from {{ ref('stg_orders') }}
where status = 'completed'
group by 1
order by 1 desc
```

In  `mart_daily_revenu`, the `ref('stg_orders')` function references `stg_oders` as a dependency. This reference allows one model to use the results of another, and also ensures their order when building models.

## Organize models

As data transformation can follow different strategies and go through several stages, you can organize the models into folders that reflect the transformation stages and help maintain a clean project structure.

To create a new folder, click on the action button of an existing folder and select **Add sub-folder**:

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FLfnMj1WsaoQQeOTnL2rc%2FRecurve_add_subfolder.png?alt=media&amp;token=56777547-bd68-4fba-884b-eacdb203e5d1" alt=""><figcaption></figcaption></figure>

To move a model into the new folder, click on the action buton of the model and select **Move**. Then select the target folder from the list.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FriMfFjWFC6Am21zpvFdm%2FRecurve_move_model.png?alt=media&amp;token=5eaf8e3f-900e-4b60-8f7f-6cbed2d78077" alt=""><figcaption></figcaption></figure>


# Model schema

A SQL model is essentially constructed as a `SELECT` statement. The results generated from a model produce a table with columns, each having specific names and data types based on the transformations you define within the model.

You can define a model schema, which serves as a description of how the resulting data should be structured—similar to a table schema in a relational database.

Defining a schema for your model offers two primary benefits:

* **Description**: Team members can easily understand the expected structure of the data by reviewing the schema without having to run a preview.
* **Structural enforcement:** In the ReOrc data pipeline, other assets such as data tests or cubes refer directly to the model schema to understand the model's structure. This schema serves as the single definition of the structure, ensuring alignment across all implementations. Therefore, maintaining a consistent and well-defined schema is essential.

### Define a model schema

To define the schema for a SQL model, follow these steps:

1. Open a SQL model in the editor.
2. Switch to the **Fields** tab.
3. Generate the schema:

   For quick generation, you can click on **Generate Schema**. ReOrc will produce the schema results, including column names, data types, and suggested descriptions (generated by our AI).

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F3C6PEksnVfxDlWN2R24m%2FRecurve_schema_generation.png?alt=media&amp;token=b5c06baa-0b52-405d-bbfa-cc235d01e985" alt=""><figcaption></figcaption></figure>
4. Verify and adjust the schema.

   After generation, you can rename fields (column names), modify data types, or adjust descriptions to improve clarity.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FP45ZA0BsbE7ffQVmGxyc%2FRecurve_edit_schema.png?alt=media&amp;token=e47b98a1-4a31-473f-a34f-66fdc32ae2da" alt=""><figcaption></figcaption></figure>


# Model configurations

While ReOrc provides the [metadata panel](/asset-management/metadata) for basic model configuration, you can use the `config()` macro (provided by dbt) to implement more granular and powerful controls over your model's behavior. This macro allows you to define model-specific configurations directly in your SQL files, giving you precise control over how your models are built and materialized.

## Key features of the `config()` macro

1. **Materialization control**: The `config()` macro enables users to determine how a model will be materialized in the analytics database. Common materialization strategies include:
   * **Table**: The model is created as a table.
   * **View**: The model is created as a view.
   * **Incremental**: The model is built incrementally, allowing for efficient updates to large datasets.
2. **Granular control**: Configurations set using the `config()` macro can inherit or override settings defined in other locations like model's metadata. Users can define various configurations within the `config()` macro, some of which include:
   * Setting unique keys for incremental models
   * Specifying incremental strategy
   * Specifying partition for large data volume
   * Configuring pre-hook and post-hook

The configuration should be placed at the beginning of model script:

```sql
{{ config(
    materialized='incremental',
    unique_key='id'
) }}

SELECT *
FROM {{ ref('source_table') }}
```

## Configure incremental models

One popular usage of `config()` is to define the incremental strategy for data models.

Incremental is materialization strategy designed to efficiently update tables in a data warehouse by only transforming and loading new or changed data since the last run. This approach significantly reduces the time and resources required for data transformations, making it especially useful for large datasets.

In a model's metadata panel, you can specify the materialization option to be `incremental`. By default, this option results in append-only behavior, where new data is simply added to the table with each build. Therefore, you must specify the following configurations:

* **`unique_key`**: Defines the unique identifier for records in the model, which helps dbt determine whether to insert new records or update existing ones.
* **`incremental_strategy`**: Specifies how dbt should handle incremental updates. Common strategies include:
  * `merge`: Updates existing records and inserts new ones based on the unique key.
  * `append`: Simply adds new records without updating existing ones.
  * `insert_overwrite`: Overwrites existing records with new data based on specified conditions.
* **`is_incremental()`**: This macro is essential for filtering which rows should be processed during an incremental run. It allows you to specify conditions to select only new or updated records since the last execution.

For example, in the orders table, we can implement incremental materialization to process only new or updated orders since the last run, reducing the processing time and ensuring the table remains up-to-date:

```sql
{{ config(
    materialized='incremental',
    unique_key='id',
    incremental_strategy='merge'
) }}

select * 
from {{ source("public", "raw_orders") }}
{% if is_incremental() %} -- only process new records
    where ordered_at >= (select max(ordered_at) from {{ this }})
{% endif %}
```

## Platform-specific congfigurations

As different database platforms use varying approaches to optimize data processing, some configurations are designed and applied specifically for each platform. For detailed information on these platform-specific configurations and behaviors, refer to [PLATFORM SPECIFIC](/platform-specific/doris-selectdb)


# Jinja templating

[Jinja](https://jinja.palletsprojects.com/en/stable/) is a fast, expressive, powerful templating engine, commonly used to generate dynamic content.  It allows you to embed programming logic into any text-based format (HTML, XML, CSV, or LaTex).

In modern data engineering, Jinja has gained popularity by enabling the use of variables, logic, and reusability in SQL transformation, largely thanks to the integration in open-source tools like dbt.

ReOrc is integrated with dbt to support Jinja directly in SQL models and allows you to define reusable assets, such as variables, macros, and tests.

## Jinja syntax

Jinja's syntax is very similar to Python and is declared inside delimiter tags, which include:&#x20;

* **Expression `{{ ... }}`:** Expressions are used to output string, reference variables, and call macros.
* **Statement `{% ... %}`:** Statements are used for control flow, such as `for` loops and `if` statements, and to define macros.&#x20;
* **Comments `{# ... #}`:** These are comments in Jinja and won't be compiled.

The following are some examples of using Jinja in ReOrc SQL models.

**Set variable**

With Jinja, you can define a local variable and use directly in the query as follows:

{% tabs %}
{% tab title="SQL model" %}

```sql
{% set min_date="2018-02-17" %}

select * from {{ source('jaffle_shop', 'raw_orders') }}
where order_date >= '{{ min_date }}'
```

{% endtab %}

{% tab title="Compiled code" %}

```sql
select * from "jaffle_shop"."raw_orders"
where order_date >= '2018-02-17'
```

{% endtab %}
{% endtabs %}

ReOrc supports creating global variables that you can use in multiple models and pipelines. See: [Variables](/data-modeling/jinja-templating/variables).

`if` **statement**

{% tabs %}
{% tab title="SQL model" %}
Check the condition using `if` statement.

```sql
{% set filter_shipped = True %}

select *
from {{ source('jaffle_shop', 'raw_orders') }}
where 1 = 1  -- Always true, allows appending conditions dynamically
{% if filter_shipped %}
  and status = 'shipped'
{% endif %}
```

{% endtab %}

{% tab title="Compiled code" %}

```sql
select *
from "jaffle_shop"."main"."raw_orders"
where 1 = 1  -- Always true, allows appending conditions dynamically

  and status = 'shipped'
```

{% endtab %}
{% endtabs %}

`for` **loop**

{% tabs %}
{% tab title="SQL model" %}
Iterate through a list of items using `for` loop.

```sql
-- define the list of statuses
{% set statuses = ['shipped', 'returned', 'cancelled'] %}

-- use a for loop to create a query with counts for each status
select
    {% for status in statuses %}
        sum(case when status = '{{ status }}' then 1 else 0 end) as {{ status }}_count
        {% if not loop.last %}, {% endif %}
    {% endfor %}
from {{ source('jaffle-shop', 'raw_orders') }}
```

{% endtab %}

{% tab title="Compiled code" %}

```sql
select
        sum(case when status = 'shipped' then 1 else 0 end) as shipped_count, 
        sum(case when status = 'returned' then 1 else 0 end) as returned_count, 
        sum(case when status = 'cancelled' then 1 else 0 end) as cancelled_count
        
from "jaffle-shop"."raw_orders"
```

{% endtab %}
{% endtabs %}

**Define macro**

Jinja macros are similar to functions in programming languages. You can define your logic and transformation into a macro and use it across different models.  See: [Macros](/data-modeling/jinja-templating/macros).

{% tabs %}
{% tab title="Macro definition" %}
Definition of a macro that calculates the sum based on the given status:

```sql
{% macro count_orders_by_status(status) %}
    sum(case when status = '{{ status }}' then 1 else 0 end)
{% endmacro %}
```

{% endtab %}

{% tab title="SQL model" %}
Calling the macro in a model.&#x20;

```sql
select
    {{ count_orders_by_status('shipped') }} as shipped_orders,
    {{ count_orders_by_status('returned') }} as returned_orders,
    {{ count_orders_by_status('cancelled') }} as cancelled_orders
from {{ source('jaffle_shop', 'raw_orders') }}
```

{% endtab %}

{% tab title="Compiled code" %}
As you can see, afte compilation the macro call is resolved with its definition:

```sql
select
   sum(case when status = 'shipped' then 1 else 0 end) as shipped_orders,
   sum(case when status = 'returned' then 1 else 0 end) as returned_orders,
   sum(case when status = 'cancelled' then 1 else 0 end) as cancelled_orders
from "jaffle_shop"."raw_orders"
```

{% endtab %}
{% endtabs %}

## Built-in Jinja functions

As ReOrc integrates with the open-source dbt framework, the built-in, dbt-specific Jinja functions are also available for use. For the full list of functions and definitions, refer to [dbt Jinja functions](https://docs.getdbt.com/reference/dbt-jinja-functions).

Some commonly used functions are:

1. **`ref()`**
   * **Purpose**: References another model within the same project or across projects. This function ensures that dependencies are managed correctly.
   * **Usage**: `{{ ref('model_name') }}`
2. **`source()`**
   * **Purpose**: Creates a dependency between a model and a source table, enabling better tracking of data lineage.
   * **Usage**: `{{ source('source_name', 'table_name') }}`
3. **`var()`**
   * **Purpose**: Accesses variables defined in the project **Library**, allowing for parameterization of models and macros. See: [Variables](/data-modeling/jinja-templating/variables).
   * **Usage**: `{{ var('variable_name') }}`


# Variables

Variables can help configure time ranges, eliminate hardcoded values, or supply data for model configuration. In a ReOrc project, you can define variables as assets and use them across multiple models.

There are two scopes for variables in ReOrc:

* **Local variables** are defined in a model using Jinja syntax; they are scoped locally and only accessible within the model.&#x20;
* **Global variables** defined in **Library** > **Variables**, are project-level assets and accessible from any models in the project.&#x20;

When we refer to "variables" generally, we mean global variables.

Variables are defined with explicit types to remove the need for casting and prevent format errors. When building a model (whether in preview, console, or pipeline) that has variables, you can use pre-defined default values or overwrite them with custom inputs.

## Define a variable

To define a project variable, follow these steps:

1. In ReOrc, open your project and go to **Library** > **Variables**.
2. Click **+Add New**.
3. Provide the name, data type, description, and value for the variable.

   ReOrc supports creating project variables with explicit data types.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F3kpaV7yCw0o3fI9Ycyd7%2FRecurve_create_variable_min_order_date.png?alt=media&amp;token=cbbc8ef3-f36c-4a0a-b78c-8452340d45c7" alt=""><figcaption></figcaption></figure>

4. Click **Add**.

The new variable will be displayed in the **Variables** section of **Library**.

By default, a created variable is active and ready for use in models. You can deactivate the variable by toggling off the **Active** option.

## Use the variable

You can start referencing the defined variable in models with the `{{ var('variable_name') }}` expression.

For example, the following model uses the `min_order_dateime` defined in the project library.

```sql
select 
    id as order_id,
    customer as customer_id,
    ordered_at as order_date

from {{ source("jaffle_shop", "raw_orders") }}

where ordered_at >= {{ var('min_order_datetime') }}
```


# Macros

A macro in Jinja is similar to function in programming languages. It allows you to define reusable pieces of code that accept parameters, process logic, and return values. Jinja macros are used in SQL models to encapsulate transformation logic, avoid repetitive SQL code, and improve maintainability.&#x20;

In ReOrc project, you can define macros as assets and use them across different modules and multiple models.

## Syntax

Jinja macros are defined within the `{% macro %}` and `{% endmacro %}` statements. Similar to Python functions, they accept parameters, process logic, and return values.

For example:

```sql
{% macro cents_to_dollars(column_name, scale=2) %}
    ({{ column_name }} / 100)::numeric(16, {{ scale }})
{% endmacro %}
```

The snippet above defines a macro named `cents_to_dollars` which converts cent amount to dollar amount by specify two parameters: `column_name` and `scale` (optional parameter).

## Define a macro

To define a project-level macro, follow these steps:

1. In ReOrc, open your project and go to **Library** > **Macro**.
2. Click **+ Add New**.
3. Provide the SQL code for the macro and the description.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FeWK63LZhPsyVx57zYiLk%2FScreenshot%202024-12-15%20at%2014.44.38.png?alt=media&amp;token=c726ad64-296b-43e3-aa88-dfdaefb404c4" alt=""><figcaption></figcaption></figure>
4. Click **Add**.&#x20;

The new macro will be displayed in the **Macro** section of **Library**.

By default, a created macro is active and ready for use in models. You can deactivate the macro by toggling off the **Active** option.

## Call the macro

With the macro defined and active, you can call it from any model in your project. Macros are called with the `{{ ... }}` expression.

For example, we can apply the `cents_to_dollars` macro as below:

```sql
select
  id as payment_id,
  {{ cents_to_dollars('amount') }} as amount_usd,
  ...
from {{ ref("stg_payments") }}
```

## Use macros from a package

In addition to user-defined macros and built-in functions, you can get access to a wealth of predefined macros via dbt packages. These packages offer the resources and macros designed for common transformation use cases, helping you speed up development and avoid reinventing the wheel.

For details on importing packages, see: [Packages and dependencies](/asset-management/packages-and-dependencies).

To call a macro imported from a package, simply prefix the call with the package name:

```sql
select 
    order_id,
    {{ dbt_utils.safe_add(['subtotal', 'tax', 'shipping_fee']) }} as total_amount,
from {{ source('jaffle_shop', 'raw_orders' }}
```


# Materialization

When you run transformation in a model you can define how the generated results are stored, or materialized, in the target database. ReOrc supports the following materialization options.

* Table
* View
* Incremental
* Ephemeral

Depending on your transformation use cases, you can select different materialization strategies. You can view and configure materialization of a model in the [**Metadata**](/asset-management/metadata#view-and-edit-metadata) section.

{% hint style="info" %}
By default, all models are materialized as tables.
{% endhint %}

## Table

**Definition:** Creates a table and stores the results when building the model. Every time the model is run, the table is dropped and recreated with the latest data.

**Use case:** Use when you want to physically store the data and prefer faster query performance at the cost of extra space.

## View

**Definition:** Creates a view in the database. A view is simply a stored query and  does not hold data; instead, it provides a virtual table environment for various complex operations.

**Use case:** Use views when you want to avoid storing a physical table and don’t mind the performance cost of re-running the query every time the view is accessed.

## Incremental

**Definition:** Adds new or updated records to an existing table without recreating the entire table. &#x20;

**Use case:** Ideal for very large datasets where it would be inefficient to rebuild the entire table each time. Only processes new or modified data since the last run.

## Ephemeral

**Definition:** The model is not materialized at all. Instead, the model snippet is interpolated into the downstream models that reference it.  This is similar to treating the model snippet as a common table expression (CTE).

**Use case:** Useful for intermediate computations that don't need to be stored but are referenced in downstream models.&#x20;


# Data lineage

Data lineage helps track how data flows through the transformation process, from sources to models. It provides visibility into the dependencies between datasets and the transformations applied to them, making it easier to understand the relationships and impacts of changes within a data process.

In ReOrc, data lineage is represented as a directed acyclic graph (DAG). Whenever you edit an asset and make references (through `ref()` and `source()` functions), ReOrc automatically tracks its relationships with other assets and reflects them in the DAG view.

## View lineage

To view data lineage in ReOrc, open an asset in the editor and toggle on the **Lineage view** option.

Each asset in the data lineage is represented as a node with links showing the relationships with other assets (nodes). You can click and drag the nodes to reposition them for a clearer view.

The bottom-right toolbar allows you to expand the lineage section, zoom in and out, and focus on the current node of the opened asset.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FExZL9P5lNAyvA4TQx6pj%2FRecurve_data_model_lineage.png?alt=media&amp;token=27df7095-82cc-4502-ad74-8cf4b536ad7f" alt=""><figcaption></figcaption></figure>

## Navigation in lineage

### Centric node

By default, the selected asset/node is designated as the *centric* node. With large project size and complex transformation strategy, there can be a lot of linkage associated with an asset. By focusing on one node at a time, the lineage view helps you inspect the asset information, and its relationship with the upstream and downstream models, and enhance the overall transformation plan.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FZI8tWNaSb8EfiQ8FT3VE%2FRecurve_lineage_view_centric_node.png?alt=media&amp;token=8f5dd7ca-acf4-4b9c-956c-126b8d70ebcc" alt=""><figcaption></figcaption></figure>

You can use the search bar on the top left corner to search and adjust the number of upstream and downstream layers of the current node.

### Show all lineages

To view the data lineage of all assets in the project, you can toggle on the **Show all lineages** option.&#x20;

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FOIrF7qhli2r68zQl7t73%2FRecurve_show_all_lineages.png?alt=media&amp;token=e60499bd-2e86-400c-88c8-c446cb16d417" alt=""><figcaption></figcaption></figure>


# Data tests

Data tests are assertions that you make about models and resources in a project. These tests validate the correctness of the transformed data, ensuring that standards for integrity and quality are met before delivering the data to downstream analytics. A data test is simply a SQL or Jinja query that selects rows meeting a failing condition.

Data test is one of the *dbt* artifacts that ReOrc integrates into its data validation capabilities.

There are two types of data tests:

* **Generic test**: a test designed to be reusable across multiple models, columns, or tables. It targets specific data but can be applied broadly to check for common conditions or constraints.&#x20;
* **Singular test**: a custom SQL-based test where you can write a specific SQL query to validate data. It is typically used for more specific or complex checks that are unique to a particular model or situation.

ReOrc provides a wide collection of templates for built-in generic tests, as well as the flexibility to write custom queries to cover more advanced scenarios. Built-in generic tests provide the basic but essential validations, such as `NULL` check or referential integrity, while custom generic tests and singular tests can deal with complex business logic.

As with any quality control practice, we recommend starting with the most basic testing scenarios before moving to complex cases. You can first apply built-in generic tests to validate the core assumptions about your dataset structure, then add custom tests to reflect specific business rules.

## Test categories

Data tests are associated with categories that reflect relevant business metrics. We adopt these categories from industry best practices to help you understand how well your data serves different business needs.

You can set up multiple tests of different categories for each data asset. When running these tests in pipelines, you'll see the results grouped by category in the [Data Quality dashboard](/health-tracking/data-quality), making it easier to understand how your data is performing.

<table><thead><tr><th width="159">Category</th><th>Defintion</th><th>Example</th></tr></thead><tbody><tr><td>Freshness</td><td>Check the timestamp to see if the data is up-to-date and made available for the intended use cases.</td><td><p></p><ul><li>A daily sales report should have data of the most recent transactions.</li><li>Raw data is expected to be ingested daily before 6 pm.</li></ul></td></tr><tr><td>Volume</td><td>Check that the number of rows are properly processed and falls within a specified range.</td><td><ul><li>Updated data should be no less than 1000 records every day.</li></ul></td></tr><tr><td>Completeness</td><td>Check if there are missing values in datasets.</td><td><ul><li>Timestamp column should not contain <code>NULL</code> values.</li><li>Name column should not contain empty strings.</li></ul></td></tr><tr><td>Validity</td><td>Check if values in a column fall within a specified list or adhere to a defined format.</td><td><p></p><ul><li>String value should be within the list of enums.</li><li>Numeric value should be within the expected data range.</li></ul></td></tr><tr><td>Uniqueness</td><td>Check for undesired duplicates of data within a dataset.</td><td><ul><li>In the <em>order</em> table, no two records should have the same combination of <code>order_id</code> and <code>product_id</code> values.</li></ul></td></tr><tr><td>Consistency</td><td>Check if aggregated data aligns correctly with the expected results.</td><td><ul><li>The total sales amount in <em>monthly_sales</em> is aggregated from daily transactions in <em>daily_sales</em> table. Consistency check should be applied to ensure montly total sales is consistent with the sum of daily sales.</li></ul></td></tr></tbody></table>

## Test severity

A data test applied to an asset returns a list of failing rows as its result. Each test result has a severity level indicating its significance: Passed, Warning, or Error.&#x20;

In the **Severity level** section of a test, you can set thresholds for these levels based on the number of failures:

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FoQtbDStxnnsZ940TvpBe%2FRecurve_test_template_security_level.png?alt=media&amp;token=540a518e-5d8f-4573-9c4a-c1aa1a4159f2" alt=""><figcaption></figcaption></figure>

For example, a test that checks for data completeness (columns with `NULL` values) can have the following thresholds:

* **Error** if the `NULL` % is greater than 10%.&#x20;
* **Warning** if the `NULL` % is between 0% and 10%.
* **Passed** otherwise.

## Create a test from a template

Test creation is centralized in the **Test case template** section, which displays all available test artifacts, including:

* **Templates**: templates for built-in generic tests, organized by their scope (column-level or table-level) and by test category.&#x20;
* **Custom generic tests**: generic tests defined in project **Library**.
* **Custom SQL**: singular tests for one-off use cases.&#x20;

{% hint style="info" %}
Currently, ReOrc supports test cases for models.
{% endhint %}

Follow these steps to create a test from a template:

1. Open your model in the editor.
2. Switch to the **Test cases** tab and click **+ Add new**.
3. In the test template, you can see all the available test templates, including the templates for built-in tests and custom tests. Select a desired template.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FjhSWDFcU0tjtalrtf7v4%2FRecurve_test_case_template.png?alt=media&amp;token=5fa800fc-501a-4119-84b4-482ee004ece0" alt=""><figcaption></figcaption></figure>
4. Configure the test case.&#x20;

   The configuration may differ between templates. For example, in the template for **Row Values Freshness Check**, we need to specify the following:

   * Name: the displayed name in the test case list.
   * Description: the description to communicate your intentions.
   * Track data from column: specify the column to apply the test condition.
   * Condition (optional): limit the scope of the test to only certain rows based on specific criteria, ensuring that the comparison is meaningful within a defined context.
   * Severity: set the threshold for severity levels.
5. Click **Add**.

The new test will be displayed in the **Test cases** tab of the model.

## Test execution

Data tests assigned to a model are executed when you:

* Run and preview the model using console: [Console](/asset-management/console)
* Run a pipeline that involves the model: [Job](/pipeline/job).

## Invalid test cases

Test cases involving columns or models will become invalid if the columns or models are missing due to schema changes or deletions. The tests will fail when you run the models, in console or pipeline.&#x20;

{% hint style="info" %}
Make sure that you review the dependent test cases of a model after making changes to its schema.
{% endhint %}

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FgnrKZMrM0hIj3wyesIJB%2FRecurve_model_schema_invalid.png?alt=media&amp;token=82cd0413-6035-4fc2-bc89-bfa3fdc06aa5" alt=""><figcaption></figcaption></figure>

When a test case is invalid, you need to either reconfigure the schema/model or modify the test case itself.


# Built-in generic tests

ReOrc provides you with a list of templates for generic tests of common use cases. In this page, you can check out the description of each test and learn to incorporate them into your data workflow.

ReOrc built-in generic tests are built upon the curated tests of the *dbt-expectations* package. To learn more about the implementation of the tests, visit the [dbt-expectations repository](https://github.com/calogica/dbt-expectations).

{% hint style="warning" %}
Built-in test cases involving model columns (column-level tests) will retrieve the columns from the model's schema. Therefore, you must generate the schema before running these test cases. See: [Model schema](/data-modeling/models/model-schema).
{% endhint %}

## Freshness (coming soon)

<details>

<summary>Freshness</summary>

This test checks if the values in a specified time-based column are recent, meaning they fall within a certain interval before the current timestamp.&#x20;

In **Configuration**, you need to provide the following:

* Track data from column: select the target time-based column to check for recency.
* Date part: the unit of time for the interval.
* Interval: how far back from the current timestamp the data should be considered recent.

&#x20;<img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FC69cpiDtD6Ze4OhYAPjx%2FScreenshot%202024-12-19%20at%2010.00.43.png?alt=media&amp;token=b3fabf3f-bfda-483b-afff-a4967d33b9f6" alt="" data-size="original">

For example, to check if the orders in `stg_orders` are all created within the last 5 months, you need to track data from the `ordered_at` column, set `month` for date part and `5` for the interval. &#x20;

Additionally, you can set conditions for rows, for example `ordered_at` is not `null`.

</details>

<details>

<summary>Freshness (with group by)</summary>

This test checks if the groups of values in a specified time-based column are recent, meaning they fall within a certain interval before the current timestamp.&#x20;

In **Configuration**, you need to provide the following:

* Track data from column: select the target time-based column to check for recency.
* Date part: the unit of time for the interval.
* Interval: how far back from the current timestamp the data should be considered recent.
* Group by: which columns to group by. The test will evaluate each unique combination of the specified columns.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FsbCwqGZd5MQKXwajwTZ9%2FRecurve_row_value_freshness_group_by.png?alt=media\&token=7c9d3e63-4305-470d-96f5-ebf860d6adee)

For example, to check each customer in the `stg_orders` model has at least one order in the last 24 hours, you can specify:

* Track data from column: `ordered_at`
* Date part: `hour`
* Interval: 24
* Group by: `customer_id`

</details>

## Volume

<details>

<summary>Table Row Between</summary>

This test checks if the number of rows in a model falls within a certain range, ensuring that your analytics and reporting are based on a relevant and sufficient dataset.

In **Configuration**, you need to provide the following:

* Min: the minimum value of the range.
* Max: the maximum value of the range.
* Strictly: whether the min and max boundaries are inclusive or exclusive.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F6cJS7Br7rga4EItqPEiq%2FRecurve_table_row_between.png?alt=media\&token=505fb6b1-a774-4047-9b51-f4f443893469)

For example, you can check that the number of orders in the `stg_orders` are sufficient for analytics by demanding the the row count should be between 50 (min) to 200 (max).

</details>

<details>

<summary>Table Row Equal</summary>

This test checks if the number of rows in a model to be equal to a specified value. This is useful when you expect that a specific transformation should produce an exact number of entries.

In **Configuration**, you need to provide the exact row count value.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FAoNn3dunY5qHpmJn3Ghv%2FRecurve_table_row_count_equal.png?alt=media\&token=95b6030f-733d-4146-9f0c-a6604cf0a932)

</details>

## Completeness

<details>

<summary>Not null</summary>

This test checks if data of a specific column contain null values. This is crucial for maintaining data integrity, especially when certain columns are expected to always have valid entries.

In **Configuration**, you need to select the target column to check for null values.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FLTVvfQa8mWkQCGWbVMck%2FScreenshot%202024-12-19%20at%2009.44.49.png?alt=media\&token=2ccc0607-7abc-42a1-a623-a49db37deb1b)

</details>

## Validity

<details>

<summary>Numeric value within range</summary>

This test checks if each column value falls between a defined range. This is particularly useful for identifying outliers or errors in data, ensuring that values do not exceed expected limits.

In **Configuration**, you need to specify:

* Track data from column: select the target column to check for valid value.
* Min: the minimum value of the range.
* Max: the maximum value of the range.
* Strictly: whether the min and max boundaries are inclusive or exclusive.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F8udcUhBkPl9LG9UhRonJ%2FRecurve_numeric_value_within_range.png?alt=media\&token=626e504b-b21b-4065-a0cc-61f29c104da4)

For example, you can check if the orders in `stg_order` model have valid payment amount by checking if the `order_total` column data has values between 50 (min) and 1000 (max).

</details>

<details>

<summary>Maximum</summary>

This test checks if the maximum value in a specific column falls within a defined range.

In **Configuration**, you need to specify the following:

* Track data from column: select the target column to check for valid value.
* Min: the minimum value of the range.
* Max: the maximum value of the range.
* Strictly: whether the min and max boundaries are inclusive or exclusive.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FEuwnXZZMGGLou3wpPTh4%2FRecurve_maximum.png?alt=media\&token=f7543559-e88a-4a32-bc57-fce6ac731940)

</details>

<details>

<summary>Minimum</summary>

This test verifies that the minimum value in a specified column falls within a defined range.

In **Configuration**, you need to specify the following:

* Track data from column: select the target column to check for valid value.
* Min: the minimum value of the range.
* Max: the maximum value of the range.
* Strictly: whether the min and max boundaries are inclusive or exclusive.

<img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FLPIJdtfnGgTNHg9WDxv0%2FRecurve_minimum.png?alt=media&amp;token=1f03a67e-995e-48ab-8099-dad71e44a4d7" alt="" data-size="original">

</details>

<details>

<summary>Median</summary>

This test checks if the median value of a specified column — the middle value when data is sorted — falls within a defined range.

In **Configuration**, you need to specify the following:

* Track data from column: select the target column to sort and retrieve the median value.
* Min: the minimum value of the range.
* Max: the maximum value of the range.
* Strictly: whether the min and max boundaries are inclusive or exclusive.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FhU3eokFn0GUrBVKKb6bu%2FRecurve_median.png?alt=media\&token=3501cba5-d50f-4fcd-85ae-174294f902f1)

</details>

<details>

<summary>Average</summary>

This test checks if the mean (average) value of a specified column falls within a defined range.

In **Configuration**, you need to specify the following:

* Track data from column: select the target column to retrieve the average value.
* Min: the minimum value of the range.
* Max: the maximum value of the range.
* Strictly: whether the min and max boundaries are inclusive or exclusive.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FSL1Q7q9rsO9r6V58FGPU%2FRecurve_average.png?alt=media\&token=cc3ac6d6-20c3-4c4d-b7b9-3d8117cec7ee)

For example, you can use average test to check for anomalies in customer spending patterns by setting a defined range for `order_total` column values (between $50 and $1000).

</details>

<details>

<summary>Sum</summary>

This test checks if the total sum of all values in a specified column falls within a defined range.

In **Configuration**, you need to specify the following:

* Track data from column: select the target column to calculate the sum.
* Min: the minimum value of the range.
* Max: the maximum value of the range.
* Strictly: whether the min and max boundaries are inclusive or exclusive.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FztXhqAsNprQKzNO8MH94%2FRecurve_sum.png?alt=media\&token=eaabe8fd-93cd-4ced-a258-efa5d9523137)

</details>

<details>

<summary>Compare between two columns</summary>

This test checks that, for each row, the values in one column (A) are greater than the values in another column (B). This ensures that the relationship between the two columns holds true across the dataset.

In **Configuration**, you need to specify the following:

* Target column A: The column with values to be compared.
* Equal: This allows for equality; the test will pass if column A's values are greater than or equal to column B's values.
* Target column B: The column with values to be compared against.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F78hC61XJuvWgrH0fbxK2%2FRecurve_compare_values_between_two_columns.png?alt=media\&token=171e2d9f-3c21-4865-89d5-f9ca36871486)

For example, by design, the order total (after tax) should always be larger than subtotal.

</details>

<details>

<summary>Text value within enums</summary>

This test validates that all distinct values in a specified column are contained within a predefined set of acceptable values. This is crucial for maintaining data integrity and consistency, particularly when dealing with categorical data.

In **Configuration**, you need to specify the following:

* Target column: the target column to check for valid values
* Value list: a list of acceptable values, with each value separated by a new line, that the distinct values in the column must match.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F4xvr9KkdPK9Wb0O7g5DR%2FRecurve_text_value_within_enums.png?alt=media\&token=4f46fa16-2254-42b6-9312-8ffe0eb1f8c0)

</details>

<details>

<summary>Matches RegEx</summary>

This test expects column values to be strings that match a given regular expression, such as validation of e-mail addresses, phone numbers, or URL format specifications.

In **Configuration**, you need to specify the following:

* Target column: the target column to verify values with regular expression.
* Pattern: the regular expression.
* Is Raw: `true` if the regex pattern should be treated as a raw string. This allows you to write regex patterns without worrying about escaping backslashes.
* Flag: a string of one or more characters that are passed to the regex engine as flags (or parameters). Allowed flags are adapter-specific. A common flag is `i`, for case-insensitive matching. The default is no flags.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FcJQzwrFyhkk7iZelqgS1%2FRecurve_matches_regex.png?alt=media\&token=bed887cc-bc02-4748-90ff-48af6d6d5f36)

For example, in the `stg_items` model, we can verify whether the values in the `sku` column match the correct pattern: `^[A-Za-z]+-\d+$` (a sequence of letters, followed by a dash, and ending with digits).

</details>

## Uniqueness

<details>

<summary>No duplicates</summary>

This test checks that no two rows have the same combination of values in the specified columns, helping to maintain data integrity by preventing duplicate records.

In **Configuration**, you need to specify the following:

* Primary keys: the columns to create the combination of values.
* Set ignore value: determine how combinations with empty values should be handled — either when *all values are missing* or when *any value is missing*.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FCtxbJ1IU4WNLs6romSxx%2FRecurve_no_duplicates.png?alt=media\&token=3f1b9d72-82f6-40f0-a476-fe1d45e82dc3)

For example, we can check for the duplicate products (using a combination of name, sku, type) within the product model.

</details>

## Consistency

<details>

<summary>Data volume within two tables</summary>

This test verifies that the number of rows in one table matches the number of rows in another table, which is particularly useful in scenarios where data integrity between related tables is critical.

In **Configuration**, you need to specify the data model to compare against the current model.

![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FLTT8uQPuZgIDdoRG3fTx%2FRecurve_data_volume_within_two_tables.png?alt=media\&token=8b8cf463-31b4-4553-b960-58f9769401c9)

For example, you can use this test to verify that the number of rows in the `customers` table matches the number of distinct customers in the `orders` table. This can help ensure that all customers have at least one order recorded.

</details>


# Custom generic tests

Beyond built-in generic tests, you can write custom generic tests to cover complex testing scenarios.&#x20;

At bottom, generic tests are Jinja macros that return failing rows. These tests are considered project-level assets and can be used across different models in your project.&#x20;

To define a generic test, simply write a macro and wrap it within `{% test %} {% endtest %}` block. A generic test should accept one or both standard parameters:

* `model`: The model or resource where the test is applied.
* `column_name`: If the test validates assumptions about a specific column's data, include the `column_name` parameter.

Here's an example:&#x20;

This `payment_amount_reasonable` test receives four parameters: the model, column name, minimum and maximum amounts. Inside, the validation logic is organized into a CTE (common table expression) that queries all the payment amounts not in the reasonable range.

We can apply this generic test to models that store payment amount of different kinds.

```sql
-- custom generic test for the reasonable payment amount

{% test payment_amount_reasonable(model, column_name, min_amount=0, max_amount=200) %}

with validation as (
    select
        {{ column_name }} as payment_amount
    from {{ model }}
    where {{ column_name }} < {{ min_amount }}
        or {{ column_name }} > {{ max_amount }}
)

select *
from validation

{% endtest %}
```

## Create a custom generic test

To create a custom generic test, follow these steps:

1. In your project, go to **Library** > **Generic Test**.
2. Click **+ Add new**.
3. Define the generic test with the following fields:

   * SQL Code: provide the test code.
   * Parameter: hit the **Refresh** button to fetch the parameters involved in the test definition and provide the type.
   * Description: describe the functionality of the test.
   * Category: select the test category that the test should reflect.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FKwDPO1wzpTC5JxujzNsY%2FRecurve_custom_generic_test.png?alt=media&amp;token=68d1f6ba-37b6-4eeb-b3c1-57f99058d68c" alt=""><figcaption></figcaption></figure>
4. Click **Add**.

## Add a custom generic test

The created generic test is then accessible from **Test case template**. You set up the test the same way as a built-in generic test.&#x20;

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FIgJnsEqLxNPfzjkgNjf3%2FRecurve_custom_generic_test_template.png?alt=media&amp;token=086d73e0-958c-4355-8f47-a1e1717f66bb" alt=""><figcaption></figcaption></figure>

Specify parameter values in the **Configuration** section:

* **Generic Test:** Select the desired generic test from the dropdown menu.
* **Test Category:** Assign an appropriate category to the test based on its nature.
* **Configuration:** The test script will be automatically populated when you select a generic test from the dropdown.
* **Parameters:** Provide the parameter values.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FWSSYc0MoEIoFjAIypdqR%2FRecurve_use_custom_generic_test.png?alt=media&amp;token=5fe403a8-bc25-41fd-9256-68ee10df1bfd" alt=""><figcaption></figcaption></figure>

Once added, you can verify the test by running the model in [Console](/asset-management/console).


# Singular tests

Singular tests are simple SQL queries that return failing records of a model or a resource. They are typically used for one-off checks or specific business rules that do not require reusability.

You can use Jinja functions like `ref()` and `source()` to make reference to the target resource.

For example, we can create a singular test that checks for suspicious payments by method in the stg`_payments` table:

```sql
with large_payments_by_method as (
    select 
        paymentmethod,
        amount,
        status
    from {{ source("stripe", "raw_payments") }}
    where status = 'success'
        and (
            (paymentmethod = 'bank_transfer' and amount > 10000) or
            (paymentmethod = 'credit_card' and amount > 5000) or
            (paymentmethod = 'gift_card' and amount > 1000)
        )
)

select *
from large_payments_by_method
```

Notice that the singular test accepts no parameters as it's only applied on the `stg_orders` model.

## Create a singular test

To add a singular test to a model:

1. Open the **Test case template** and select / search for the **Singular Test** template.
2. Fill in the name, description, and SQL contents.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FMKjCUqUNSwEjk4glIMT0%2FRecurve_suspicious_payments.png?alt=media&amp;token=f6b8164b-29f7-4bac-8442-1bb86aa0864b" alt="" width="563"><figcaption></figcaption></figure>

3. Click **Save**.

Once added, you can verify the test by running the model in [Console](/asset-management/console).


# Overview

## What is semantic layer?

While much of data work focuses on building robust pipelines and transformation models, the true value of data is only recognized when it influences business decisions. As most stakeholders who want to derive insights don't often work with SQL or complex data tools, there's a crucial demand for an interface to enable end users to flexibly query data without tinkering with the technicalities.

Semantic layer is created to maps real-world entities and their metrics to a logical data structure. It translates database concepts into familiar business terms like product, customer, and revenue, creating a unified view of data across your organization.&#x20;

ReOrc's **Semantic Layers** provide an abstraction layer that simplifies data access and enhances query performance. By organizing data into meaningful structures such as **Cubes**, **Views**, and **Relationships**, ReOrc enables users to build efficient, reusable, and scalable data models.

Let's look at where this fits in your workflow. After ingesting and transforming your data, you need to make it meaningful for business use. This meaning comes from metrics that help end users make important decisions. A store owner may ask:

* "What are the monthly revenue this year?"
* "Which menu items have the highest profit margins?"

ReOrc's **Semantic Layers** makes these answers accessible without having to write custom SQL. By expressing requests through measures and dimensions, users can retrieve consistent, accurate insights.

{% hint style="info" %}
**ReOrc Semantic Layers** are available exclusively in the **Production** environment. This means that when creating cubes or views, they will reference the production database. Please ensure the data connection for the Production environment is properly configured.
{% endhint %}

## Concept

Semantic Layers in ReOrc are designed to bridge the gap between raw data storage and business intelligence by structuring data in an intuitive manner. Key components include:

### Cube

A **Cube** is a structured data model that enables multidimensional analysis. It consists of:

* **Measures**: Aggregable numerical values (e.g., revenue, sales count).
* **Dimensions**: Categorical values used for grouping and filtering (e.g., product category, region, date).
* **Primary and Foreign Keys**: Used to establish relationships with other cubes or data models.
* **Reusability**: Each cube can be used as an input to create views.
* **Integration with BI Tools**: Cubes provide structured data that feeds into business intelligence tools for reporting and analysis.

### View

A **View** is a logical representation of data derived from one or multiple cubes. It serves as a simplified and optimized data source, enabling users to:

* Pre-define complex aggregations and calculations.
* Improve query performance by materializing specific data structures.
* Customize datasets for different analytical use cases.

### Relationships

ReOrc allows users to define **Relationships** between different cubes and views to establish data connectivity. These relationships enable:

* Seamless data integration across multiple datasets.
* Enhanced query efficiency by leveraging predefined joins.
* A structured approach to data governance and security.

## Benefit of using Semantic Layers

* **Performance Optimization**: Reduces query complexity and speeds up data retrieval.
* **Reusability & Maintainability**: Encourages consistent data modeling and reuse.
* **Scalability**: Supports growing datasets and evolving analytical requirements.
* **Improved Data Governance**: Ensures data integrity and security by structuring access to datasets.


# Data Modelling vs Semantic Layer

## The Problem with Traditional Data Modelling

In traditional data modeling, analytics-ready datasets were designed primarily for BI tools, often following **Kimball star schema** principles. These models focused on pre-aggregating data to optimize dashboard performance but led to challenges like:

* **Inflexibility**: Pre-aggregated datasets restricted metric reusability.
* **Duplication of Business Logic**: Metrics were often defined separately in BI tools, leading to inconsistencies.
* **Performance Issues**: Repeated joins and transformations resulted in high query costs and slow reports.

## The Role of the Semantic Layer

The **semantic layer** allows organizations to define **metrics, business rules, and aggregations centrally**, decoupling transformation from metric definition. This enables:

* **A single source of truth for business metrics**
* **Consistent calculations across BI and data applications**
* **Faster insights by reducing redundant SQL logic**

## Key Differences: Traditional vs. Modern Data Modeling

| Aspect            | Traditional (BI-Ready)              | Modern (Metrics-Ready)                                 |
| ----------------- | ----------------------------------- | ------------------------------------------------------ |
| Schema Design     | Pre-aggregated fact tables          | Granular fact tables                                   |
| Metric Definition | Spread across BI tools              | Centralized in semantic layer                          |
| Transformation    | Done in data modelling tools and BI | Mostly in data modelling, semantic handles metrics     |
| Performance       | Heavy BI tool queries               | Optimized joins in data modelling, metrics in semantic |

## Designing Data Models to Support a Semantic Layer

To make data modelling tool work efficiently with a semantic layer, we need to adjust the traditional **staging → intermediate → marts** model by focusing on:

1. **Reducing Intermediate Models**: Avoid unnecessary joins and pre-aggregations.
2. **Creating Granular Fact Tables**: Keep data at an atomic level for flexible metric computation.
3. **Standardizing Naming Conventions**: Ensure data model names align with semantic layer definitions.

#### Example: Good vs. Bad Fact Table Design

**❌ Bad (Pre-Aggregated, BI-Ready)**

```sql
SELECT customer_id, DATE_TRUNC('month', order_date) AS month, SUM(order_amount) AS monthly_revenue
FROM stg_orders
GROUP BY customer_id, month;
```

**Issue:** This locks the aggregation at a **monthly level**, making it difficult to compute daily or weekly revenue.

**✅ Good (Metrics-Ready, Semantic Compatible)**

```sql
SELECT order_id, customer_id, order_date, order_amount
FROM stg_orders;
```

**Why?** The semantic layer can now dynamically aggregate revenue at different time grains (daily, weekly, monthly).

## Building a Semantic Layer That Works with data modelling tool

The semantic layer should be designed to:

* **Map directly to data model fact & dimension tables**
* **Define business metrics declaratively (not transform data further)**
* **Ensure reusability across multiple BI tools**

#### Example: Defining Metrics in the Semantic Layer

**Data Model Table (`fct_orders`)**

```sql
SELECT order_id, customer_id, order_date, order_amount FROM stg_orders;
```

**Semantic Layer (`metrics.yaml`)**

* metrics: name: total\_revenue description: "Total revenue, aggregated at different time grains" calculation: SUM(order\_amount) entity: customer\_id time\_grain: \["day", "week", "month", "year"]

**Benefit:** The same **total\_revenue** metric can be reused across dashboards and reports without redefining SQL logic.

## Best Practices for a Unified Approach

✅ **Keep Data Models at the Right Granularity**: Avoid pre-aggregations in data model layer; let the semantic layer handle them.

✅ **Ensure Referential Integrity**: Maintain primary and foreign key relationships in data models.

✅ **Validate Business Logic in Data Modelling Tool**: Build test cases to enforce data consistency.

✅ **Centralize Metric Definitions in the Semantic Layer**: Avoid hardcoding business logic in dashboards.

## Common Pitfalls and How to Avoid Them

| Pitfall                                                   | Solution                                                                        |
| --------------------------------------------------------- | ------------------------------------------------------------------------------- |
| Pre-aggregating Data in Data Model Layer                  | Keep fact tables granular; let the semantic layer handle aggregation.           |
| Defining Metrics in BI Instead of Semantic Layer          | Centralize metric definitions in a tool-agnostic semantic layer.                |
| Inconsistent Naming Between Data Models & Semantic Models | Standardize naming conventions between data model layer and the semantic layer. |

## Case Study & Example

#### Scenario: Tracking Monthly Active Users (MAU)

**✅ Data Model (`fct_user_activity.sql`)**

```sql
SELECT user_id, event_date, event_type FROM raw_events WHERE event_type IN ('login', 'purchase', 'page_view');
```

**✅ Semantic Model (`metrics.yaml`)**

* metrics: name: monthly\_active\_users description: "Unique users who were active in a given month" calculation: count\_distinct entity: user\_id time\_grain: month filter: event\_type IN ('login', 'purchase')

✅ **Why this works:** Data model tool prepares the raw event data, while the semantic layer defines the **MAU metric dynamically**.

## Summary

By shifting towards a **metrics-ready data modelling approach**, we:

* Separate **data transformation (data modelling)** from **metric definition (semantic layer)**.
* Ensure **business metric consistency** across tools.
* Improve **query performance** by reducing redundant calculations.
* Enable **flexibility** for future analytics and reporting needs.

#### Action Items for Data Teams:

* **Refactor data models** to remove pre-aggregations.
* **Adopt a centralized semantic layer** for metric definitions.
* **Standardize naming conventions** across data and semantic models.


# Cube

## Overview

The Cube in ReOrc's Semantic Layers is a structured data model that enables efficient data querying and analytics. It organizes data into measures and dimensions, allowing users to derive insights with ease. Cubes help abstract complex queries, improving performance and usability for business intelligence and reporting

## Cube Concept

A **Cube** is a virtual data model that represents a multidimensional dataset, composed of:

* **Measures**: Numeric values that can be aggregated (e.g., revenue, sales count).
* **Dimensions**: Categorical values used for grouping and filtering (e.g., product category, region, date).
* **Primary Key (PK)**: A unique identifier that ensures data integrity within the cube.
* **Foreign/Unique Keys**: Each cube will contain zero, one, or many foreign or unique keys used to connect to other data models/tables.
* **Data Model Representation**: Each data model/table is created as one cube.
* **Reusability**: Each cube can be reused as an input to create views.
* **Integration with BI Tools**: Dimensions and measures within a cube are used to feed data into BI tools for reporting and visualization.

### Cube Data Type

Data type from model or table from warehouse will be generated into Generic Data Type includes:

* String
* Boolean
* Date
* Time
* Integer
* Decimal

### Measures and dimensions

As mentioned above, you create a cube to model a semantic modeling case with your data. When creating a cube, you start by specifying the target tables and defining their relationships. From the available columns in these tables, you extract **dimensions** and further define measures from the dimensions.

* **Dimensions** are non-aggregated columns in your dataset, which you can use to segment or filter your data. They act as descriptive attributes for measures. For instance, dimensions like `order_status` or `payment_method` can filter or categorize orders.
* **Measures** are aggregations performed on columns in your model. They represent metrics or calculations, such as `order_count` (total number of orders) or `average_order_value` (average value of a sale, calculated as `sales amount ÷ order count`). Measures can be final metrics or building blocks for more complex calculations.

With a cube defined, when an end user asks: "What are the monthly revenue this year?". They can construct a data query using:

* Measures: `revenue` (aggregated through using `sum` on orders' `amount`)
* Dimensions: `order_date` dimension with month granularity

## Create Cube

#### Option 1: From Current Project

To create a cube, follow these steps:

{% hint style="warning" %}
Ensure the reference data model has been:

* Generated Schema. Refer to [Model schema](/data-modeling/models/model-schema)
* Materialized in Production environment by creating a pipeline job in Production environment. Refer to [Job](/pipeline/job)
  {% endhint %}

1. In the **Cube** tab, click on the **+** icon and select **New Cube**.
2. In the opened modal:

   1. Select data source. It is defaulted to current project
   2. Select the data models that you would like to create as Cube
   3. Click on **Create** button

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FUmKEFVhsruMborjfBoFg%2Fimage.png?alt=media&amp;token=4f652a2f-5d4e-4a09-a960-6f4f88746608" alt=""><figcaption></figcaption></figure>
3. Cube(s) created successfully under Cube folder.
4. In the **Fields** pane, mouse over to the dimension that can be uniquely identify the record in the cube and click on **...**, select **Set as Primary Key**.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FY110ghzptMOOD0LNYHGi%2Fimage.png?alt=media&amp;token=73ccd43c-c874-4c5f-bbda-051acb148af9" alt=""><figcaption></figcaption></figure>

#### Option 2: From Data Warehouse Connection

{% hint style="info" %}
Please ensure the Production Environment Data Connection of the Analytics Databases has been set up. Refer to [Connections](/connections/destinations)
{% endhint %}

1. In the **Cube** tab, click on the **+** icon and select **New Cube**.
2. In the opened modal:

   1. Select **Warehouse**.
   2. Select the tables that you would like to create as Cube

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FIf3X55cZOytWxL0SmJcn%2Fimage.png?alt=media&amp;token=66e138a8-38c2-4892-b3f5-c9f33c44bb8b" alt=""><figcaption></figcaption></figure>
3. Cube(s) created successfully under Cube folder.
4. In the **Fields** pane, mouse over to the dimension that can be uniquely identify the record in the cube and click on **...**, select **Set as Primary Key**.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FGvUrQ7yGIALPYF06DD7R%2Fimage.png?alt=media&amp;token=fc5d293a-ff69-4856-befe-5d1fa0f70386" alt=""><figcaption></figcaption></figure>

## Preview Cube Result

In the **Display** pane, you can select the dimensions & measures that you would like to preview cube by clicking on  **+ Add** under the **Fields** section.

You can further filter the data by adding in the dimensions or measures into the **Filter** section and sort by selected field under **Sort** Section.

Click on **Preview** button to preview the result of the selected fields & criteria.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FIQLgwPL7Ozb8hlAK3BJs%2Fimage.png?alt=media&amp;token=e8329569-e600-4c29-9d94-9a7503bb7c0f" alt=""><figcaption></figcaption></figure>

Corresponding to the preview result on the selected fields & conditions, the SQL will be generated on the **Generated SQL** tab.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FDXSRx6xV8RlNZMhvxqVD%2Fimage.png?alt=media&amp;token=d093aa4b-87c0-4432-9c43-aac12be8c19c" alt=""><figcaption></figcaption></figure>

## Organize Cubes

You can organize the cubes into folders that reflect the analysis area and help maintain a clean project structure.

To create a new folder, click on the action button of an existing folder and select **Add sub-folder**:

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FnSkxV8N3q7jDMGQKWtyx%2Fimage.png?alt=media&amp;token=2a44ced2-ca89-4bec-b64c-d0e79b6a5787" alt=""><figcaption></figcaption></figure>

To move a model into the new folder, click on the action button of the model and select **Move to**. Then select the target folder from the list.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FhMQZ5oNKAjcnz9yRvmrN%2Fimage.png?alt=media&amp;token=09e8b5e3-56ab-41bf-a7c5-a9c26a2cf732" alt=""><figcaption></figcaption></figure>

<br>


# Custom Dimension

## Overview

A **Custom Dimension** in ReOrc allows users to define new categorical fields within a Cube that do not exist directly in the underlying data model. Custom Dimensions enhance analytical capabilities by enabling additional grouping, filtering, and segmentation of data.

## What is Custom Dimension?

A **Custom Dimension** is a user-defined field that categorizes data based on computed logic, transformations, or predefined criteria. These dimensions help refine analyses without modifying the raw dataset.

## Use Cases

Custom Dimensions are used when:

* **Derived Categorization**: Creating new classifications, such as grouping age into "Youth," "Adult," and "Senior."
* **Conditional Labels**: Assigning custom labels based on business rules, such as "High Value Customer" for those with purchases over a threshold.
* **Combining Attributes**: Merging multiple fields into a single dimension, like concatenating `Region` and `Sales Territory`.
* **Data Standardization**: Normalizing values across different datasets to ensure consistency.

## Create a Custom Dimension

To create a custom dimension, follow these steps:

{% hint style="info" %}
Ensure the cube's primary key has been set before proceed to create the custom dimension. Refer [Cube](/semantic-modeling/cube#create-cube)
{% endhint %}

1. Click on **+** button, select **Add a dimension**

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FGDHukXCvxDz7KNaOcqzZ%2Fimage.png?alt=media&amp;token=e5d587ba-88cf-45bd-962c-7109bd568a58" alt=""><figcaption></figcaption></figure>

2. Fill in the details in the modal:
   1. **Field label** will be auto populate based on the Field name&#x20;
   2. When entering the **custom formula**, you can click on the fields on the list to auto populate into the formula box.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FAcQ2x133hBuExCRlA1oY%2Fimage.png?alt=media&amp;token=ac4c04b1-7c9d-4e91-a4d5-6bac4a4d73cd" alt=""><figcaption></figcaption></figure>

3. Click on **Validate** button to validate the formula

{% hint style="warning" %}
Ensure that the custom formula matches the type of database connected.
{% endhint %}

4. Once no error detected, click on **Add** button to add the custom dimension into the cube.


# Custom Measure

## Overview

A **Custom Measure** in ReOrc enables users to create new numerical calculations within a Cube, enhancing data analysis and reporting capabilities. These measures help define key business metrics that may not exist explicitly in the raw dataset.

## What is Custom Measure?

A **Custom Measure** is a user-defined metric derived from existing fields using aggregation, mathematical operations, or conditional logic. These measures help refine insights and provide additional flexibility in data analysis.

## Use Cases

* **New Business Metrics**: Defining KPIs such as "Profit Margin" using (`(Revenue - Cost) / Revenue`).
* **Conditional Aggregations**: Creating measures like "High-Value Orders" for transactions above a certain amount.
* **Ratio & Percentage Calculations**: Computing values like "Conversion Rate" as (`(Total Sales / Total Visitors) * 100`).
* **Custom Weighting**: Applying business rules to weigh certain values differently in calculations.

## Create a Custom Measure

To create a custom dimension, follow these steps:

{% hint style="info" %}
Ensure the cube's primary key has been set before proceed to create the custom dimension. Refer [Cube](/semantic-modeling/cube#create-cube)
{% endhint %}

1. Click on **+** button, select **Add a measure**

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FGDHukXCvxDz7KNaOcqzZ%2Fimage.png?alt=media&amp;token=e5d587ba-88cf-45bd-962c-7109bd568a58" alt=""><figcaption></figcaption></figure>

2. Fill in the details in the modal:

   1. **Field label** will be auto populate based on the Field name&#x20;
   2. When entering the **custom formula**, you can click on the fields on the list to auto populate into the formula box.
   3. For **Aggregations** and sample use case, refer to [Aggregation Function](/semantic-modeling/cube/custom-measure/aggregation-function)

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Fs2gTfnEb8JbcrYlh9F4R%2Fimage.png?alt=media&amp;token=df2d60fb-f824-42e7-b0b9-34a7d2ab2710" alt=""><figcaption></figcaption></figure>
3. Click on **Validate** button to validate the formula

{% hint style="warning" %}
Ensure that the custom formula matches the type of database connected.
{% endhint %}

4. Once no error detected, click on **Add** button to add the custom dimension into the cube.


# Aggregation Function

Aggregation functions are essential for summarizing data in meaningful ways when creating a measure. These functions operate on a set of values and return a single summarized result.

### Supported Aggregation Functions

ReOrc supports the following aggregation functions:

#### 1. `SUM`

Calculates the total sum of a numeric field.

**Example:**

```
SUM(revenue)
```

*Returns the total revenue across all records.*

#### 2. `COUNT`

Counts the number of records.

**Example:**

```
COUNT(order_id)
```

*Returns the total number of orders.*

#### 3. `COUNT DISTINCT`

Counts the number of unique values in a field.

**Example:**

```
COUNT_DISTINCT(customer_id)
```

*Returns the number of unique customers.*

#### 4. `AVG`

Computes the average value of a numeric field.

**Example:**

```
AVG(order_amount)
```

*Returns the average order amount.*

#### 5. `MIN`

Finds the smallest value in a field.

**Example:**

```
MIN(price)
```

*Returns the lowest product price.*

#### 6. `MAX`

Finds the largest value in a field.

**Example:**

```
MAX(price)
```

*Returns the highest product price.*

#### 7. `CUSTOM`

Allows users to define their own aggregation logic using formulas.

**Example:**

```
SUM(revenue) / COUNT(order_id)
```

*Calculates the average revenue per order.*

### Usage in Measures

When defining a measure, an aggregation function must be specified to determine how the data should be summarized. Below is an example of how an aggregation function is used to define a measure:

```
measures:
  - name: total_revenue
    label: "Total Revenue"
    type: number
    aggregation: SUM
    expression: "SUM(revenue)"
```

This measure calculates the total revenue by summing up all revenue values.


# SQL functions and operators

ReOrc's semantic layer translates user-defined queries into the SQL dialect of your underlying data source. However, due to differences in SQL syntax and the need for query transformation, certain SQL functions and operators may not be fully supported—particularly within query fragments that perform `SELECT` operations directly from tables.

To ensure compatibility and consistent behavior, ReOrc provides a defined set of supported SQL functions and expressions. Below is the list of currently supported functions:

<table data-header-hidden><thead><tr><th width="170.94921875" valign="top">Function</th><th width="122.10546875">Type<select><option value="zhDmiw8qTFlI" label="Comparison" color="blue"></option><option value="As5AflgHCCXp" label="Mathematical functions" color="blue"></option><option value="xV8dkaluYUBl" label="Trigonometric functions" color="blue"></option><option value="YiV5ITDu2MkB" label="String functions" color="blue"></option><option value="Iw4kcwlUsxJs" label="Pattern matching" color="blue"></option><option value="bycEbco7IBY3" label="Data type" color="blue"></option><option value="MkZSpUEZz38X" label="Date/time functions" color="blue"></option><option value="Lhk8pDQ80hoZ" label="Conditional expressions" color="blue"></option><option value="GNRJRYMRsFGH" label="Aggregate functions" color="blue"></option><option value="OF7ZAxUos2zj" label="Row and array" color="blue"></option></select></th><th valign="top">Description</th></tr></thead><tbody><tr><td valign="top">&#x3C;</td><td><span data-option="zhDmiw8qTFlI">Comparison</span></td><td valign="top">Returns TRUE if the first value is less than the second</td></tr><tr><td valign="top">></td><td><span data-option="zhDmiw8qTFlI">Comparison</span></td><td valign="top">Returns TRUE if the first value is greater than the second</td></tr><tr><td valign="top">&#x3C;=</td><td><span data-option="zhDmiw8qTFlI">Comparison</span></td><td valign="top">Returns TRUE if the first value is less than or equal to the second</td></tr><tr><td valign="top">>=</td><td><span data-option="zhDmiw8qTFlI">Comparison</span></td><td valign="top">Returns TRUE if the first value is greater than or equal to the second</td></tr><tr><td valign="top">=</td><td><span data-option="zhDmiw8qTFlI">Comparison</span></td><td valign="top">Returns TRUE if the first value is equal to the second</td></tr><tr><td valign="top">&#x3C;> or !=</td><td><span data-option="zhDmiw8qTFlI">Comparison</span></td><td valign="top">Returns TRUE if the first value is not equal to the second</td></tr><tr><td valign="top">ABS</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Absolute value</td></tr><tr><td valign="top">CEIL</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Nearest integer greater than or equal to argument</td></tr><tr><td valign="top">DEGREES</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Converts radians to degrees</td></tr><tr><td valign="top">EXP</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Exponential (e raised to the given power)</td></tr><tr><td valign="top">FLOOR</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Nearest integer less than or equal to argument</td></tr><tr><td valign="top">LN</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Natural logarithm</td></tr><tr><td valign="top">LOG</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Base 10 logarithm</td></tr><tr><td valign="top">LOG10</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Base 10 logarithm (same as LOG)</td></tr><tr><td valign="top">PI</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Approximate value of π</td></tr><tr><td valign="top">POWER</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">a raised to the power of b</td></tr><tr><td valign="top">RADIANS</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Converts degrees to radians</td></tr><tr><td valign="top">ROUND</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Rounds v to s decimal places</td></tr><tr><td valign="top">SIGN</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Sign of the argument (-1, 0, or +1)</td></tr><tr><td valign="top">SQRT</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Square root</td></tr><tr><td valign="top">TRUNC</td><td><span data-option="As5AflgHCCXp">Mathematical functions</span></td><td valign="top">Truncates to integer (towards zero)</td></tr><tr><td valign="top">ACOS</td><td><span data-option="xV8dkaluYUBl">Trigonometric functions</span></td><td valign="top">Inverse cosine, result in radians</td></tr><tr><td valign="top">ASIN</td><td><span data-option="xV8dkaluYUBl">Trigonometric functions</span></td><td valign="top">Inverse sine, result in radians</td></tr><tr><td valign="top">ATAN</td><td><span data-option="xV8dkaluYUBl">Trigonometric functions</span></td><td valign="top">Inverse tangent, result in radians</td></tr><tr><td valign="top">ATAN2</td><td><span data-option="xV8dkaluYUBl">Trigonometric functions</span></td><td valign="top">Inverse tangent of y/x, result in radians</td></tr><tr><td valign="top">COS</td><td><span data-option="xV8dkaluYUBl">Trigonometric functions</span></td><td valign="top">Cosine, argument in radians</td></tr><tr><td valign="top">COT</td><td><span data-option="xV8dkaluYUBl">Trigonometric functions</span></td><td valign="top">Cotangent, argument in radians</td></tr><tr><td valign="top">SIN</td><td><span data-option="xV8dkaluYUBl">Trigonometric functions</span></td><td valign="top">Sine, argument in radians</td></tr><tr><td valign="top">TAN</td><td><span data-option="xV8dkaluYUBl">Trigonometric functions</span></td><td valign="top">Tangent, argument in radians</td></tr><tr><td valign="top">||</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Concatenates two strings</td></tr><tr><td valign="top">BTRIM</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Removes characters from start and end of string</td></tr><tr><td valign="top">BIT_LENGTH</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Returns number of bits in the string</td></tr><tr><td valign="top">CHAR_LENGTH</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Returns number of characters in the string</td></tr><tr><td valign="top">LOWER</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Converts the string to all lower case</td></tr><tr><td valign="top">LTRIM</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Removes characters from the start of string</td></tr><tr><td valign="top">OCTET_LENGTH</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Returns number of bytes in the string</td></tr><tr><td valign="top">POSITION</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Returns index of substring within string</td></tr><tr><td valign="top">RTRIM</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Removes characters from the end of string</td></tr><tr><td valign="top">SUBSTRING</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Extracts the substring of string</td></tr><tr><td valign="top">TRIM</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Removes characters from start, end, or both ends</td></tr><tr><td valign="top">UPPER</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Converts the string to all upper case</td></tr><tr><td valign="top">ASCII</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Returns the numeric code of the first character</td></tr><tr><td valign="top">CONCAT</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Concatenates all arguments</td></tr><tr><td valign="top">LEFT</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Returns first n characters (or all but last ABS(n))</td></tr><tr><td valign="top">REPEAT</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Repeats string the specified number of times</td></tr><tr><td valign="top">REPLACE</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Replaces all occurrences of a substring</td></tr><tr><td valign="top">RIGHT</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Returns last n characters (or all but first ABS(n))</td></tr><tr><td valign="top">STARTS_WITH</td><td><span data-option="YiV5ITDu2MkB">String functions</span></td><td valign="top">Returns TRUE if string starts with prefix</td></tr><tr><td valign="top">LIKE</td><td><span data-option="Iw4kcwlUsxJs">Pattern matching</span></td><td valign="top">Returns TRUE if the string matches the pattern</td></tr><tr><td valign="top">REGEXP_SUBSTR</td><td><span data-option="Iw4kcwlUsxJs">Pattern matching</span></td><td valign="top">Returns substring matching regex pattern</td></tr><tr><td valign="top">TO_CHAR</td><td><span data-option="bycEbco7IBY3">Data type</span></td><td valign="top">Converts timestamp to string by format</td></tr><tr><td valign="top">DATE_ADD</td><td><span data-option="MkZSpUEZz38X">Date/time functions</span></td><td valign="top">Adds interval to a timestamp</td></tr><tr><td valign="top">DATE_TRUNC</td><td><span data-option="MkZSpUEZz38X">Date/time functions</span></td><td valign="top">Truncates timestamp to specified precision</td></tr><tr><td valign="top">DATEDIFF</td><td><span data-option="MkZSpUEZz38X">Date/time functions</span></td><td valign="top">Difference between date parts of expressions</td></tr><tr><td valign="top">EXTRACT</td><td><span data-option="Iw4kcwlUsxJs">Pattern matching</span></td><td valign="top">Retrieves subfields like year or hour</td></tr><tr><td valign="top">LOCALTIMESTAMP</td><td><span data-option="MkZSpUEZz38X">Date/time functions</span></td><td valign="top">Returns current date and time without time zone</td></tr><tr><td valign="top">NOW</td><td><span data-option="MkZSpUEZz38X">Date/time functions</span></td><td valign="top">Returns current date and time with time zone</td></tr><tr><td valign="top">CASE</td><td><span data-option="Lhk8pDQ80hoZ">Conditional expressions</span></td><td valign="top">Generic conditional expression</td></tr><tr><td valign="top">COALESCE</td><td><span data-option="Lhk8pDQ80hoZ">Conditional expressions</span></td><td valign="top">Returns the first non-NULL argument</td></tr><tr><td valign="top">NULLIF</td><td><span data-option="Lhk8pDQ80hoZ">Conditional expressions</span></td><td valign="top">Returns NULL if arguments are equal</td></tr><tr><td valign="top">GREATEST</td><td><span data-option="Lhk8pDQ80hoZ">Conditional expressions</span></td><td valign="top">Selects the largest value</td></tr><tr><td valign="top">LEAST</td><td><span data-option="Lhk8pDQ80hoZ">Conditional expressions</span></td><td valign="top">Selects the smallest value</td></tr><tr><td valign="top">AVG</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Average of non-NULL input values</td></tr><tr><td valign="top">COUNT</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Counts non-NULL input rows</td></tr><tr><td valign="top">COUNT(DISTINCT)</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Counts unique non-NULL input values</td></tr><tr><td valign="top">MAX</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Maximum of non-NULL input values</td></tr><tr><td valign="top">MIN</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Minimum of non-NULL input values</td></tr><tr><td valign="top">SUM</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Sum of non-NULL input values</td></tr><tr><td valign="top">MEASURE</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Works with measures of any type</td></tr><tr><td valign="top">COVAR_POP</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Population covariance</td></tr><tr><td valign="top">COVAR_SAMP</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Sample covariance</td></tr><tr><td valign="top">STDDEV_POP</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Population standard deviation</td></tr><tr><td valign="top">STDDEV_SAMP</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Sample standard deviation</td></tr><tr><td valign="top">VAR_POP</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Population variance</td></tr><tr><td valign="top">VAR_SAMP</td><td><span data-option="GNRJRYMRsFGH">Aggregate functions</span></td><td valign="top">Sample variance</td></tr><tr><td valign="top">IN</td><td><span data-option="OF7ZAxUos2zj">Row and array</span></td><td valign="top">TRUE if value matches any from a list</td></tr><tr><td valign="top">NOT IN</td><td><span data-option="OF7ZAxUos2zj">Row and array</span></td><td valign="top">TRUE if value matches none from a list</td></tr></tbody></table>


# Calculating Period-over-Period Changes

### **Use Case**

Calculating period-over-period changes is essential for tracking trends and growth in key business metrics such as clicks, orders, and revenue. This guide explains how to compute period-over-period comparisons, such as week-over-week or month-over-month changes, using Reorc's semantic capabilities.

### Example: Month-over-Month Change Calculation

To calculate a period-over-period metric in Reorc, follow these steps:

**Step 1: Create the Base Measure**

* Add a new measure, `no_of_member`, and define the formula. For example, use `COUNT(DISTINCT member_id)` to count distinct members.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FsJG9oK3kgjqsRdDbzg4B%2Fimage.png?alt=media&amp;token=cc80751c-8447-4d26-9eb5-e6ed72e8e09f" alt="" width="375"><figcaption></figcaption></figure>

**Step 2: Create the Compared Measure**

* Add another measure, for example, `no_of_member_lm` having the same formula with base measure
* Enable the **Reporting Period** feature and set the time range to **Last Month**.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FnnbEZUmizquRWuVYbgn8%2Fimage.png?alt=media&amp;token=919fc7ef-bddb-44d0-9494-c8e85ed6e81c" alt="" width="375"><figcaption></figcaption></figure>

**Step 3: Calculate the Period-over-Period Change**

* Create a new measure that calculates the change between the current month and the last month.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FFpag7iZhymW9XwfAdJcZ%2Fimage.png?alt=media&amp;token=2bb1f23b-9a5b-4a42-94e5-750e6184f672" alt="" width="375"><figcaption></figcaption></figure>

### **Conclusion**

Reorc's rolling\_window feature allows for flexible and efficient calculation of period-over-period changes. By defining reporting period and calculated measures, users can easily track performance over time and derive meaningful insights from their data.


# Relationship

## Overview

A **Relationship** in ReOrc defines how different Cubes are connected, enabling seamless data integration and enhancing analytical capabilities. Establishing relationships between Cubes ensures consistency, improves query performance, and facilitates the creation of meaningful Views.

## Concept of Relationship

A **Relationship** represents the logical connection between two or more Cubes based on common keys. These relationships allow data from multiple Cubes to be combined, enabling cross-referencing and enriched analysis.

#### Types of Relationships:

* **One-to-One (1-1)**: Each record in one Cube corresponds to exactly one record in another Cube.
* **One-to-Many (1-n) or Many to One(n-1)**: A single record in one Cube is associated with multiple records in another Cube.

## Why Setup a Relationship?

#### **For View Creation**

* Relationships allow Views to aggregate and display data from multiple Cubes seamlessly.
* Enables pre-joined datasets that improve performance in BI tools.

#### **For Data Consistency and Integrity**

* Ensures correct data linkage across different datasets.
* Reduces redundancy and improves maintainability.

#### **For Enhanced Query Performance**

* Predefined relationships optimize query execution by reducing the need for complex joins at runtime.
* Improves efficiency by leveraging indexed relationships for faster data retrieval.

## Define Relationships

To define the relationship between cube, follow these steps:

{% hint style="info" %}
Ensure the cube's primary key has been set before proceed to create the custom dimension. Refer [Cube](/semantic-modeling/cube#create-cube)
{% endhint %}

1. Click on the **Edit Relationship** button, the relationship modal will be shown

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F44GZgj37QoOlCWkOGCH0%2Fimage.png?alt=media&amp;token=c8a91500-fd85-40ff-b25e-5f79e07ec187" alt=""><figcaption></figcaption></figure>

2. Click on **Add Relationship** to start add a new row of the relationship between cube.
3. Select the Relationship Type, From and To fields in the list and click on **Add** button.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FgZ6VgtekZWFTa8Tl2OtL%2Fimage.png?alt=media&amp;token=0bf05ea8-4e54-4142-a5e8-47e0c646327e" alt=""><figcaption></figcaption></figure>

4. Once the relationships have been defined, click on the **Save** button to save all the relationships created.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FuiacNGkkK6lHYssMmqPm%2Fimage.png?alt=media&amp;token=aa511be3-6609-4031-b6ee-13e61c5650df" alt=""><figcaption></figcaption></figure>


# View

## Overview

A **View** in Recurve is a virtual representation of structured data that enables flexible and efficient data access without duplicating or modifying the underlying source. Unlike Cubes, which focus on organizing raw data into measures and dimensions, Views serve as a refined analytical layer where multiple data sources can be combined, enriched, and optimized for reporting and analysis.

Views are essential for:

* **Aggregating and Reshaping Data**: Views enable dynamic structuring of data across multiple Cubes to align with specific business needs.
* **Combining Data Across Domains**: Views allow users to integrate data from different projects and subject areas into a unified analytical dataset.
* **Enhancing Data Usability**: By defining custom-calculated metrics and pre-applied transformations, Views simplify complex queries and improve accessibility for business users.

## View Concept

A View in Recurve operates as an abstraction layer that sits on top of Cubes and Relationships, refining data structure while maintaining flexibility. The core components of a View include:

#### **1. Cube Integration**

Views draw data from one or more Cubes, utilizing their defined dimensions, measures, and relationships. Rather than modifying raw data, Views structure and optimize it for analytical consumption.

#### **2. Relationship Mapping**

Views leverage predefined Relationships between Cubes, ensuring that data joins are optimized and queries run efficiently. This allows users to analyze data across multiple domains without manual SQL joins.

#### **3. Cross-Project Connectivity**

Unlike Cubes, Views can pull in data from other projects within Recurve, enabling broader data integration and cross-functional reporting.

#### **4.Shared fields (dimensions & measures)**

One of the key differentiators of Views is the ability to define **Calculated Dimensions & Measures** that are not inherently present in Cubes. These include:

* Derived business KPIs (e.g., Customer Retention Rate, Net Profit Margin)
* Custom aggregations (e.g., Rolling 12-Month Sales)
* Advanced filtering logic to segment data dynamically

### Linking Components Together

The strength of Views lies in how they connect multiple semantic components:

* **Cubes serve as foundational data structures** containing key business metrics and dimensions.
* **Relationships define how different Cubes interact**, ensuring data consistency.
* **Views act as an analytical layer**, refining and restructuring Cube data to fit business needs & requirements.
* **Calculated Metrics enhance Views**, enabling users to derive deeper insights without modifying base datasets.

By leveraging Views, users can efficiently model complex business logic, integrate disparate data sources, and create highly optimized datasets for analysis, ensuring a seamless analytical experience.

## Create a View

To create a view, follow these steps:

1. In the **Cube** tab, click on the **+** icon and select **New View**.
2. In the opened modal,&#x20;
   1. Enter the view name
   2. Select the Dimensions & Measures that you would like to create as View.
   3. Click on **Create** button

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FCZbM0yscgfhdtDlXvt4W%2Fimage.png?alt=media&amp;token=e5143c00-308c-48b6-92b2-909e31132a90" alt=""><figcaption></figcaption></figure>

3. View created successfully under View folder.

## Create a View (Reference cube from other projects)

{% hint style="info" %}
Recurve only support reference to other project's cubes that are created under the same connection, refer to [1. Set up a connection](/getting-started/1.-set-up-a-connection)
{% endhint %}

Follow these steps to create a view which referencing other project's dimensions & measures:

1. Ensure the other project that you would like to refer has been connected in **Dependencies**. Refer to [Packages and dependencies](/asset-management/packages-and-dependencies#manage-dependencies)

2. In the **Cube** tab, click on the **+** icon and select **New View**.

3. In the opened modal,&#x20;

   1. Enter the view name
   2. Select the Dimensions & Measures that you would like to create as View. You can also select dimensions & measures from other project in the list.
   3. Click on **Create** button

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FGsts2trC0sQkd0rtHlKX%2Fimage.png?alt=media&amp;token=2af29837-3f82-48c0-8535-e6c09be30548" alt=""><figcaption></figcaption></figure>

4. View created successfully under View folder.

5. Click on Edit Relationship and define the relationship with reference cube from other project. Refer [Relationship](/semantic-modeling/cube/relationship#define-relationships)

## Update View

If you would like to Add/Remove the dimensions and measures of the existing view, follow these steps:

1. Click on ![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FoiNAgnolnwPFfQn0WC13%2Fimage.png?alt=media\&token=f71b400a-dcbe-43f0-affe-d550c2019485)at the **Fields** pane of the existing view.
2. Select/Deselect the dimensions & measures in the opened modal and click on **Update** button.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FlNk7XubHwTUpmWSKgjtz%2Fimage.png?alt=media&amp;token=ec5c9d41-899d-4c1a-875d-f7edbc53a51c" alt=""><figcaption></figcaption></figure>

## Preview View Result

In the **Display** pane, you can select the dimensions & measures that you would like to preview **view** by clicking on  **+ Add** under the **Fields** section.

You can further filter the data by adding in the dimensions or measures into the **Filter** section and sort by selected field under **Sort** Section.

Click on **Preview** button to preview the result of the selected fields & criteria.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F5xpTimZvQgwfEzoxScdd%2Fimage.png?alt=media&amp;token=e62386f2-2094-4893-9694-ec39d53937c3" alt=""><figcaption></figcaption></figure>

Corresponding to the preview result on the selected fields & conditions, the SQL will be generated on the **Generated SQL** tab.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FQNpTZKIFW4XRNMiX6r9U%2Fimage.png?alt=media&amp;token=54916296-f9a7-4645-a4b0-80079d9381c9" alt=""><figcaption></figcaption></figure>

## Organize Views

You can organize the Views into folders that reflect the analysis area and help maintain a clean project structure.

To create a new folder, click on the action button of an existing folder and select **Add sub-folder**:

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FKaSABfhP0JxvuFxFujHH%2Fimage.png?alt=media&amp;token=78426ab8-5771-4119-959f-e7d7b42dbffb" alt=""><figcaption></figcaption></figure>

To move a model into the new folder, click on the action button of the model and select **Move to**. Then select the target folder from the list.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FxvltvH7OFBF1pnn63zIg%2Fimage.png?alt=media&amp;token=1a39dd1f-17d8-40e5-b5b6-69b61b5e6e72" alt=""><figcaption></figcaption></figure>


# Primary Dimension

## Overview

The **Primary Dimension** in ReOrc Views serves as the key identifier that defines the root Cube for the join path. It establishes a structured relationship for combining multiple data sources, ensuring accurate and efficient data retrieval.

### Purpose of the Primary Dimension

* **Defines the Root Cube**: Determines the starting point for joining multiple Cubes within the View.
* **Ensures Consistent Data Relationships**: Helps maintain a structured and logical data flow by guiding how joins are applied across related datasets.
* **Optimizes Query Performance**: Provides a predefined path for data aggregation, reducing unnecessary joins and improving efficiency.
* **Supports Business Logic**: Ensures that the View aligns with reporting needs by structuring data based on the most relevant business entity.

### Impact of Primary Dimension on Query Results

The choice of Primary Dimension can significantly influence the outcome of queries and reports. Below are examples of how it affects results:

#### **Example 1: Customer-Centric vs. Order-Centric View**

* **Primary Dimension: `Customer ID`**
  * The View will group data around customers.
  * Aggregations such as total spend per customer will be calculated at the customer level.
  * A customer with multiple orders will have their data merged, displaying cumulative totals.
  * Order without customers will not be show in this scenario.
* **Primary Dimension: `Order ID`**
  * The View will group data by individual orders.
  * Each order will be treated as a separate record, displaying order-level details.
  * Orders without customer will be available.

#### **Example 2: Sales Data with Different Primary Dimensions**

* **Primary Dimension: `Product ID`**
  * The View will show total sales grouped by product.
  * Metrics like average revenue per product will be straightforward to compute.
* **Primary Dimension: `Region ID`**
  * The View will aggregate sales data based on geographical regions.
  * Queries will focus on regional trends rather than product-level sales.

## Set Primary Dimension

To set primary dimension for a view, mouse over to the dimension that you would like to set as the primary dimension and click on **...**, select **Set as primary dimension**

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Fi0Zf8gL3nX7JLvPVGb8H%2Fimage.png?alt=media&amp;token=5a19a0ed-c35c-4b86-a71e-c2271ae70d87" alt=""><figcaption></figcaption></figure>


# Add Shared Fields

Refer to [Shared Fields](/semantic-modeling/shared-fields) to understand more.

## Add to View

{% hint style="info" %}
Refer to [Shared Fields](/semantic-modeling/shared-fields#create-a-shared-fields) on how to create a shared fields.
{% endhint %}

To add the shared fields into the existing View, follow these steps:

1. Click on ![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FoiNAgnolnwPFfQn0WC13%2Fimage.png?alt=media\&token=f71b400a-dcbe-43f0-affe-d550c2019485)at the **Fields** pane of the existing view.
2. Select the shared fields from the Shared field folder in the opened modal and click on **Update** button.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F4sg673LcQSXltC0HVEFe%2Fimage.png?alt=media&amp;token=b5d6a876-d9cb-4229-8119-53b883dbcda2" alt=""><figcaption></figcaption></figure>

## Manage Relationship

If the shared field added to view is from other projects, then you will need to define the relationship of the underlying cube that used to create this shared fields into current project. Refer [Relationship](/semantic-modeling/cube/relationship#define-relationships)


# Shared Fields

## Overview

Shared Fields in ReOrc enable users to define reusable dimensions and measures that can be applied across multiple cubes and projects' cubes within the semantic layer. These standardized fields ensure consistency, improve efficiency, and provide a unified analytical experience across various datasets.

## Concepts

#### 1. **Cross-Cube Calculation Enablement**

* The key purpose of Shared Fields is to enable cross-cube calculations, allowing measures to be derived from multiple cubes.
* Example: `Profit` is calculated using `Revenue` from the `Sales Cube` and `Cost` from the `Finance Cube`, ensuring a standardized approach across reports and dashboards.
* This differs from **Custom Measures/Dimensions**, which are specific to a single cube and already reusable when creating views.

#### 2. **Reusable Dimensions and Measures Across Projects**

* Dimensions: Common attributes (e.g., `Date`, `Customer ID`, `Product Category`) that can be used across different cubes and projects.
* Measures: Aggregated calculations (e.g., `Total Revenue`, `Order Count`, `Average Discount`) that maintain uniform logic across datasets and projects.

#### 3. **Governance and Standardization**

* Provides a centralized approach to managing key business metrics and attributes.
* Reduces inconsistencies caused by different teams defining the same metric differently.

## Use Cases

#### 1. **Cross-Cube Profit Calculation**

* Example: `Profit` is calculated as `Revenue` (from `Sales Cube`) minus `Cost` (from `Finance Cube`).
* Impact: Ensures all financial reports consistently apply the same logic without duplication.

#### 2. **Consistent Business Metrics Across Projects**

* Example: `Total Sales` is defined once and applied across multiple projects, ensuring uniform reporting for regional and global teams.
* Impact: Standardizes metric calculations across different business units.

#### 3. **Cross-Functional Data Analysis**

* Example: `Customer Lifetime Value (CLV)` is derived from `Average Order Value` (from `Sales Cube`) and `Customer Retention Rate` (from `Marketing Cube`).
* Impact: Enables a unified customer analytics strategy by leveraging data from different business domains.

## Impact on Relationships

* **Defining Relationships for Shared Fields:** Users must define relationships between the shared fields (underlying cubes used in the calculation) and the cubes included in the view.
* **Maintains Referential Integrity:** Ensures accurate joins and aggregations when shared fields are used across multiple cubes.
* **Simplifies Data Lineage Tracking:** Provides visibility into how dimensions and measures are connected to different views and reports.
* **Optimizes Data Processing:** Reduces redundancy and enhances the efficiency of data transformation and computation.

## Create a Shared fields

To create s shared fields, follow these steps:

1. In the **Cube** tab, click on the **+** icon and select **New shared dimension or New shared measure**.
2. Fill in the details in the modal and click on **Create** button.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FqzEUZSqNo5ewbIWz6STV%2Fimage.png?alt=media&amp;token=e59110d1-52be-4f47-a219-f07eebe6dd8b" alt=""><figcaption></figcaption></figure>

3. Fill in the details:
   1. **Field label** will be auto populate based on the Field name&#x20;
   2. When entering the **custom formula**, you can click on the fields on the list to auto populate into the formula box.
   3. For **Aggregations** and sample use case, refer to [Aggregation Function](/semantic-modeling/cube/custom-measure/aggregation-function)

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FbcMsAj5w8xZTSYBDhbzZ%2Fimage.png?alt=media&amp;token=be53ff30-298d-4661-a9e4-f0da3e5e2ca8" alt=""><figcaption></figcaption></figure>

4. Click on **Validate** button to validate the formula

{% hint style="warning" %}
Ensure that the custom formula matches the type of database connected.
{% endhint %}

5. Once no error detected, click on **Add** button to add the custom dimension into the cube.

## Organize Shared fields

You can organize the shared into folders that reflect the analysis area and help maintain a clean project structure.

To create a new folder, click on the action button of an existing folder and select **Add sub-folder**:

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FfplAWk0fT6G5co6pTSnj%2Fimage.png?alt=media&amp;token=11700ca8-a149-437e-afe1-94934429f167" alt=""><figcaption></figcaption></figure>

To move a model into the new folder, click on the action button of the model and select **Move to**. Then select the target folder from the list.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FD5nQ8DdNh6kF71dX2OTY%2Fimage.png?alt=media&amp;token=db8d0ab7-4b25-46c8-9ab1-ad2f9237f70a" alt=""><figcaption></figcaption></figure>


# Integration

## Overview

ReOrc Semantic provides a centralized semantic layer to standardize business metrics and definitions. It currently supports integration with Business Intelligence (BI) tools via PostgreSQL, enabling seamless data access and query execution.

## Integration with BI Tools

ReOrc Semantic can be accessed through any BI tool that supports PostgreSQL connections. Users can connect to the semantic layer using the same credentials they use to log in to ReOrc.

### Steps to Connect

1. Navigate to Project **Settings, Semantic layer integration**
2. Connection details as shown in the page, copy each of the details into the BI tools to establish the connection to ReOrc Semantic.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FoaX5OHWthHkXHj0WWkVJ%2Fimage.png?alt=media&amp;token=bca2f7fd-4ecf-455e-9ec5-20233aef9f84" alt=""><figcaption></figcaption></figure>


# Guandata Integration

## Preparation

Before connecting to a PostgreSQL database, ensure you have collected the following information:

* Database version (minimum requirement: PostgreSQL ≥12.5)
* IP address and port number of the database server
* Database name
* Database username and password
* Connection method
* Schema name (optional)

## Connection Steps

### Creating a Data Connection Account

1. Log in to Guandata BI.
2. Navigate to **"Data Center" > "Data Accounts"** and click **"New Data Account"**.
3. In the pop-up window, select **"PostgreSQL"** as the account platform.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FvDPFlxVct0iukkrElRYm%2Fimage.png?alt=media&amp;token=ffff4b23-184a-4931-87a3-6e980c2d9b63" alt=""><figcaption></figcaption></figure>

### **Creating a Dataset**

**Selecting the Connector**

1. Go to **"Data Center" > "Datasets"**, then click **"+ New Dataset"**.
2. Choose **"Database"** as the data source type.
3. In the **"Select Connector"** step, choose **"PostgreSQL"**, then click **Next**.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Fub0SadjTm0KwTKsmXcrf%2Fimage.png?alt=media&amp;token=9897bde0-408d-411e-81b7-7aacd8e2df8c" alt=""><figcaption></figcaption></figure>

### **Selecting Data Tables**

1. Select an existing data account from the dropdown menu.
2. Choose the desired database table.&#x20;

Once data preview is successful, proceed to the next step.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FnN3guUgyBTuZwGAZbtJw%2Fimage.png?alt=media&amp;token=2eabf66f-dd6e-4289-836e-37a093646d89" alt=""><figcaption></figcaption></figure>

### **Database Connection and Update Settings**

Guandata supports two types of database connections: **Direct Connection** and **Guan-Index**. In our case, please choose Direct Connection.

### **Confirming Dataset Information**

At this stage, users can finalize the dataset name, storage location, and field settings.

* **Dataset Name & Storage Location**: Assign a clear and recognizable name to the dataset and choose where to store it. After confirmation, the dataset will appear in **"Data Center" > "Datasets"**. (For Guan-Index datasets, there may be a delay before data extraction is complete).
* **Field Renaming**: Users can rename fields by clicking the dropdown arrow next to the field name.

### **Using the Dataset**

Once the dataset is created, users can immediately utilize it for visualization and analysis. Additional dataset settings and management options are available—refer to the **"Dataset"** documentation for more details.


# Looker Studio

Looker Studio connects to Reorc as if it were a PostgreSQL database. To connect to Reorc, navigate to the tool panel and click **"Add data."** In the **"Connect to data"** tab, select **PostgreSQL**, then enter the SQL API credentials.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FE3cbUYIJ4C4299vLrwIQ%2Fimage.png?alt=media&amp;token=f555be32-316e-4482-b61f-e205ef85d096" alt="" width="563"><figcaption></figcaption></figure>

Drag columns from the Data side panel to the Chart side panle to build a report:

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FoCe9VoBJpuvssFdOpbyI%2Fimage.png?alt=media&amp;token=1d3e4fb6-45f7-4046-804c-c07d0b8dd78e" alt="" width="375"><figcaption></figcaption></figure>


# Overview

The **Pipeline** module in ReOrc enables you to orchestrate data workflows efficiently. Rather than manually running models to retrieve results, you can define pipelines that automate the entire data transformation process. Pipelines represent your data workflows, from which you can schedule periodic runs, manage dependencies between models, and monitor workflow status in real time.

In ReOrc, pipeline is a another type of asset that can contain multiple models. When you create a pipeline, ReOrc automatically queries the relationship between models - derived from data lineage - and visualizes them in a directed acyclic graph (DAG).

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FLAhuqNLebB8aJKYxJG6a%2FRecurve_model_pipeline.png?alt=media&amp;token=1e4bb162-24e8-4533-b821-dc25910b18da" alt=""><figcaption></figcaption></figure>

The **Pipeline** module is designed to provide:

* **A high-level view**: Pipelines provide an accessible, high-level visualization of the data workflow, allowing data practitioners and stakeholders to easily understand the workflow's objectives and outcomes.&#x20;
* **End-to-end validation**: Pipelines automatically trigger data tests for models and assets during each run as a form of regression analysis. This helps you identify any issues introduced when chaining together several transformations.
* **Simplified troubleshooting**: Results and logs are instantly displayed in the Pipeline Health dashboard, where you can inspect details of each task to tfarace errors and resolve issues efficiently.

## Key features

The module currently supports the following features:

* [**Modeling pipeline**](/pipeline/modeling-pipeline): Create pipelines from data models.
* [**Job**](/pipeline/job): Configure job and schedule run from pipelines.


# Modeling pipeline

Modeling pipelines are simply pipelines that contain data models. You can create a modeling pipeline to describe a workflow of multiple models and schedule job to periodically run the workflow.

## Create a modeling pipeline

Follow these steps:

1. In your ReOrc project, go to **Data Design** > **Pipelines**.
2. Click on the **+** icon and select **Create modeling pipeline.**
3. Provide the name for your pipeline.
4. Select the models that the pipeline should contain.&#x20;

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FBeCNTgKc4yF8ipxbgPVx%2FRecurve_create_modeling_pipeline.png?alt=media&amp;token=24e32cac-7f93-4d1c-ae3b-1d54c174581d" alt=""><figcaption></figcaption></figure>
5. In **Variable settings**, you can view the list of variables associated with the models.&#x20;

   On each variable, you can decide to lock the current value; this applies to dynamic variables, such as current datetime. You can also provide a custom value.
6. Click **Confirm**.

   The new modeling pipeline is then added under the **Models** folder and presented in the DAG view

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F7hRucyNxu44lBH5InzH2%2FRecurve_created_pipeline_dag.png?alt=media&amp;token=4dac97d9-a3ce-48f9-922b-be373d9b10e8" alt=""><figcaption></figcaption></figure>
7. Click **Publish**.&#x20;

Once the pipeline is created and published, you can start scheduling runs through [Job](/pipeline/job).


# Advanced pipeline

An advanced pipeline is a special type of pipeline that lets you combine multiple operators and modeling pipelines to create complex data transformation workflows.

**Operators** are the fundamental units used by the ReOrc orchestrator to perform tasks. In a modeling pipeline, each model is an operator that transforms data by running SQL queries. In an advanced pipeline, however, you can include other types of operators capable of handling broader tasks, such as:

* Ingesting data from a source to a target data warehouse.
* Running custom SQL queries for ad-hoc transformations.
* Sending notifications at various stages of job execution.

## Create an advanced pipeline

Follow these steps to create an advanced pipeline:

1. Navigate to **Data Design** > **Pipelines** in your ReOrc project.
2. Click the **+** icon and select **Create advanced pipeline**.
3. Enter a name for your pipeline and click **Confirm**.

   An advanced pipeline is created. You’ll now define its nodes and their relationships within the DAG (directed acyclic graph).
4. Click **+ Add node**. Choose an operator or an existing modeling pipeline.

   Each operator has different configuration requirements. See \[documentation link] for details.
5. Define the relationships (execution order) between nodes by clicking and dragging arrows between them.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FAoeqUqhe7vgTXK9J5bkb%2Fconnect_pipeline_node_480.gif?alt=media&amp;token=a11fad72-c383-45f6-8b79-fc1120a1ce4c" alt=""><figcaption></figcaption></figure>

## Operators

### SQL Operator

SQL Operator executes custom queries directly against your data sources. While SQL models focus on transformation logic and dependencies, SQL Operator is ideal for cleaning and preparing data before it enters your modeling pipeline.&#x20;

Configuration:

* Data Source: the target data source. These are the destinations that you've configured in your ReOrc organization.
* Database: the specifc database that you want to run the query.
* SQL Query: the SQL query script, where can you write multiple query statements.

For example, you can use it to clean source tables before transforming them in downstream SQL models.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FHwG7rDZprNv1H4Yp7Axh%2FRecurve_sql_operator_sample.png?alt=media&amp;token=bf9736bf-be6c-466e-8299-2b5ab50edbd6" alt=""><figcaption></figcaption></figure>

### Transfer Operator

The Transfer Operator allows you to move data from one location to another. For example, you can use it to transfer data from BigQuery to Postgres or from Amazon S3 to Google Cloud Storage.

The operator consists of two tasks: Dump and Load. The Dump task fetches data from a source, while the Load task transfers it to a destination. The configuration, authentication, and parameters vary depending on the source and destination.

For example, we use Transfer operator to move data from Google Sheet into our Postgres database, then processs the data in a modeling pipeline:

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FjCDum72KNN4exz3oQDpG%2FRecurve_transfer_operator.png?alt=media&amp;token=37607d35-d37d-43c4-bb34-d4323d25bf7b" alt=""><figcaption></figcaption></figure>

### Python Operator

The Python Operator allows you to integrate Python code into data pipelines. This operator is particularly useful in scenarios such as:

* **Data Processing**: Performing transformations or calculations on datasets.
* **API Interactions**: Making API calls to external services or databases.
* **Custom Logic Implementation**: Executing business logic that may not fit into standard operators like Bash or SQL operators.


# Job

To run a pipeline, you can create a job that describes how it should be executed. Job configuration can include:

* Target environment: Choose between running the pipeline in **development** environment for testing, or applying it in **production** environment after thorough validation.&#x20;
* Schedule time: Select a scheduling strategy for the pipeline, or trigger it manually.
* Variable settings: Configure values for variables referenced in the models&#x20;
* Notifications: Set up notifications for job failures via emails or third-party integrations.

## Tasks

During a job run, every node is wrapped inside a task - the basic unit of work that represents the operation to be performed on the asset. Tasks are executed in a specific order based on the asset's dependencies, which are retrieved the upstream and downstream relationship in the [DAG](/pipeline/overview).

Depending on the pipeline type, the functionality of the task may differ.&#x20;

For modeling pipeline, each task performs two main steps:

1. Materialize the asset: execute the transformation query specified in the asset.
2. Run data tests: run the associated data tests of the asset.

Advanced pipeline can involves various types of operators and transformations, such as the *TransferOperator* for extracting and loading data, or *SQLOperator* for performing ad-hoc data transformation.&#x20;

After a task has finished running, you can inspect the execution logs in [Pipeline health](/health-tracking/pipeline-health#task-details).

By design, when a task fails, the entire job run is also marked as failed and all downstream tasks won't be executed.&#x20;

## Create a job

{% hint style="info" %}
When you create a job from a pipeline, the job registers only the most recently published versions of the pipeline and associated models. To ensure that all changes are included, we recommend publishing the pipeline and models before creating the job.
{% endhint %}

Follow these steps to create a job:

1. From the **Pipelines** tab, select a pipeline.
2. Switch to the **Jobs** tab and click **+ Create a job**.
3. Provide the configuration for the job.

{% tabs %}
{% tab title="1. Detail" %}
Provide the name, select the target environment, and customize the associated model variables.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FlwrtbSzcOG76JFpLPNuA%2FRecurve_create_a_job_detail.png?alt=media&amp;token=37f9b5f8-f8ab-4741-85c8-5178326d4ce0" alt="" width="563"><figcaption></figcaption></figure>
{% endtab %}

{% tab title="2. Schedule" %}
Provide the schedule for the job and the trigger type:

* Standard setup: trigger the run at a specific time between certain intervals.
* Advanced setup: specify the schedule in crontab format, for those familiar with the `cron` scheduler. See: [Cron](https://en.wikipedia.org/wiki/Cron).
* Manually trigger: no scheduling; to be manually triggered in the **Pipeline Health** dashboard.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Fzj7z0amotPwsv6Ev9MoE%2FRecurve_create_a_job_schedule.png?alt=media&amp;token=0211f948-5f46-47b4-9547-5d6ae963f055" alt="" width="563"><figcaption></figcaption></figure>
{% endtab %}

{% tab title="3. Notification" %}
Here you can configure notifications on job failure. By default, notifications are sent by email.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FnzhKrRmACQWo0DuviHwd%2FRecurve_create_a_job_notification.png?alt=media&amp;token=43f13023-3445-4b58-9dc2-7f0efe57f975" alt="" width="563"><figcaption></figcaption></figure>
{% endtab %}
{% endtabs %}

4. Click **Create**.&#x20;

The new job will be displayed in the **Jobs** section.

You can visit the [**Pipeline Health**](/health-tracking/pipeline-health) dashboard to monitor the execution status of the job or, as a shortcut, click on the job name to navigate to **Job details**.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FNCQ5daGgVLzXhHhhHWtg%2FRecurve_jobs_tab.png?alt=media&amp;token=f532d9a4-148b-48d2-ad18-9a628f8caf52" alt=""><figcaption></figcaption></figure>


# Pipeline health

The **Pipeline Health** dashboard provides a project-wide visualization of all pipelines, allowing you to monitor and manage pipelines and jobs efficiently.&#x20;

You can view historical data, and filter pipelines by run status, schedule states, and tags. Inspecting each entry to view details of each pipeline, and perform key actions like triggering, editing, or activating / deactivating the pipelines and jobs

This guide walks you through all components of the **Pipeline Health** dashboard.

To access the dashboard, in your project, click on **Health tracking**.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Fm5EoyBnY5G6qsPd6dss0%2FRecurve_pipeline_health_overview.png?alt=media&amp;token=5c5bb82e-f507-4d43-bd59-2a6f5e2f518e" alt=""><figcaption></figcaption></figure>

## Pipeline charts

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FKCvoSnu3cvaZWZNsQlho%2FRecurve_pipeline_health_charts.png?alt=media&amp;token=1c047c24-96e2-489d-8146-71c4e45ff524" alt=""><figcaption></figcaption></figure>

The **Pipeline distribution** chart represents the total number of pipelines with active jobs distributed across pipeline different categories, and the **Pipeline health trend** displays the total number of pipeline jobs with and their statuses, within a specified timeframe.

## Pipeline and job list

Below pipeline charts is the list of all pipelines and associated jobs.

Here you can use the top search bar to quickly search for pipeline from the list. The sort and filter functions help you navigate and group the pipelines by a combination of tags, owners, and run statuses.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FXsPddgN0yfUsFT36Iwz0%2FRecurve_pipeline_health_pipeline_list.jpg?alt=media&amp;token=3e593061-5b1a-4035-8835-bc7153cbaa4b" alt=""><figcaption></figcaption></figure>

Each pipeline item displays the list of associated jobs and relevant information, including:&#x20;

* Job name
* Environment: development or production.
* Last run time
* Schedule
* Recent runs: the last 14 runs; the height of each bar represents the run duration and its color indicates the status (green for successful and red for failure).&#x20;
* Status toggle: activate or deactivate the job.

## Job details

To view the details of a job, click on the job item's name or click the action button and select **View job details**.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FrKtLjpgcoPuV028bb6pR%2FRecurve_pipeline_health_job_item_click.png?alt=media&amp;token=d4f2215d-30fa-456f-96e3-4ebd6a6dea5a" alt=""><figcaption></figcaption></figure>

### Graph view

By default, ReOrc opens the latest job run details in the graph view. Each node represents a task, with run status and last run time.&#x20;

The graph view provides a visual representation of task dependencies and relationships. It is best used to understand workflow structure and task dependencies at a glance.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Fd5XaP52FkMuM56tW7xLF%2FRecurve_job_detail_graph.png?alt=media&amp;token=0beda31a-40f8-44f7-9f48-d31403938cb9" alt=""><figcaption></figcaption></figure>

A job can have multiple runs over a period of time. To filter, you can use the Date and Run ID filter functions. Using the search bar, you can highlight a task or a group of tasks (nodes).&#x20;

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FfbNhPk0kpCFwiX0gFLK3%2FRecurve_job_detail_filter_and_search.png?alt=media&amp;token=66f8f926-2a5d-4575-a17b-98225c476819" alt=""><figcaption></figcaption></figure>

### Task details

After locating a specific run, you can view the details of a task by clicking on the corresponding node. Task details display two key information in two tabs:

**Query**: the complied query of the model.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FJHYNrbrzvOzRvorlR4CC%2FRecurve_task_details_query.png?alt=media&amp;token=76cdc2d3-0d33-4198-8e0d-e93cb59f8866" alt="" width="563"><figcaption></figcaption></figure>

**Run logs**: details about the materialization process and results of data tests.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FPiisNmOw0ag2sBc3FCYg%2FRecurve_task_details_run_logs.png?alt=media&amp;token=250c691c-5f69-4c43-ba4a-38d4f25080e3" alt="" width="563"><figcaption></figcaption></figure>

### Grid view

Switch to the **Grid** tab to view job details in grid view.

The grid view displays all tasks in the job. Each column represents a job run and the column height indicates the execution duration of the run. Each square represents an individual task run, with color-coded status.&#x20;

Grid view displays tasks in a table format with detailed status and timing. This view is best used for tracking historical runs and comparing task performance across multiple runs.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FerFnLSlJsXWUu00qmGYx%2FRecurve_pipeline_health_job_details_grid_view.png?alt=media&amp;token=40a882f9-0740-420c-9332-0ec386d6e14c" alt=""><figcaption></figcaption></figure>

Using the search bar, you can select a specific group of tasks to focus on. The filter tool allows you to:

* Filter by runs: select a range of runs (last 10, 30, 50 runs, or a customized number).
* Filter by date: display all runs in a specific date range.
* Filter by status: Completed, Failed, In progress, No status.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FW3GaZ0QTLjEj53Z0qhJv%2FRecurve_job_list_grid_view_search_and_filter.png?alt=media&amp;token=3b224277-5366-4b05-b51d-62fbed155217" alt=""><figcaption></figcaption></figure>

Similar to the graph view, you can click on a square to see the corresponding task details.


# Data quality

The Data quality dashboard helps you monitor the health status of data assets in your project. Health status is essentially the interpretation of test results of assets with [test categories](/data-modeling/data-tests#test-categories).

{% hint style="info" %}
**Data quality** dashboard currently supports monitoring data model assets.
{% endhint %}

You can easily view data quality in two ways:

* Get a bird's-eye view through test coverage summaries and quality matrix, or
* Zoom in on specific assets to investigate potential issues in detail.

This guide walks you through the interface of the dashboard.

To access the dashboard, from the top navigation bar, go to **Health tracking** > **Data quality**.

First, the overview page displays two sections: Test coverage and Health matrix, showing data quality of a specific environment.  You can switch between the **Development** and **Production** environments using the toggle in the top-right corner. ReOrc fetches all the assets and health statuses of the environment and reflects in the dashboard.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FvmPCZNmirzIbX1D7xbZA%2Fmockup_data_quality_dashboard.png?alt=media&amp;token=625f97e2-e200-43fb-b328-736346a4527d" alt=""><figcaption></figcaption></figure>

## Test coverage

There are two types of coverages:

* **Monitoring coverage** (pie chart) shows the percentage of models in your project that are being monitored through testing. Higher percentage means more assets are being covered.
* **Monitoring coverage by test category** (horizontal bar chart) breaks down the Monitoring coverage  by showing the percentage of assets with tests in specific categories. This helps identify areas that may lack sufficient testing. For example, high coverage in "Completeness" but lower coverage in "Validity" could indicate that more attention is needed to ensure data accuracy.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FSwYjucZmnllnW5ZXZ3Dt%2FRecurve_data_quality_test_coverage.png?alt=media&amp;token=e940f748-bd29-436c-b4a8-f6b46546eabc" alt=""><figcaption></figcaption></figure>

## Health matrix

The Health Matrix provides a comprehensive view of all monitored assets. Assets are listed vertically, while columns across the top represent the asset owner, materialization status, and each test category.

* **Owner**: displays the owner of each asset, configurable through metadata.
* **Materialization Status**: indicates the current status of materialization (Success, Failed, or No Status if not yet materialized).
* **Test Categories**: each column represents a test category, with each cell showing the health status of the asset in that category (Passed, Warning, or Error).

The matrix allows you to quickly assess health across multiple categories.

By default the the dashboard shows all types of health statuses with data  of the last 14 days. You narrow that down using the **Issues only** toggle and a customized time range.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FcM2nyIuYhkxbCdbaToca%2FRecurve_data_quality_health_matrix.png?alt=media&amp;token=3a9961c4-912a-4425-9951-0591adc3bf59" alt=""><figcaption></figcaption></figure>

You can use the search bar to search for certain assets by names, and use the filter functions to filter out the asset by different properties.

## Asset details

To view detailed health status of an asset, click on the name of the asset from the matrix.

By default, this opens the **Data quality** tab.

### Data quality

This tab shows all test cases configured to the asset, with test category and target column. Expanding a test case shows all the executions of the test, with the configured severity level and test results.

This section provides a convenient way to view, edit, and add new test cases to an asset.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FBsLVf5XVc1G8o5U1rdYn%2FRecurve_data_quality_data_quality_tab.png?alt=media&amp;token=ff90856a-ebee-47a6-a44a-34305caa3678" alt=""><figcaption></figcaption></figure>

### Build history

Switching to the **Build history** tab shows you all the tasks that involve the asset.  Tasks shown here include both those initiated manually and those triggered by scheduled pipeline jobs. This provides users with a comprehensive timeline of the asset’s activity and performance.

Each record provides details about the task run, such as build time, execution duration, and overall health status of the asset.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FAVA9gvzoFmeuUlJuuCmv%2FRecurve_data_quality_build_history.png?alt=media&amp;token=e07e5858-2811-4a41-b7c0-258788cceb1e" alt=""><figcaption></figcaption></figure>

You can further inspect a task by clicking on it.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FomYgjbxwx3OVkh2xyxGt%2FRecuve_data_quality_task_detail.png?alt=media&amp;token=d46a23a5-4bf2-45eb-b92d-745e94207c1e" alt=""><figcaption></figcaption></figure>


# Data protection

The **Data Protection** feature utilizes **Data Encryption** to ensure the confidentiality and integrity of data.

This process involves transforming readable data (plaintext) into an unreadable format (ciphertext) using advanced cryptographic algorithms and a secure encryption key. Only authorized parties with the corresponding decryption key can revert the data to its original form.

By encrypting data during storage, transmission, and processing, this feature protects sensitive information from unauthorized access, theft, and tampering.

Some of the use cases include:

* **Analytics** **querying**: unless authorized, a user is not able to query privacy-sensitive data, even though they have all access to the database
* **Data querying**: an authorized user can run a query to get the data, which reveals the privacy-sensitive data
* **Access control**: the data owner can conveniently grant/revoke access to privacy-sensitive data

In the current version, ReOrc supports data encryption through:

* **Key management**: Organization owners or admins can create encryption keys using symmetric cryptographic algorithms, AES-128 or AES-256.
* **Column-level encryption**: Users can apply their database or data warehouse's built-in encryption and decryption functions with the created keys.

## Key management

{% hint style="warning" %}
Only organization owners or admins can create and edit encryption keys.
{% endhint %}

To create an encryption key:

1. Log in to your ReOrc organization.
2. Navigate to **Data Governance** > **Data Protection** in the sidebar.
3. Click **Create key**.
4. Provide the following details:

   * **Key name**: This name must be unique and will be used in transformation scripts for encryption and decryption.
   * **Description**: Optional, but recommended.
   * **Encryption algorithm**: Choose between AES-128 and AES-256.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FdkohNYSWnrniDmKcoB9K%2FRecurve_key_management.png?alt=media&amp;token=5076a7bc-c200-4789-abce-5f25b24bec60" alt="" width="563"><figcaption></figcaption></figure>
5. Click **Create**.

<details>

<summary>AES-128 or AES-256</summary>

When choosing between AES-128 and AES-256 for database encryption, you should consider the tradeoff between performance and security:

* **AES-128**: Faster encryption and decryption (\~40% faster than AES-256), suitable for general use cases.
* **AES-256**: Provides stronger security and a larger key space, ideal for highly sensitive data, such as financial records or government information.

</details>

## Encrypt and decrypt data

{% hint style="info" %}
ReOrc currently supports data encryption in advanced pipeline's operators only.
{% endhint %}

### **In SQL**&#x20;

You can use the `{{ secret('key_name') }}` macro to reference your encryption key in SQL snippets. Use your database's encryption functions in a [**SQL opearator** ](/pipeline/advanced-pipeline#sql-operator)as follows:

```sql
-- Encrypt raw data using the secret key 'key_name'
SELECT AES_ENCRYPT(raw_column, {{ secret('key_name') }}) AS encrypted_data FROM my_table;

-- Decrypt data using the same key
SELECT AES_DECRYPT(encrypted_column, {{ secret('key_name') }}) AS decrypted_data FROM my_table;
```

### In Python

You can use the `aes_encrypt` and `aes_decrypt` utility functions. For example, in a [**Transfer operator**](/pipeline/advanced-pipeline#python-operator), we can encrypt column data before loading it into destination:

```python
class MyTransformer(Transformer):
    def transform_impl(self, row: dict, *args, **kwargs):
        row['phone_number_encrypted'] = aes_encrypt(row['phone_number'], 'key_name')
        return row

transformer = MyTransformer()
```


# Console

The ReOrc Console offers a convenient way to run and verify your assets in the development environment. Instead of navigating between modules, you can access the console from the bottom toolbar to execute models and pipelines directly, viewing results instantly.

Similar to pipeline execution, a console run performs these actions:

* Allow you to select multiple assets.
* Execute each asset as a task in the order determined by dependency, and along with associated data tests (for models).
* Provide task details view for troubleshooting, including the compiled query and run logs.

But unlike pipeline executions, console runs are instant and focused on verification. This makes it easy to iterate on your assets and ensure they work correctly before shipping changes to production.

The console currently supports two asset types: models and pipelines.

## Run assets in console

To run assets in the console, follow these steps:

1. Open your project and go to **Design**.
2. At the bottom of the screen, click on **Console**.

   This opens the console panel.
3. Click on the **Choose assets or pipeline** prompt input.
4. In the opened pop-up, select the asset type and the target assets.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FzWPezSz8OwD9pVCVcmF9%2FRecurve_console_select_model_dialog.png?alt=media&amp;token=14be722d-dbdb-4b6c-9c7f-3eaa26b46c18" alt=""><figcaption></figcaption></figure>
5. In **Variable settings**, you can view the list of variables associated with the models.&#x20;

   On each variable, you can decide to lock the current value; this applies to dynamic variables, such as current datetime. You can also provide a custom value.
6. Click **Save**.&#x20;
7. To run the assets, click **Run**.&#x20;

Each asset is then executed as a task and displayed in the task list.&#x20;

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FQAVEBHZqfoT2qmIq3ZFN%2FRecurve_console_task_list.png?alt=media&amp;token=7bd5cfdc-e96c-4afe-8e06-f391f42e96af" alt=""><figcaption></figcaption></figure>

## Inspect task details

To view the details of a task, click on the task from the list. This opens the task details view where you can inspect the compiled query, the logs of materialization process, and the test results.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FgmCGw5Fs8loOoo1ILgMR%2FRecurve_console_task_details.png?alt=media&amp;token=27105c5a-c175-466f-9245-5c14be9c0114" alt=""><figcaption></figcaption></figure>


# Metadata

Metadata is essentially "data about data". In ReOrc, metadata include properties and description of a particular asset in your project, such as source, model, or pipeline. Metadata can help your team effectively communicate asset information, set up the behavior, and manage its lifecycle.

## Metadata types

ReOrc supports the following metadata. Some metadata only apply to specific asset types.

<table data-full-width="false"><thead><tr><th width="166">Metadata</th><th width="297.3333333333333">Value</th><th>Usage</th></tr></thead><tbody><tr><td><strong>Status</strong></td><td><ul><li>Live: The asset is considered accurate and ready for use.</li><li>In progress: Default status - the asset is being developed and not yet finalized.</li><li>Archive: The asset is archived and no longer recommended for use.</li></ul></td><td>Status indicates the current status of the asset, helping the team and system identify its stage in the lifecycle.</td></tr><tr><td><strong>Owner</strong></td><td>List of the owners</td><td>Owner specifies the owners of the asset, who are responsible for its maintenance, updates, and management.</td></tr><tr><td><strong>Materialization</strong></td><td><ul><li>View</li><li>Table</li><li>Incremental</li><li>Ephemeral</li></ul></td><td>Materialization controls how the asset is materialized. See: <a data-mention href="/data-modeling/materialization">Materialization</a>.</td></tr><tr><td><strong>Access</strong></td><td><ul><li>Public: Any models can reference the asset.</li><li>Protected: Only models from the same project can reference the asset.</li><li>Private: No models, including those in the same project, can reference this asset.</li></ul></td><td>Access allows you to manage access permissions of the asset, controlling which models can reference it.</td></tr><tr><td><strong>Tags</strong></td><td>User-defined text</td><td>Members can create descriptive tags to help organize, find, and filter a model. For example: <code>finance</code> or <code>daily-report</code>.</td></tr><tr><td><strong>Description</strong></td><td>Description of the asset</td><td>Members can create description of a model to communicate the design, purpose, and usage.</td></tr></tbody></table>

## View and edit metadata

To view and edit metadata of an asset, open the asset in editor and click on the ![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FG92nawkXZhXwxMEsVCya%2FRecurve_info_button.png?alt=media\&token=bf4cf02e-a67b-4898-8975-211410cbfff4) icon. The **Metadata** panel appears on the right side where you can edit the available properties.&#x20;

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Fpvkv6yM1rENR79nqomVd%2FRecurve_metadata_section.png?alt=media&amp;token=b33f3be7-8444-41ad-873b-513f9f282826" alt=""><figcaption></figcaption></figure>


# Version history

Version history provides a systematic approach to keeping track of changes made to an asset in ReOrc. You can create and publish an asset under a specific version, allowing your team to review the progression of changes and roll back to previous versions if necessary.

## Publish a version

By default, when you first create an asset, such as a model or a pipeline, that asset is in the `draft` state. After you've made some changes to the asset, you can publish it to indicate that the asset is ready for use in your data workflow. This means creating a version of the asset and recording it in version history.

To publish an asset, follow these steps:

1. In the editor, click on the **Publish** button.&#x20;

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F0DWeCymHnYpgVLAegh3Y%2FRecurve_asset_publish_button.png?alt=media&amp;token=b8205ac2-4445-4685-afae-146b78bcad77" alt="" width="563"><figcaption></figcaption></figure>

   This opens the asset publishing modal.
2. In **Version Information**, provide the version number and the update message to describe the changes you made.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FSOiKbBFZMJloCzl7Jxlx%2FRecurve_publish_model_modal.png?alt=media&amp;token=14797360-02cb-4176-ae55-fe1effd9d760" alt="" width="563"><figcaption></figcaption></figure>
3. If you're making changes to an already published asset, you can switch to the **Compare changes** tab to see the diff view.&#x20;

   Diff view compares the current modifications to the latest version of the asset.
4. Click **Publish**.

## View version history

You can view all the versions of an asset in version history.

Follow these steps:

1. Open the asset in the editor.
2. Click on the **Version history** button.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FFoRCOwZJ4lU3jeujHXda%2FRecurve_version_history_button.png?alt=media&amp;token=9ecc039b-46d0-4b55-8e9d-26744e12ac37" alt="" width="563"><figcaption></figcaption></figure>
3. In the opened **Version history** panel, you can see the list of versions of the asset.

   <figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FEoWE3wtOECfTy8NTKc95%2FRecurve_version_history_panel.png?alt=media&amp;token=69d3f3e0-2375-4cd8-b4cf-20780ba2c031" alt="" width="563"><figcaption></figcaption></figure>
4. Select a version to view the detailed changes.


# Packages and dependencies

As the core functionalities in ReOrc's data modeling leverages dbt, external dbt packages and project dependencies are also supported.

<details>

<summary>What are dbt packages?</summary>

**Definition**

dbt package refers to the encapsulation of dbt resources into a folder structure. Like code libraries in software engineering, dbt packages are reusable collections of resources (sources, models, and macros) that can be distributed and reused across multiple projects. These packages are often created by other teams or the community and provide useful functionalities, best practices, or industry-specific logic.

**Benefits**

* **Code Reusability:** Packages let you reuse tested models, macros, and transformations across multiple projects, saving development time.
* **Standardization:** Apply consistent logic and best practices across teams by using shared packages.
* **Collaboration:** Teams can share their work as packages, enabling other teams to leverage existing solutions without reinventing the wheel.
* **Community Resources:** Open-source packages provide industry-standard tools and utilities maintained by the community, reducing the need for custom development.

</details>

<details>

<summary>What are dbt project dependencies?</summary>

**Definition**

Leveraging the flexibility and modularity of packages, each dbt project can also be treated as a package. This means one project can rely on models, resources, or data from another. This setup allows multiple teams to collaborate and share data models while maintaining separate projects.&#x20;

Dependencies between projects can be dynamically resolved, meaning you can reference models from another project without having to include their source code directly in your project.

**Benefits**

* **Shared Logic:** Teams can reuse models across projects, promoting consistency and reducing redundancy.
* **Dynamic Resolution:** Dependencies are resolved dynamically, meaning you don’t need to pull in the source code from other projects, making the setup cleaner and more manageable.
* **Clear Boundaries:** Each team maintains ownership over their project, while still allowing other teams to benefit from their work.

</details>

ReOrc simplifies the process of package import and dependency management through the **Packages** and **Dependencies** menus.&#x20;

## Manage packages

To access the **Packages** menu, from the top navigation bar of your project, click on **Packages**.

The menu displays a curated list of packages that you can install to your project.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FsXSDJgtOyuEyK0xqq368%2FRecurve_packages_menu.png?alt=media&amp;token=8e40f203-2b03-4bb9-ac42-61fa0696e66a" alt=""><figcaption></figcaption></figure>

### Install a package

You can search for a package by name or filter by provider, and toggle on the **Install** option. The package's resources will then be available to use in your project.

You can then use the package's resources, such as macros in your models: [Macros](/data-modeling/jinja-templating/macros#use-macros-from-a-package).

To view the full list of packages and their descriptions, refer to the Package Hub - a registry for dbt packages, maintained by the dbt Community: [Package Hub](https://hub.getdbt.com/).

### Uninstall a package

To uninstall a package, simply navigate to the package row in the **Packages** menu and toggle off the **Install** option.

Note that after uninstalling, all the references to the package's resources will likely fail.

## Manage dependencies

To access the **Dependencies** menu, from the top navigation bar of your project, click on **Dependencies**.

The **Dependencies** menu lists out all projects in your organization with relevant information, including the analytics database in use and the project owner.&#x20;

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FBl69EqOZAHRg0VzSqVIU%2FRecurve_dependencies_menu.png?alt=media&amp;token=9bc5a4a9-6e0d-49fd-ae5c-799cffd7d446" alt=""><figcaption></figcaption></figure>

### Connect a dependent project

To connect another project in your organization as a dependent project, locate the project in the list and toggle on the **Connect** option.&#x20;

All resources with the `Public` access from the dependent project, such as sources, models, macros, will be accessible from the current project. See: [Metadata](/asset-management/metadata#metadata-types).

### Remove a dependent project

To remove a dependent project, locate the project in **Dependencies** and toggle off the **Connect** option.

Note that all resources in the current project that depend on the removed project will likely fail.


# Overview

A introduction to the Data Service module of ReOrc.

## What is Data Service?

The **Data Service** module simplifies data access for non-technical users by providing a user-friendly interface to interact with SQL-based data views. It allows business teams, external partners, or other stakeholders to explore, filter, and download data without needing to write or understand SQL queries.With Data Service, technical users (e.g., data engineers or analysts) can create and share pre-defined SQL queries, while non-technical users can easily access and interact with the resulting data through a visual interface. This eliminates the need for manual data extraction or complex query writing, making data more accessible and actionable for everyone.

## Key benefits

* **Save as a Service**: Users can save queries as services, enabling others to preview, download, or access the data through an API.
* **Ease of Use for Non-Tech Users**: Non-technical users can easily preview data and perform further analysis without SQL knowledge.
* **Data Accessibility**: External users can download data in Excel or extract it via API for seamless integration with their systems.

## Components

* **Create & edit Data Service**: Write, save, and manage SQL queries with a built-in editor and field configuration options.
* **Data preview & download**: Preview, filter, sort, and export data to Excel/CSV for easy analysis and sharing.
* **Data sharing API**: Share Data Services and access data via API keys.
* **Access control**: Manage permissions and share Data Services with specific users or teams.


# Create & edit Data Service

{% hint style="info" %}
Only users with Manage/Edit permission can create & edit the Data Service.
{% endhint %}

## Create a Data Service

To create a Data Service, follow these steps:

1. In your ReOrc project, go to **Data Service**.
2. Click on the **+** icon and select **Create data service.**
3. Provide the name for your Data Service.
4. Click **Create.**

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FEfS2swDmygOC00MM5dT7%2FScreenshot%202025-02-26%20at%2016.43.43.png?alt=media&amp;token=cd283121-800b-40df-a815-65099fcf7996" alt=""><figcaption></figcaption></figure>

## Define SQL query

1. Click **Edit query** to define/ edit SQL query of the Data Service.
2. In the query editor, define connection for your Data Service.
3. Input your SQL query.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Fz1NVw6zFgqeEhnnp12nr%2FScreenshot%202025-02-26%20at%2016.52.58.png?alt=media&amp;token=aaeb96c4-92fc-4bf4-a891-410860d6b30b" alt=""><figcaption></figcaption></figure>

{% hint style="info" %}
When SQL contains field aliases, please add "AS" explicitly and the corresponding identifier for the different databases, and avoid `SELECT *`syntax
{% endhint %}

For example:

```sql
SELECT
    o.id AS order_id,
    c.name AS customer_name,
    o.order_total
FROM
    database_name.table_name o
JOIN
    database_name.table_name c ON o.customer = c.id
WHERE
    o.order_status = 'completed';
```

4. Click **Update > Save** to confirm the changes.
5. View the query output in the **Data Preview** tab.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F9K5bfQITuxCLQlU8e0lM%2FScreenshot%202025-02-26%20at%2017.08.04.png?alt=media&amp;token=e28b24f1-8e4b-4abc-b616-785c642e727f" alt=""><figcaption></figcaption></figure>

## Organize Data Services

To create a new folder, click on the action button of an existing folder and select **Add sub-folder**:

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Fusi3kM993CPGMxlH6Nvl%2FScreenshot%202025-02-26%20at%2017.17.27%20(1).png?alt=media&amp;token=a390f76c-da61-45bf-b633-2533d2fd2c81" alt=""><figcaption></figcaption></figure>

To move a Data Service into the new folder, click on the action button of the Data Service and select **Move to**. Then select the target folder from the list.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FAWNLgbMZEfruvMJpwoor%2FScreenshot%202025-02-26%20at%2017.18.55.png?alt=media&amp;token=43351894-9b30-46bc-92b6-c3df7a9d1d0e" alt=""><figcaption></figcaption></figure>


# Data preview & download

## Field properties configuration

You, as an editor, can configure the field's properties in menu action when click on column header:

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2Fbyl0SGVADm47MDCOBWmg%2FScreenshot%202025-02-26%20at%2017.32.54.png?alt=media&amp;token=9641e6ee-c777-468f-b623-7c6078a1065b" alt=""><figcaption></figcaption></figure>

* **Edit description:** Add/ edit description to provide context or notes to the field (optional).

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FAXR3W91AtSTwgN7swCJ2%2FScreenshot%202025-02-27%20at%2011.09.09.png?alt=media&amp;token=70486a67-fda2-4284-a0ec-b286855060e1" alt=""><figcaption></figcaption></figure>

Description can be viewed by hovering tip icon next to field name.

* **Edit field alias:** Add/ edit alias to the field (optional). If no alias is added, header (field name) will be shown as-is (extracted from query).

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FrclNcG2xdNV5PjFnqTLj%2FScreenshot%202025-02-27%20at%2011.06.36.png?alt=media&amp;token=83ec8db7-ca5b-43a0-9e18-961dd730b595" alt=""><figcaption></figcaption></figure>

Click the **X** icon on the right side of the text to revert to the original field name.

## Filters & sorting

You can filter and sort data in the Data Service preview to conduct analysis, focus on specific details, or refine your data view.

### Set filter conditions

1. Click **Filter** at the top of the preview table.
2. You can add multiple filter conditions.
   * Select a field (e.g., *Customer, OrderID, Revenue, Date*).
   * Choose an operator, available options based on data type of the field (see table below).
   * Enter the filter value.

<table><thead><tr><th width="167">Operator</th><th width="126" align="center">STRING</th><th width="118" align="center">INT</th><th width="113" align="center">FLOAT</th><th width="118" align="center">DATETIME</th><th align="center">BOOLEAN</th></tr></thead><tbody><tr><td><ul><li>Equal</li><li>Not equal</li></ul></td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td><td align="center">✓</td></tr><tr><td><ul><li>Greater than</li><li>Greater than or equal to</li><li>Less than</li><li>Less than or equal to</li></ul></td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td><td align="center"></td></tr><tr><td><ul><li>Contains</li><li>Not contains</li></ul></td><td align="center">✓</td><td align="center"></td><td align="center"></td><td align="center"></td><td align="center"></td></tr><tr><td><ul><li>Time range</li></ul></td><td align="center">✓</td><td align="center"></td><td align="center"></td><td align="center">✓</td><td align="center"></td></tr></tbody></table>

Click the **X** icon on the right side of the filter condition to delete it.

3. You can choose whether **Any** or **All** needs to be met.
4. Click **Confirm** to apply filter conditions.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FetxdrDCgb7xPOgulCeax%2F1.0%20Open%20filter%20popover.png?alt=media&amp;token=f6c708b0-e933-425e-abec-af27d0d157c8" alt=""><figcaption></figcaption></figure>

### Set sort conditions

1. Click **Filter** at the top of the preview table.
2. You can add multiple sort conditions.
   1. Select a field to sort.
   2. Choose the sort method (**Ascending** or **Descending**).

Click the **X** icon on the right side of the sort condition to delete it.

3. Click **Confirm** to apply sort conditions.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F9WK9cra9wNIPihkV0Vbh%2F2.0%20Open%20sort%20popover.png?alt=media&amp;token=c56a8d48-57ff-43b5-9434-34368e354ce7" alt=""><figcaption></figcaption></figure>

## Refresh to get latest data

You can click **Refresh** at the top right corner of the data preview table to extract latest data.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FsOjfU5Ioz6MhVsMGtXcJ%2FScreenshot%202025-02-27%20at%2010.55.28.png?alt=media&amp;token=91c0b31f-a3f0-4e7a-86cf-ffb01475eb6b" alt=""><figcaption></figcaption></figure>

{% hint style="info" %}
Clicking the **Refresh** button triggers to get the **latest** data based on current sort/ filter conditions that being applied, but takes no effect on reset or changing those configurations.
{% endhint %}

## Download data

1. Click the **Download** button at the top of the data preview table.
2. You can rename the download file (optional). By default, file name is the Data Service's name.
3. Select file format (**Excel** or **CSV**).

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FRfpMndnrww3OP8FcYdz9%2FScreenshot%202025-02-27%20at%2011.31.08.png?alt=media&amp;token=8ad02142-bf62-446d-a97e-dbb8a6031b48" alt=""><figcaption></figcaption></figure>

4. Click **Download.**
5. Check download task in your browser.

**Note**:

* Field alias, filter and sort conditions will take effect on your download file.
* Total row number of your download file should not exceed 500,000 rows.


# Data sharing API

The Data Service API is shared for all services, the user can refer to API documentation to know the usage (request & response format).

## Get your personal API key

You can generate, manage, and perform actions on your API key to use the Data Service API.

1. Click **How to call API?** in the utility bar
2. The API Key is hidden by default. Click on **Reveal the key** to see its value, and you can quickly click to **Copy.**
3. Follow the API documentation below for API endpoints, request parameters and usage guidelines.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FdxYyhW39bKZWwnHT0acj%2FScreenshot%202025-02-27%20at%2012.44.28.png?alt=media&amp;token=e7147bcb-c037-48a6-ba44-74770782a84a" alt=""><figcaption></figcaption></figure>

You can click **Rotate** to generate a new API key (replace the existing one).

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FUmRfymbFNljAkC9Q86HY%2FScreenshot%202025-02-27%20at%2016.06.47.png?alt=media&amp;token=9d8acd65-6830-45d0-aa31-105f2db9c4ce" alt=""><figcaption></figcaption></figure>

{% hint style="info" %}
The current key will immediately be disabled once rotated and requests made using the key will be rejected.
{% endhint %}

### API Documentation

### Prerequisite

Obtain your [personal API key](#get-your-personal-api-key) from the Data Service detail page.

### API Request

#### **Request Header**

| Request header | Value                       |
| -------------- | --------------------------- |
| Authorization  | Bearer `{{ your_API_key }}` |

#### **Request Body**

<table><thead><tr><th width="128">Parameter</th><th width="92">Type</th><th width="539">Description</th></tr></thead><tbody><tr><td>filters</td><td>array</td><td><p>Filter conditions list. Each filter contains:</p><ul><li><code>field</code>: The field name to filter on.</li><li><code>operator</code>: The comparison operator. </li></ul><p>Supported operators: </p><p><code>=</code>, <code>!=</code>, <code>></code>, <code>&#x3C;</code>, <code>&#x3C;=</code>, <code>~</code> (inclusive), <code>!~</code> (exclusive), </p><p><code>time_between</code>, <code>time_relative</code> (for special time ranges including <code>today</code>, <code>yesterday</code>, <code>this_week</code>, <code>last_week</code>, <code>this_month</code>, <code>this_year</code>, <code>last_year</code>).</p><ul><li><code>value</code>: The filter value. </li></ul><p>If using <code>time_between</code>, the value must be an array in the format <code>[start_time, end_time]</code>.</p></td></tr><tr><td>sorts</td><td>array</td><td><p>Sort conditions list. Each sort condition contains:</p><ul><li><code>field</code>: The field name to sort by.</li><li><code>order</code>: The sorting order, either <code>asc</code> (ascending) or <code>desc</code> (descending).</li></ul></td></tr><tr><td>page</td><td>int</td><td>The page number for pagination.</td></tr><tr><td>page_size</td><td>int</td><td><p>The number of records returned per page. </p><p>Allowed values: <code>[100, 10000]</code>. Default: <code>100</code>.</p></td></tr></tbody></table>

#### **Request Example**

{% code overflow="wrap" %}

```sh
curl --location --request POST 'https://api.reorc.cloud/api/data-service/open/services/{{ data_service_id }}/preview' \
--header 'Accept-Language: en-US,en;q=0.9,zh;q=0.8,zh-CN;q=0.7' \
--header 'Cache-Control: no-cache' \
--header 'Connection: keep-alive' \
--header 'DNT: 1' \
--header 'Origin: https://demo.reorc.cloud' \
--header 'Pragma: no-cache' \
--header 'Referer: https://demo.reorc.cloud/' \
--header 'Sec-Fetch-Dest: empty' \
--header 'Sec-Fetch-Mode: cors' \
--header 'Sec-Fetch-Site: same-site' \
--header 'User-Agent: Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/133.0.0.0 Safari/537.36' \
--header 'accept: application/json' \
--header 'sec-ch-ua: "Chromium";v="133", "Not(A:Brand";v="99"' \
--header 'sec-ch-ua-mobile: ?0' \
--header 'sec-ch-ua-platform: "macOS"' \
--header 'content-type: application/json' \
--header 'Authorization: Bearer {{ your_api_key }}' \
--header 'Host: api.reorc.cloud' \
--data-raw '{
    "filters": [
        {
            "field": "PaymentMethod",
            "operator": "=",
            "value": "Cash"
        }
    ],
    "filter_logic": "all",
    "sorts": [],
    "timezone": "Asia/Shanghai"
}'
```

{% endcode %}

{% hint style="info" %}
Please replace the following parameters with actual values:

* `{{ data_service_id }}`: the actual ID of the data service.
* `{{ your_api_key }}`: your personal API key.
  {% endhint %}

#### **Response Example**

Successful Response Example

{% code fullWidth="false" %}

```json
{
    "code": "0",
    "msg": "success",
    "data": {
        "total": 304,
        "items": [
            {
                "o_orderkey": {
                    "type": "bigint",
                    "name": "o_orderkey",
                    "normalized_type": "integer",
                    "value": "5997922"
                },
                "o_orderdate": {
                    "type": "date",
                    "name": "o_orderdate",
                    "normalized_type": "date",
                    "value": "1992-12-04"
                },
                "o_custkey": {
                    "type": "int",
                    "name": "o_custkey",
                    "normalized_type": "integer",
                    "value": "88970"
                },
                "o_orderstatus": {
                    "type": "varchar",
                    "name": "o_orderstatus",
                    "normalized_type": "string",
                    "value": "F"
                },
                "o_totalprice": {
                    "type": "decimal",
                    "name": "o_totalprice",
                    "normalized_type": "float",
                    "value": "91422.19"
                },
                "o_orderpriority": {
                    "type": "varchar",
                    "name": "o_orderpriority",
                    "normalized_type": "string",
                    "value": "4-NOT SPECIFIED"
                },
                "o_clerk": {
                    "type": "varchar",
                    "name": "o_clerk",
                    "normalized_type": "string",
                    "value": "Clerk#000000108"
                },
                "o_shippriority": {
                    "type": "int",
                    "name": "o_shippriority",
                    "normalized_type": "integer",
                    "value": "0"
                },
                "o_comment": {
                    "type": "varchar",
                    "name": "o_comment",
                    "normalized_type": "string",
                    "value": "oze blithely across the slyly bold packages. dolphin"
                }
            },
            {
                "o_orderkey": {
                    "type": "bigint",
                    "name": "o_orderkey",
                    "normalized_type": "integer",
                    "value": "5997921"
                },
                "o_orderdate": {
                    "type": "date",
                    "name": "o_orderdate",
                    "normalized_type": "date",
                    "value": "1997-03-16"
                },
                "o_custkey": {
                    "type": "int",
                    "name": "o_custkey",
                    "normalized_type": "integer",
                    "value": "117583"
                },
                "o_orderstatus": {
                    "type": "varchar",
                    "name": "o_orderstatus",
                    "normalized_type": "string",
                    "value": "O"
                },
                "o_totalprice": {
                    "type": "decimal",
                    "name": "o_totalprice",
                    "normalized_type": "float",
                    "value": "68401.33"
                },
                "o_orderpriority": {
                    "type": "varchar",
                    "name": "o_orderpriority",
                    "normalized_type": "string",
                    "value": "2-HIGH"
                },
                "o_clerk": {
                    "type": "varchar",
                    "name": "o_clerk",
                    "normalized_type": "string",
                    "value": "Clerk#000000101"
                },
                "o_shippriority": {
                    "type": "int",
                    "name": "o_shippriority",
                    "normalized_type": "integer",
                    "value": "0"
                },
                "o_comment": {
                    "type": "varchar",
                    "name": "o_comment",
                    "normalized_type": "string",
                    "value": "xcuses nag slyly. idle dolphins cajole ironically-- regular, bold ex"
                }
            },
            {
                "o_orderkey": {
                    "type": "bigint",
                    "name": "o_orderkey",
                    "normalized_type": "integer",
                    "value": "5997920"
                },
                "o_orderdate": {
                    "type": "date",
                    "name": "o_orderdate",
                    "normalized_type": "date",
                    "value": "1992-08-02"
                },
                "o_custkey": {
                    "type": "int",
                    "name": "o_custkey",
                    "normalized_type": "integer",
                    "value": "42044"
                },
                "o_orderstatus": {
                    "type": "varchar",
                    "name": "o_orderstatus",
                    "normalized_type": "string",
                    "value": "F"
                },
                "o_totalprice": {
                    "type": "decimal",
                    "name": "o_totalprice",
                    "normalized_type": "float",
                    "value": "36627.47"
                },
                "o_orderpriority": {
                    "type": "varchar",
                    "name": "o_orderpriority",
                    "normalized_type": "string",
                    "value": "1-URGENT"
                },
                "o_clerk": {
                    "type": "varchar",
                    "name": "o_clerk",
                    "normalized_type": "string",
                    "value": "Clerk#000000205"
                },
                "o_shippriority": {
                    "type": "int",
                    "name": "o_shippriority",
                    "normalized_type": "integer",
                    "value": "0"
                },
                "o_comment": {
                    "type": "varchar",
                    "name": "o_comment",
                    "normalized_type": "string",
                    "value": "al instructions nag carefully until the requests. fluffily re"
                }
            },
            {
                "o_orderkey": {
                    "type": "bigint",
                    "name": "o_orderkey",
                    "normalized_type": "integer",
                    "value": "5997895"
                },
                "o_orderdate": {
                    "type": "date",
                    "name": "o_orderdate",
                    "normalized_type": "date",
                    "value": "1996-01-15"
                },
                "o_custkey": {
                    "type": "int",
                    "name": "o_custkey",
                    "normalized_type": "integer",
                    "value": "91180"
                },
                "o_orderstatus": {
                    "type": "varchar",
                    "name": "o_orderstatus",
                    "normalized_type": "string",
                    "value": "O"
                },
                "o_totalprice": {
                    "type": "decimal",
                    "name": "o_totalprice",
                    "normalized_type": "float",
                    "value": "199978.64"
                },
                "o_orderpriority": {
                    "type": "varchar",
                    "name": "o_orderpriority",
                    "normalized_type": "string",
                    "value": "2-HIGH"
                },
                "o_clerk": {
                    "type": "varchar",
                    "name": "o_clerk",
                    "normalized_type": "string",
                    "value": "Clerk#000000075"
                },
                "o_shippriority": {
                    "type": "int",
                    "name": "o_shippriority",
                    "normalized_type": "integer",
                    "value": "0"
                },
                "o_comment": {
                    "type": "varchar",
                    "name": "o_comment",
                    "normalized_type": "string",
                    "value": "ly among the regular, even depend"
                }
            }
        ],
        "error": null
    }
}
```

{% endcode %}

Failed Response Example

{% code overflow="wrap" %}

```json
{
    "code": "0",
    "msg": "success",
    "data": {
        "total": 0,
        "items": [],
        "error": {
            "code": "A1402",
            "reason": "Preview data failed: (1105, \"errCode = 2, detailMessage = Unknown column 'o_orderke' in '_reorc_limit_subquery' in SORT clause\")",
            "data": null
        }
    }
}
```

{% endcode %}


# Access control

## Manage permission

1. Navigate to the **Data Service** you want to share.
2. Click the **Share** button in the utility bar.
3. View the list of users with access and their roles:
   * **Administrators**: Can manage all assets and users.
   * **Developers**: Can edit data services.
   * **Viewers**: Can view and download data.
   * **Guests**: External users with view-only access to specific assets that they have been granted.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F0QfnOEmw64U9s6k0XLV3%2FScreenshot%202025-02-27%20at%2015.38.03.png?alt=media&amp;token=f27b6e91-12d0-40a2-b4fd-6aeab85f8c49" alt=""><figcaption></figcaption></figure>

**Note**:

* **Project Members** will have their default access to the data service based on their role in the project (e.g., Administrators can manage, Developers can edit, Viewers can view).&#x20;
* These default access levels **cannot be modified** in the data service sharing settings. To change a user’s role, update their role in the [**Project settings**](/settings/project-settings).

## Add users

1. In the **Share** popup, click the search bar.
2. Search for users by name or email.
3. Select a user to grant **"Can View"** access.
4. The user will be added to the parental project as a **Guest**.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F9VRUdvKdphk2Hq6S6p31%2FScreenshot%202025-02-27%20at%2015.52.23.png?alt=media&amp;token=8dcb9f7c-b70b-4733-adc9-822dd990e319" alt=""><figcaption></figcaption></figure>

{% hint style="info" %}
If you can not find users, please check to ensure they are members of the current organization in the [Organization settings](/settings/organization-settings).
{% endhint %}

### Remove users

1. In the **Share** popup, locate the user you want to remove.
2. Click **Remove** next to their name to revoke access.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FNsU47zTdpWORFkhouDPd%2FScreenshot%202025-02-27%20at%2015.59.25.png?alt=media&amp;token=e9d132dd-0526-4713-8f56-c328bd9d40a1" alt=""><figcaption></figcaption></figure>


# Rein AI Copilot

Rein (ReOrc Intelligence) is an AI-powered copilot designed specifically for data transformations. It assists you in writing, fixing, and optimizing data transformation code. The copilot integrates directly into the platform's code editor, providing you with real-time assistance.

In ReOrc model editor, you can invoke Rein by simply highlighting a snippet and let it help you reign over complex data workflows.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F4WSVLM9B39iHvHFadxtd%2FRecurve_rein_code_highlighting.png?alt=media&amp;token=73cf214b-f6ff-49dd-8424-74951d08d66f" alt="" width="563"><figcaption></figcaption></figure>

We recommend highlighting the entire transformation to provide Rein with better context for code fixing and optimization. For each suggestion, Rein displays a diff view comparing the current version and the improved version. You can then accept or regenerate suggestions that best fit your use case.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FBMnpTcKNwhcymH0oiT7A%2FRecurve_rein_suggestions.png?alt=media&amp;token=f735d98a-043d-4944-bcf7-b2e39060e6e4" alt=""><figcaption></figcaption></figure>

## Code fixing

Rein can automatically identify and fix issues in transformation code. This feature helps you by:

* Detecting syntax errors and providing corrections
* Suggesting fixes for common query anti-patterns
* Ensuring proper column references and table dependencies

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FHVR7QQZYBRVbiR4toJna%2FRecurve_rein_fix_code.png?alt=media&amp;token=a017aa06-b895-4579-90f0-dcb9916f181d" alt=""><figcaption></figcaption></figure>

## Code optimization

The optimization feature helps improve the performance and efficiency of transformation code:

* Analyzes query patterns and suggests performance improvements
* Recommends better join strategies
* Identifies opportunities for query simplification
* Optimizes complex operations for better performance

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FaqUHeyKhmOL9pV8gGGoq%2FRecurve_rein_optimize_code.png?alt=media&amp;token=b5310d39-a714-423b-bf58-52aef5ecf194" alt=""><figcaption></figcaption></figure>


# Organization settings

Organization settings allow owners and admins to make changes that apply to all the projects and members of the organization.

To access **Organization settings**, from the left sidebar of ReOrc click on ![](https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FOcNztUhT5hu5wNZIux0y%2FRecurve_organization_icon.jpg?alt=media\&token=c4256b2b-676c-4e49-b5e8-45b06cdabf43) and select a setting section.&#x20;

Below are the available settings of an organization.

## Organization overview

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FOlTOandKH1O2H3ytQKEb%2FRecurve_organization_overview.png?alt=media&amp;token=9938294d-699f-4efc-b7b1-a257143b7d7a" alt=""><figcaption></figcaption></figure>

Here you can edit the **Organization name** or **Delete organization**.

## User management

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FoNJhvfFKHU4dfg7Z4ZZh%2FRecurve_org_user_management.png?alt=media&amp;token=da19fb04-b88c-4da2-a92a-ce728f980cbb" alt=""><figcaption></figcaption></figure>

**User management** allows you to:

* Organize members into departments that reflect your organization structure.
* Invite members by email.
* Change member roles. (Coming soon)
* Deactivate / remove members.

For more details about roles and permissions, see: [Roles and permissions](/settings/roles-and-permissions).

## Environment & workers

Set up environments and workers. For more details, see: [Set up organization](/set-up-and-deployment/set-up-organization).


# Project settings

Project settings allow a project admin to make changes that apply to all members and assets in the project.

To access project settings, open the project and switch to the **Settings** tab.

Below are the available configurations.

## Basic information

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FkWYwJ36VwsH9sfjg1HS0%2FRecurve_project_settings_basic_information.png?alt=media&amp;token=38a1f01e-1418-462b-b6fe-527ed887aa87" alt=""><figcaption></figcaption></figure>

In **Basic information**, you can:

* Edit the project name and icon.
* Set the project status. This helps communicate the project status when members view the project from the project list.
* Edit the project description.

## Data connections

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2F3NGO5v4PeHiKMsy0BbPO%2FRecurve_project_settings_data_connection.png?alt=media&amp;token=545ba464-ef36-4e3a-a9cc-9e4821cc3998" alt=""><figcaption></figcaption></figure>

**Data connections** allows you to configure connections that you can use in the project. For more details, see: [Project connections](/connections/project-connections).

## Project members

As a project admin, you invite members in your organization to the project under different roles and permissions. See: [Roles and permissions](/settings/roles-and-permissions).

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FzgWqA7qohElCIEtbg8Eg%2FRecurve_project_settings_project_members.png?alt=media&amp;token=3215e33d-9a6f-4ce1-9f35-af3337489ca8" alt=""><figcaption></figcaption></figure>


# Profile settings

To customize your ReOrc profile, click your avatar in the bottom-left corner. From here, you can:

* Switch the display language (ReOrc currently supports English and Chinese).
* Switch your organization.
* Change your password.
* Sign out.

To access profile settings, click **Profile**. In this section, you can update your display name and password.

<figure><img src="https://786945529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FFTrGKWnjusKCQj11CkuL%2Fuploads%2FAfIvDykozJyYteJHHNap%2FRecurve_profile_page.png?alt=media&amp;token=5284c3e7-3279-403e-943d-3852df9448a3" alt=""><figcaption></figcaption></figure>


# Roles and permissions

Roles and permissions determine a member's access to the functionalities and assets. ReOrc uses a two-tier access model with predefined roles:

* **Organization level**: controls who can manage company-wide resources like team members, billing, and environment setup.
* **Project level**: determines what specific actions members can perform within individual projects, such as viewing data, performing transformation, or managing project resources.

Each member can have different roles across the organization and its projects.

## Organization level

* **Owner:** has access to all dashboards and resources.
* **Admin:** can view and edit all configuration dashboards and resources, including environment setup, projects, and users.
* **Member:** can only view dashboards and have limited access to resources.

<table data-full-width="false"><thead><tr><th align="center">Permissions</th><th align="center">Owner</th><th align="center">Admin</th><th align="center">Member</th></tr></thead><tbody><tr><td align="center">View organization information</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Edit organization information</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">Create, edit, and delete deparments and users</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">View worker list</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Deploy, join, start, stop, remove workers</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">Generate API keys</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">View destinations</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Add, edit, delete destinations</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">View integration list</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Add, edit, remove integrations</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">View project list</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Create project</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Delete project</td><td align="center">✓ (as project owner)</td><td align="center">✓ (as project owner)</td><td align="center"></td></tr></tbody></table>

## Project level

* **Admin:** can view and edit all configuration dashboards and resources of the project.
* **Developer:** can view and edit assets.&#x20;
* **Viewer:** can view assets only.

<table data-full-width="false"><thead><tr><th align="center">Permissions</th><th align="center">Admin</th><th align="center">Developer</th><th align="center">Viewer</th></tr></thead><tbody><tr><td align="center">View library assets (variables, macros, generic tests)</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Edit library assets</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">View packages and depedencies</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Configure packages and depedencies</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">View data design assets (sources, models, pipelines)</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Edit data design assets</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">View lineage</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Preview and build design data assets</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">View metadata</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Edit metadata</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">View Pipeline Health dashboard</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Edit pipeline jobs</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">View Data Quality dashboard</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">View project settings</td><td align="center">✓</td><td align="center">✓</td><td align="center">✓</td></tr><tr><td align="center">Configure project connections</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr><tr><td align="center">Edit project members</td><td align="center">✓</td><td align="center">✓</td><td align="center"></td></tr></tbody></table>


# Doris/SelectDB

## Materialization configurations

### View

* Define the model as "View" in the metadata panel

### Table

**Table Configuration**[**​**](https://docs.getdbt.com/reference/resource-configs/doris-configs#table-configuration)

```sql
{{ config(
    materialized = "table",
    duplicate_key = [ "<column-name>", ... ],
    partition_by = [ "<column-name>", ... ],
    partition_type = "<engine-type>",
    partition_by_init = ["<pertition-init>", ... ]
    distributed_by = [ "<column-name>", ... ],
    buckets = "int",
    properties = {"<key>":"<value>",...}
      ...
    ]
) }}
```

Available configurations:

| Option              | Description                                                                             | Required or not?                     |
| ------------------- | --------------------------------------------------------------------------------------- | ------------------------------------ |
| `materialized`      | How the model will be materialized into Doris. Must be `table` to create a table model. | Required, can be defined in metadata |
| `duplicate_key`     | The key list of Doris table model: 'duplicate'.                                         | Required                             |
| `partition_by`      | The partition key list of Doris.                                                        | Optional                             |
| `partition_type`    | The partition type of Doris.                                                            | Optional (default: `RANGE`)          |
| `partition_by_init` | The partition rule or some real partitions item.                                        | Optional                             |
| `distributed_by`    | The bucket key list of Doris.                                                           | Required                             |
| `buckets`           | The bucket number in one Doris partition.                                               | Required                             |
| `properties`        | The other configuration of Doris.                                                       | Required                             |

### Incremental

An incremental Doris table, item table model must be 'unique' and is configured using the following syntax:

#### **Incremental table configuration**[**​**](https://docs.getdbt.com/reference/resource-configs/doris-configs#incremental-table-configuration)

```sql
{{ config(
    materialized = "incremental",
    unique_key = [ "<column-name>", ... ],
    partition_by = [ "<column-name>", ... ],
    partition_type = "<engine-type>",
    partition_by_init = ["<pertition-init>", ... ]
    distributed_by = [ "<column-name>", ... ],
    buckets = "int",
    properties = {"<key>":"<value>",...}
      ...
    ]
) }}
```

Available configurations:

| Option              | Description                                                                                                                                                                           | Required or not?            |
| ------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------- |
| `materialized`      | How the model will be materialized into Doris. Must be `table` to create a table model.                                                                                               | Required                    |
| `unique_key`        | The key list of Doris table model :'[Doris unique](https://doris.apache.org/docs/data-table/data-model#uniq-model)'.                                                                  | Required                    |
| `partition_by`      | The partition key list of Doris. ([Doris partition](https://doris.apache.org/docs/data-table/data-partition))                                                                         | Optional                    |
| `partition_type`    | The partition type of Doris.                                                                                                                                                          | Optional (default: `RANGE`) |
| `partition_by_init` | The partition rule or some real partitions item.                                                                                                                                      | Optional                    |
| `distributed_by`    | The bucket key list of Doris. ([Doris distribute](https://doris.apache.org/docs/data-table/data-partition#partitioning-and-bucket))                                                   | Required                    |
| `buckets`           | The bucket number in one Doris partition.                                                                                                                                             | Required                    |
| `properties`        | The other configuration of Doris. ([Doris properties](https://doris.apache.org/docs/sql-manual/sql-reference/Data-Definition-Statements/Create/CREATE-TABLE/?&_highlight=properties)) | Required                    |

#### Best practice of incremental model

Here's a sample model using Doris for incrementally update by partition:

```sql
{{ 
  config(
    materialized = "incremental",
    unique_key = ["id"],  -- Specify the unique key for the incremental model
    partition_by = ["date"],  -- Partition by the date column
    partition_type = "RANGE",  -- Specify the partition type (e.g., RANGE, HASH)
    partition_by_init = ["2025-01-01"],  -- Initial partition value
    distributed_by = ["id"],  -- Distribute by the id column
    buckets = 10,  -- Number of buckets for distribution
    properties = {
      "compression": "lz4",  -- Example property for compression
      "replication_factor": "2"  -- Example property for replication factor
    }
  ) 
}}

SELECT
    id AS order_id,
    DATE(ordered_at) AS date,
    order_total,
    ordered_at,
    NOW() AS updated_at
FROM
    {{ source('ecom', 'raw_orders') }}
    
{% if is_incremental() %}
WHERE
    DATE(ordered_at) = '{{ var("dt") }}'  -- Process only current date's data
{% endif %}

```


# StarRocks

Here's a sample configuration for a model using Starrocks with incremental materialization:

```sql
{{ config(
    materialized='incremental',
    incremental_strategy='insert_overwrite',      -- specify the incremental strategy
    unique_key=['order_id', 'date'],             -- composite unique key
    partition_by=['date'],                       -- date-based partitioning
    properties={
        "dynamic_partition.time_unit": "DAY",     -- partition by day
        "dynamic_partition.end": "3",             -- maintain 3 future partitions
        "dynamic_partition.prefix": "p",          -- partition name prefix
        "dynamic_partition.buckets": "4",         -- number of buckets per partition
        "dynamic_partition.create_history_partition": "true",
        "dynamic_partition.history_partition_num": "3",   -- maintain 3 historical partitions
        "replication_num": "3",                   -- number of replicas
        "storage_medium": "SSD"                   -- storage type
    }
) }}

SELECT
    id AS order_id,
    date(ordered_at) as date,
    order_total,
    ordered_at,
    now() as updated_at
FROM
    {{ source('ecom', 'raw_orders') }}
WHERE
    {% if is_incremental() %}
    date(ordered_at) = '{{ var("dt") }}'    -- process only current date's data
    {% endif %}
```


# 欢迎使用 Reorc

## 什么是 Reorc?

Reorc 是一个统一的数据平台，旨在提供无缝的分析体验和高质量的大规模数据处理。它涵盖数据生命周期的各个阶段，帮助数据从业者高效构建和维护强大的数据转化管道。

## 核心模块

作为一体化的数据解决方案，Reorc 包括以下关键模块：

* **数据摄取（Data ingestion）：**&#x52;eorc 提供多种内置连接器，轻松将数据从不同源加载到统一目标。您还可以自定义连接器，调整数据摄取方案。
* **数据建模（Data modeling）：**&#x52;eorc 支持使用 SQL 和 Python 模型进行数据转化（ETL），遵循最佳实践，并提供版本控制和数据血缘追踪功能，确保数据的透明性和一致性。
* **语义层建模（Semantic modeling）：**&#x52;eorc 的语义层可构建统一、易于理解的业务数据指标，如关键指标及其相互关系。用户可以基于语义模型进行查询，辅助决策。
* **数据编排（Data orchestration）：**&#x901A;过一站式构建端到端数据管道，涵盖数据接入、转化和业务分析指标，配备开箱即用的操作符和直观可视化图表。
* **质量控制（Quality control）：**&#x52;eorc 在设计时就注重数据质量控制，对所有资产应用测试和质量检查，确保数据符合预定标准。

Reorc 结合了现代数据架构的创新，帮助数据从业者解决以下关键问题：

* **数据管道复杂**：随着数据量和复杂度的增加，ETL 流程、模型和工具变得日益复杂，缺乏集中管理系统让这些组件的协调变得困难。
* **治理不足**：控制权分散在多个工具和用户间，难以实施一致、安全、合规的数据管理。
* **缺乏数据可观测性**：没有统一的数据流视图，资产管理、血缘追踪、质量监控受限，当出现数据问题时，排查困难。
* **知识孤岛**：团队成员在不同的工具上工作，知识形成孤岛，影响协作与跨部门沟通，数据解决方案低效。


# Philosophy


# 设置与部署

本节提供了有关设置 Reorc 的详细信息和指南。

## 架构概述

Reorc 的服务架构分为两个部分：

* **控制面（Control Plane）：**&#x8FD0;行在 Reorc 云系统中，为用户提供管理项目和管道的 Web 界面。
* **数据面（Data Plane）：**&#x63A5;收控制面的指令并执行实际的数据任务，包括数据摄取、转化、管道任务或将数据交付到其他系统。数据面由多个 Workers 组成，这些 Workers 由控制面进行编排和管理。

<figure><img src="https://content.gitbook.com/content/MNJfiu2Or0lnmkm2x228/blobs/ovoB0IwqCGLGjcj0Dha5/Recurve_high_level_architecture.png" alt="" width="563"><figcaption></figcaption></figure>

这种架构分离提供了灵活的部署方式，数据面的 Workers 可以安装在不同的地点，以满足您组织在性能、可维护性、安全性和合规性方面的需求。

当前版本的 Reorc 支持在用户的基础设施中设置数据面服务。

请按照以下两个指南来设置您的组织并安装 Reorc-agent （数据面中的核心服务）：

1. [设置组织](/cn-reorc-help-center/she-zhi-yu-bu-shu/she-zhi-zu-zhi)
2. [安装 reorc-agent](/cn-reorc-help-center/she-zhi-yu-bu-shu/an-zhuang-reorcagent)


# 设置组织

在 Reorc 中，组织是最高层级的结构，包含多个项目和用户。组织所有者可以管理账单信息、用户权限及其他资源。

本指南将引导您完成组织的设置过程。

{% hint style="info" %}
**前提条件：**&#x60A8;需要先拥有一个 Reorc 账户。如没有账户，请访问 [Reorc](https://cn.reorc.cloud) 创建。
{% endhint %}

## 创建组织

1. 在账户创建完成后的欢迎对话框中，点&#x51FB;**“创建组织 / Create Organization”**&#x6309;钮。
2. 请为您的组织提供名称和域名。该域名将作为组织的唯一标识，同时也是您访问 Reorc 时的地址。

## 设置环境

每个 Reorc 组织通常需要两种环境：开发环境和生产环境。

类似于软件工程中的实践，环境是项目生命周期不同阶段的独立配置。开发环境是数据工程师构建、试验和测试新配置和转换的场所，而生产环境则包含了已全面测试、稳定的数据工作流。

在创建组织时，Reorc会默认设&#x7F6E;**“开发环境/dev”**&#x548C;**“生产环境/prod”**。

访问环境设置，在左侧边栏上，点击图标 ![](https://content.gitbook.com/content/MNJfiu2Or0lnmkm2x228/blobs/I9QZwzZ58v1uHCK1k0eB/Organization_icon.jpg) 并选&#x62E9;**“Environments & Workers”**。&#x20;

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FApgD7749Ey1F0h5O9KSp%2FRecurve_environments_and_workers.png?alt=media&amp;token=95d841a7-0671-493d-b1dd-2c3ecbb0acd4" alt=""><figcaption></figcaption></figure>

设置好环境后，下一步是 [安装 reorc-agent](/cn-reorc-help-center/she-zhi-yu-bu-shu/an-zhuang-reorcagent)。


# 安装 Reorc-agent

Reorc 的数据面（Data Plane）由多个 Worker Hosts 构成，用于运行由控制面（Control Plane）协调的数据任务。

每个 Worker 上都包含一个称为 Reorc-agent 的服务，它与控制面通信，并管理 Worker 上的执行环境。设置 Worker 的规则如下：

* 可设置多个 Workers 以实现横向扩展。
* &#x20;Workers 可以安装在不同的网络位置。
* 专用于某个环境的 Workers 之间必须能够相互通信。因此，建议将相同环境的 Workers 放置在同一局域网络中，以最大程度地稳定连接并降低延迟。

本指南将向您展示如何设置 Reorc Agent。

## 要求

您的 Worker Hosts 需满足以下要求：

**硬件：**

根据实际使用情况，您可以参考以下配置范围，以优化Reorc的性能表现。

<table data-full-width="true"><thead><tr><th width="161"></th><th>Worker 数量</th><th>CPU（核心数 / Worker）</th><th>内存（GB/ Worker）</th><th>磁盘（GB/ Worker）</th></tr></thead><tbody><tr><td>最低配置</td><td>1</td><td>2</td><td>8</td><td>20</td></tr><tr><td>推荐配置</td><td>2+</td><td>4</td><td>16</td><td>100</td></tr></tbody></table>

**软件：**

* 操作系统：Linux（已测试 RHEL 和 Ubuntu ）。
* Python：3.9+，建议使用更新版本，并在可行情况下使用虚拟环境。
* [Docker](https://docs.docker.com/engine/) : 20.10.0+，需安装 Docker Compose。

{% hint style="info" %}
确保运行 Reorc Agent 的用户有权限访问 Docker CLI。可以使用以下命令授予用户权限。在修改用户组后，可能需要注销并重新登录终端会话。

```bash
sudo usermod -aG docker $USER 
```

{% endhint %}

## 设置 Reorc Agent

请按照以下步骤进行操作：

1. 在 Reorc 左侧边栏中，点&#x51FB;**“组织/ Organization”**&#x56FE;标并选&#x62E9;**“环境和 Workers/ Environment & Workers”**。
2. 点&#x51FB;**“部署 Agent/ Deploy Agent”**&#x5E76;按照屏幕上的指示完成 Agent 的部署。

   或者，您也可以按照以下步骤操作。

<details>

<summary>在命令行界面（CLI）中安装 Reorc Agent</summary>

1. 在 Worker Host 上：安装 Agent 包。

```bash
pip install -U reorc-agent
```

您可以通过运行以下命令来验证安装是否成功： `reorc version`

2. 在 Worker Host 上：将 Host 注册到控制面。

```bash
reorc login
```

3. &#x5728;**“环境和 Workers/ Environments & workers”**&#x9875;面中，点&#x51FB;**“部署 Agent/ Deploy Agent”**，复制API密钥，并粘贴到 Host 上。
4. 在 Worker Host 上：启动 Agent，Agent 将持续向控制面发送心跳信号。

```bash
reorc agent start
```

</details>

3. 刷新页面以查看新部署的 Host，状态应显示&#x4E3A;**“在线/ Online”**。
4. 将 Agent 分配到环境。

   当 Agent 运行并显&#x793A;**“在线/ Online”**&#x72B6;态后，点&#x51FB;**“操作/ action”**>**“加入环境/ Join Environment”**，选择要分配的环境。当 Agent 成功加入环境后，您应会看到状态变&#x4E3A;**“活动中/ Active”**。

{% hint style="info" %}
**注意事项**

* `reorc agent start` 命令会在前台启动 Agent ，当终端会话关闭时，Agent 也会终止。对于生产部署，您应让 Agent 在后台运行。更多详细信息，请参考： [在后台运行 Agent](#zai-hou-tai-yun-xing-agent)。
* `dev` 和`prod` 环境必须至少各有一个 Agent 在运行。
  {% endhint %}

## Agent 的操作

当 Agent 启动并运行后，您可以执行一些关键操作。

点击 Agent 的 ***操作/action*** 按钮即可：

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FDG27qY0RS72iC8PGTjft%2FRecurve_agent_clicked_action.png?alt=media&amp;token=766e1810-489b-4d1d-a4a7-fbce9e0abf5f" alt=""><figcaption></figcaption></figure>

可以执行以下操作：

* **重启服务：**&#x91CD;启 Agent 服务，重启后 Agent 仍会加入环境。
* **停止服务：**&#x505C;止 Agent 服务， Agent 将变为非活动状态。
* **离开环境：**&#x5C06; Agent 服务从当前环境中移除。

## 在后台运行 Agent&#x20;

有多种方式可以将 Agent 在后台运行，例如，使用 [systemd](https://systemd.io/) 或 [Supervisor](http://supervisord.org) 等工具。

<details>

<summary>systemd</summary>

1. 创建配置文件

创建 `/etc/systemd/system/reorc-agent.service` 文件，并添加以下内容：

```systemd
[Unit]
Description=ReOrc Agent Service
After=network.target

[Service]
User=<os_user>
Group=<os_user>
ExecStart=/path/to/python/bin/reorc agent start
Restart=on-failure
Environment=PYTHONUNBUFFERED=1
StandardOutput=append:/var/log/reorc/agent.log
StandardError=append:/var/log/reorc/agent.log

[Install]
WantedBy=multi-user.target
```

2. 准备日志文件夹和权限

```bash
sudo mkdir -p /var/log/reorc
sudo chown <os_user>:<os_user> /var/log/reorc
```

3. 启动服务

```bash
sudo systemctl daemon-reload
sudo systemctl start reorc-agent
sudo systemctl enable reorc-agent
```

</details>

<details>

<summary>Supervisor</summary>

**安装 Supervisor**

1. 安装 Supervisor

```bash
# Install on Ubuntu 
sudo apt install supervisor

# Install on CentOS (RHEL)
sudo dnf install supervisor

# or
sudo yum install supervisor
```

2. 创建用户组和用户

```bash
sudo groupadd supervisor
sudo usermod -aG supervisor $USER
```

3. 创建配置文件

安装后，`/etc/supervisord.conf` 中应该已经有一个配置文件。做一些修改以允许`supervisor` 中的用户运行访问 supervisord。

```editorconfig
[unix_http_server]
file=/run/supervisor/supervisor.sock   ; (the path to the socket file)
chmod=770
chown=root:supervisor
```

4. 启用并启动 supervisord

```bash
sudo systemctl enable supervisord
sudo systemctl start supervisord
```

现在，您应该能够运行 `supervisorctl` （supervisord 的控制命令行界面）。

**添加 reorc-agent**

1. 将一个配置文件添加到 `/etc/supervisord.d/reorc-agent.ini`，其内容如下：

```editorconfig
[program:reorc-agent]
command = /path/to/python/bin/reorc agent start
autorestart = true
stopasgroup = true
killasgroup = true
umask = 000
user = <os_user>
redirect_stderr = true
stdout_logfile = /var/log/reorc/agent.log
```

请注意：

* 将 `command` 替换为 `reorc` 二进制文件的绝对路径。通常是 Python 环境（或虚拟环境）的 `bin` 文件夹。
* 替换 `user`。
* 替换日志路径 `stdout_logfile`，用户应该具有对该文件夹的写访问权限。

2. 通过 `supervisorctl` 管理进程

```bash
# Reload config and add/remove as necessary, and will restart affected programs
supervisorctl update

# start, stop, and restart reorc-agent
supervisorctl start reorc-agent
supervisorctl stop reorc-agent
supervisorctl restart reorc-agent
```

</details>

## 升级 Agent&#x20;

始终建议保持 Reorc Agent 的更新。

要升级 Agent ，请按照以下步骤操作：

1. 停止 Agent 服务

   根据您管理服务的方式，您可能需要运行以下命令之一来停止该进程：

```bash
# if managed by Systemd
sudo systemctl stop reorc-agent

# if managed by Supervisor
supervisorctl stop reorc-agent
```

2. 升级并重新登录

```bash
# Upgrade to the latest version
pip install -U reorc-agent

reorc login
```

3. 启动 Agent&#x20;

```bash
# if managed by Systemd
sudo systemctl start reorc-agent

# if managed by Supervisor
supervisorctl start reorc-agent
```


# 快速开始

本指南将引导您快速上手 Recurve

通过本指南，您可以了解当前测试版中的功能，包括连接数据库、使用数据源、创建数据模型、构建数据管道，并直接从数据管道中安排任务运行。

{% hint style="info" %}
**前提条件：**

* 您已经拥有一个 Recurve 账号，如果没有，可以在此注册： [Recurve](https://www.recurvedata.com/)。
* 您已被邀请加入某个组织，并且该组织中有 1）可用的环境 和 2）正常运行的 Worker。详细说明，请参阅： [设置与部署](/cn-reorc-help-center/she-zhi-yu-bu-shu)。
  {% endhint %}

## 操作流程

您可以按以下步骤快速上手 Recurve：

1. [**添加连接源**](/cn-reorc-help-center/kuai-su-kai-shi/1.-tian-jia-lian-jie-yuan)
   * 将 Recurve 连接到您的数据源（如关系型数据库、数据仓库）。
   * 配置连接的详细信息，以确保数据安全访问。
2. [**创建项目**](/cn-reorc-help-center/kuai-su-kai-shi/2.-chuang-jian-xiang-mu)
   * 设置项目，为您的团队提供一个共同协作的工作空间。
   * 配置项目数据库，用于存储和处理转换后的数据，形成数据处理的核心基础。
3. [**创建数据模型**](/cn-reorc-help-center/kuai-su-kai-shi/3.-chuang-jian-shu-ju-mo-xing)
   * 引用原始数据为源数据。
   * 使用模型定义 ETL 逻辑。
   * 添加测试用例（即将上线），以验证模型转换的正确性，确保数据的准确性。
4. [**在控制台中构建模型**](/cn-reorc-help-center/kuai-su-kai-shi/4.-yan-zheng-shu-ju-chu-li-liu-cheng)
   * 在控制台中运行模型构建，并自动运行数据测试来验证转换效果。
   * 调试失败的测试、优化性能，并根据结果迭代模型以满足业务需求。
5. [**设置数据管道**](/cn-reorc-help-center/kuai-su-kai-shi/5.-chuang-jian-shu-ju-guan-dao-he-diao-du-ren-wu)
   * 将数据模型自动化串联，创建高效的数据流。
   * 配置执行和任务调度。
   * 在“Health Tracking”页面中实时监控数据流调度情况。

在这些步骤中，我们将详细介绍 Recurve 的关键组件，并为每个步骤提供详细相关信息的链接。让我们立即开始探索吧！


# 1. 添加连接源

在开始转换数据之前，您需要建立与数据目的地的连接——ELT（提取/ Extract 、加载/ Load、转换/ Transform ）管道中的“L”（加载）部分。这些目的地是您摄取数据最终存储的地方，无论是数据库、数据仓库还是数据湖。

Recurve 中&#x7684;**“目的地/ Destinations”**&#x90E8;分是您管理这些关键连接点的中心。您可以在这里配置和维护与各种数据存储系统的连接。

对于简单的首次连接，我们建议您设置与关系型数据库或数据仓库的连接，这样原始表格可以直接进行数据建模，而无需额外的转换。

操作步骤：

1. 从 Recurve 的左侧边栏选择 **连接/ Connections > 目的地/ Destinations**。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FJvOQR2tkPLrlMSF0xNJe%2FRecurve_destinations_button.png?alt=media&amp;token=9e4666ab-47cb-4b54-b607-1a6e08a2082c" alt=""><figcaption></figcaption></figure>
2. &#x5728;**“目的地/ Destinations”** 页面，点击 **+ 创建连接/ Create Connection**。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2F97BdnbOyDPiCi8hUGvpq%2FRecurve_destinations_create_connection_button.png?alt=media&amp;token=5aae243e-17f4-4e8c-905d-d6a0fa387a63" alt=""><figcaption></figcaption></figure>
3. 选择与您的数据源的连接器，然后点击 **设置/ Set up。**

   每个连接器都有其自己的身份验证字段和配置参数。您可以查看此处可用的数据源列表：[目标数据库](/cn-reorc-help-center/lian-jie/mu-biao-shu-ju-ku)。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FGi97BQFeVqFipOeuYb4X%2FRecurve_choose_your_destination.png?alt=media&amp;token=e6d3e111-e009-4708-b930-ce5dfce57c43" alt=""><figcaption></figcaption></figure>
4. 提供身份验证详细信息和其他必要信息。例如，我们可以连接到 MySQL 数据库：

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2F8aAfwiG3yX1Y4DliMSfk%2FRecurve_create_a_new_destination.png?alt=media&amp;token=93bfa5bf-f696-43ef-8085-cf1ed600fdcc" alt=""><figcaption></figcaption></figure>

5. 选择目标并点&#x51FB;**“测试连接/ Test Connection”** ，以确保连接成功。对于开发目的，我们在开发环境中测试连接。
6. 点击 **创建目的地/ Create destination**，创建的连接将显示在 **目的地列表/ Destinations** 中。


# 2. 创建项目

一旦您&#x5728;**“目的地/ Destinations”**&#x4E2D;配置了连接，下一步就是创建一个项目。在Recurve中，项目是一个协作工作空间，您的团队可以在其中组织和管理所有与特定数据开发目标相关的数据工作流、模型和转换。

在此步骤中，您还可以选择在上一步中创建的连接，并将它们分配到您的项目中，作为项目连接。此设置定义了构建数据转换工作流所需的数据源。

## 关于项目连接

项目连接是与 Recurve 中特定项目相关联的数据连接。对于每个项目连接，您可以定义连接类型，并为**开发**和**生产环境**指定不同的目标数据库。此设置有助于在将开发环境中所做的更改迁移到生产环境时提供平稳过渡。

虽然一个项目可以拥有多个项目连接，但一次只能将一个连接设置为主数据库。这个主数据库，也称为**项目数据库**，是为大规模数据读取和聚合优化的。项目中的所有模型将在项目数据库下执行和构建。

## 设置项目

请按照以下步骤操作：

1. 从 Recurve 左侧栏选择 **数据开发/ Data development > 数据设计中心/ Data design hub**。

   这将打开 **数据设计中心/ Data design hub**，在这里您可以看到所有项目的列表。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2F9l8rcOFJCBs1Y36CM0Mn%2FRecurve_project_data_design_hub.png?alt=media&amp;token=4ddba330-6ff8-4ed8-bf15-58d77d26572d" alt=""><figcaption></figcaption></figure>
2. 点击 **+添加项目/ +Add Project**。
3. 提供新项目所需的相关信息。

{% tabs %}
{% tab title="1. 通用信息" %}
提供项目名称、标签和描述，以帮助组织您的项目。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FSHdXqnVIDpOXoIrxo1P3%2Fimage.png?alt=media&amp;token=c76d614c-850d-42d3-bad6-b536cfbec773" alt=""><figcaption></figcaption></figure>
{% endtab %}

{% tab title="2. 设置环境" %}
一个项目必须拥有一对开发和生产环境。

{% hint style="info" %}
在当前的测试版发布中，环境设置仅限于默认的开发和生产环境。
{% endhint %}

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FnTFmnAbbHN1hmvt1G9S3%2Fimage.png?alt=media&amp;token=06bc154d-e5ce-48aa-aed0-57f1ae8b368f" alt=""><figcaption></figcaption></figure>
{% endtab %}

{% tab title="3. 项目连接" %}
点击 **+添加/ + Add** 为每个环境指定使用的连接，并为此设置提供一个通用的连接名称。使用您在目的地中设置的连接： [1. 添加连接源](/cn-reorc-help-center/kuai-su-kai-shi/1.-tian-jia-lian-jie-yuan)。

注意，开发和生产环境的连接必须是相同类型的。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FsTh819sf1qBBAfTlsP2U%2Fimage.png?alt=media&amp;token=f5ad85b2-5531-45e8-847c-3fee97ab48e9" alt=""><figcaption></figcaption></figure>
{% endtab %}

{% tab title="4. 设置项目数据库" %}
设置已添加的项目连接为项目数据库，以便最终的数据模型存储在项目数据库中。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FClYBsIadgjyHvTqRXFeg%2Fimage.png?alt=media&amp;token=005aa5c7-f22f-4ad6-8cf3-389432348416" alt=""><figcaption></figcaption></figure>
{% endtab %}
{% endtabs %}

4. 点击 **创建/ Create**。

新项目将在 **数据开发/ Data development** 仪表板中显示。


# 3. 创建数据模型

定义数据源并创建一个简单的数据模型

本节将介绍数据建模的核心概念，帮助您掌握如何使用 Recurve 创建一个简单的数据转换用例。

## Recurve 中的资产

在 Recurve 中，资产是构建数据工作流的核心要素。可以将其视为数据转换过程中创建和管理的关键组件，每种资产类型都发挥着特定作用，共同作用将原始数据转化为有价值的洞察。

在 **数据建模** 中，主要使用以下几类资产：

* **数据源（Sources）：** 指向原始数据，便于连接并记录数据的来源。
* **模型（Models）：**&#x5904;理数据的查询，通过转换生成结构化的、适合分析的数据集。
* **Jinja 宏和变量（Jinja macros and variables）：**&#x4A;inja 模板工具，为 SQL 添加编程逻辑，使转换过程更具动态性和可维护性。

## 数据建模流程

Recurve 的数据建模流程遵循逻辑步骤，帮助您构建和验证转换工作流。

1. **定义源数据：**&#x9996;先定义代表原始数据表的源数据，便于描述和记录数据的来源。
2. **创建数据模型：**&#x5728;源数据基础上创建数据模型，将原始数据转化为有用的分析数据集。每个模型表示一个特定的转换步骤，并逐步构建。
3. **配置物化方式：**&#x6307;定模型结果在数据仓库中的物化方式。
4. **添加数据测试：**&#x4E3A;模型添加数据测试，以确保其正确运行。每次模型成功构建后，这些测试会自动执行。

建议在开发周期中包含以上步骤，以确保转换在应用到生产数据之前正常运行。

## 前提条件

以下操作示例使用由 dbt 社区提供的  `jaffle_shop` 数据集（一个虚构的电商商店）。您可以按照该仓库中的指南生成数据并将其加载到目标数据库： [jaffle-shop-generator](https://github.com/dbt-labs/jaffle-shop-generator)。

## 操作流程

让我们通过实际步骤体验 Recurve 的数据建模流程。

首先，在 **数据开发/  Data development** 仪表板中打开您创建的项目。默认情况下，Recurve 将导航&#x81F3;**“设计/ Design”**&#x90E8;分，在这里完成所有转换活动。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2F4KEwhUWJNrvZ7NWdtrSj%2FRecurve_project_data_section.png?alt=media&amp;token=45a8d941-c6c2-4710-817e-293f30f61ef3" alt=""><figcaption></figcaption></figure>

### 定义源数据

请按照以下步骤操作：

1. &#x5728;**“模型/ Models ”**&#x9009;项卡中，点&#x51FB;**“+”**&#x56FE;标并选&#x62E9;**“添加源/ Add source”**。
2. 在打开的窗口中：
   1. 选择连接类型。
   2. 选择目标连接，即您在 [2. 创建项目](/cn-reorc-help-center/kuai-su-kai-shi/2.-chuang-jian-xiang-mu) 中已设置好的连接。
3. 点&#x51FB;**“下一步/ Next”**&#x540E;，Recurve 将显示目标连接中所有可用的表。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FQPXm5cmfkbBrV0IIQ19K%2FRecurve_add_source_select_tables.png?alt=media&amp;token=fa86f5d7-db16-4ab6-9f24-9c52408639ec" alt=""><figcaption><p>从连接中选择表</p></figcaption></figure>

4. 选择所需的原始表或模型。

   在此示例中，我们选择 `jaffle_shop` 架构下的所有表。

<details>

<summary>jaffle_shop 数据集所含表</summary>

`jaffle_shop` 架构包含以下表：

* Customers：下订单的客户
* Orders：由客户发起的订单
* Products：订单中包含的食品和饮料
* Items：属于产品的订单项
* Supplies：生产产品所需的原材料
* Stores：订单下单和履行的门店

</details>

5. 点&#x51FB;**“添加源/ Add source”**。

选定的表将被添加&#x5230;**“数据源/ Sources”**&#x6587;件夹中，并按架构名称分组。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FnrOEvNmMCgsyH4V6rz6l%2FRecurve_added_sources.png?alt=media&amp;token=a0383586-6c9a-4830-86df-aa3fd8da878a" alt=""><figcaption></figcaption></figure>

### 创建数据模型

为了展示数据模型的动态性和模块化，我们将创建三个模型：

{% tabs %}
{% tab title="stg\_customers" %}
此暂存模型（ Stage model ）通过从原始客户表`customers`中选择相关字段（如`customer_id`，`customer_name`）来标准化客户数据。

此过程使用 Jinja 的  [`{{ source() }}`](/cn-reorc-help-center/advanced_usage/jinja-mu-ban) 函数来引用前一部分中定义的原始表。

```sql
SELECT
  id AS customer_id,
  name AS customer_name
FROM
  {{ source('jaffle-shop', 'raw_customers') }}
```

{% endtab %}

{% tab title="stg\_orders" %}
与 `stg_customers`类似，此暂存模型通过从原始订单表`orders` 中选择并重命名相关字段 （`order_id`、`customer_id`、 `order_date`等） 来标准化订单数据。

```sql
SELECT
  id AS order_id,
  store_id AS location_id,
  customer AS customer_id,
  subtotal AS subtotal_cents,
  tax_paid AS tax_paid_cents,
  order_total AS order_total_cents,
  ordered_at
FROM
  {{ source('jaffle-shop', 'raw_orders') }}
```

{% endtab %}

{% tab title="customers" %}
此模型将客户数据与订单历史整合在一起。

在这里，我们使用 [`{{ ref() }}`](/cn-reorc-help-center/advanced_usage/jinja-mu-ban) 函数引用这两个暂存模型。

{% code overflow="wrap" %}

```sql
-- Reference the staged data (stg_customers and stg_orders) to gather customer information.
WITH
  customers AS (
    SELECT
      *
    FROM
      {{ ref('stg_customers') }}
  ),
  orders AS (
    SELECT
      *
    FROM
      {{ ref('stg_orders') }}
  ),
  -- Aggregate the order data to calculate metrics per customer
  customer_orders AS (
    SELECT
      customer_id,
      min(ordered_at) AS first_order_time,
      max(ordered_at) AS most_recent_order_time,
      count(order_id) AS number_of_orders
    FROM
      orders
    GROUP BY
      1
  ),
  -- Join aggregated data with the customer information to produce details about each customer and their order history
  final AS (
    SELECT
      customers.customer_id,
      customers.customer_name,
      customer_orders.first_order_time,
      customer_orders.most_recent_order_time,
      coalesce(customer_orders.number_of_orders, 0) AS number_of_orders
    FROM
      customers
      LEFT JOIN customer_orders USING (customer_id)
  )
SELECT
  *
FROM
  final
```

{% endcode %}
{% endtab %}
{% endtabs %}

按照以下步骤创建每个模型：

1. &#x5728;**“模型/ Models”**&#x9009;项卡中，点&#x51FB;**“+”**&#x56FE;标并选&#x62E9;**“新建 SQL 模型/ New SQL model”**。
2. 提供模型名称，然后点&#x51FB;**“创建/ Create”**。

   新模型将被放置&#x5728;**“模型/ Models”**&#x6587;件夹中。
3. 打开模型编辑器并粘贴查询。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FJxV4Jo2tcjx3g64Pe4av%2Fimage.png?alt=media&amp;token=05b259b9-e2bf-4e11-b0d7-6e27f4ae718b" alt=""><figcaption></figcaption></figure>
4. 点&#x51FB;**“保存/ Save”**&#x786E;认更改。
5. 点&#x51FB;**“预览/ Preview”**&#x4EE5;查看查询输出，结果将&#x5728;**“结果/ Result”**&#x9009;项卡中显示。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FyLKCZmamYpuUPwqOx9ZF%2Fimage.png?alt=media&amp;token=07ab58b0-d3d7-4097-82e9-095aaf8cdafa" alt=""><figcaption></figcaption></figure>
6. 请按照上述步骤创建其他两个模型。

现在，我们已经创建了两个标准化原始数据的暂存模型，以及一个汇总并整合结果的模型，可以&#x5728;**“数据血缘/ Data linage”**&#x4E2D;查看它们，以更好地理解它们之间的关系。

打开一个模型，并切换&#x5230;**“血缘视图/ Lineage view”**&#x9009;项。这将显示一个 DAG（有向无环图），展示从原始数据到最终下游模型的资产关系。

数据血缘是通过 `source()` 和`ref()` 函数实现的，这些函数会自动跟踪资产的依赖关系。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FJZP54OsFLRgQisbIkRZP%2FRecurve_customers_data_lineage.png?alt=media&amp;token=1143b577-724a-4b6e-81e7-fe7ffbdd6108" alt=""><figcaption></figcaption></figure>

### 配置物化方式

您可以具体配置模型在数据仓库中的物化方式。

默认情况下，所有模型的物化方式为 **表格/ table** 。

按照以下步骤操作：

1. 打开模型编辑器。
2. 点击 ![](https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FP7seWaftdZHu0p9KAoG2%2FRecurve_info_button.png?alt=media\&token=88910478-ad96-4afc-8fb1-33053088e1f1)图标。
3. &#x5728;**“物化方式/ Materialization”**&#x5B57;段中，选择所需的物化方式选项。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2Fs4VBDCfKoJ5d1hxtvyeU%2Fimage.png?alt=media&amp;token=d62dbf91-dea5-4883-9db1-0f02a859e9b4" alt=""><figcaption></figcaption></figure>

继续使用我们的三个示例模型，我们可以将暂存模型物化为视图，以确保它们反映最新的源数据，并最大限度地减少存储成本。另一方面，汇总模型可以物化为表格，因为它是最终模型，且查询频率较高。

### 添加数据测试

{% hint style="info" %}
**即将上线:** 数据测试部分即将上线。
{% endhint %}

数据测试是简单的 SQL 查询，它根据您设置的条件返回失败的记录。这些测试用于验证转换后数据的正确性，确保模型的结果符合预定义的标准。

Recurve 提供了一系列内置测试，您可以快速将其添加到模型中。

按照以下步骤向模型添加测试：

1. 打开模型编辑器。

2. 切换&#x5230;**“测试用例/ Test cases”**&#x9009;项卡。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FtgXCBnVqKlGdFNLCo11K%2FRecurve_test_case_tab.png?alt=media&amp;token=131350dc-e706-42df-9028-cf3416a75ab1" alt=""><figcaption></figcaption></figure>

3. 点击 **+ 添加新建/ + Add new**。

4. 选择一个模板并指定相应的值。

   例如，对于 `stg_orders` 模型，我们可以添加 "空值" 测试，以验证日期列中是否存在`null` 值。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FSCP4rCkzXN7KzWWW1CkQ%2FRecurve_empty_value_check_stg_orders.png?alt=media&amp;token=07083849-38a2-495f-af38-7e75201310d4" alt=""><figcaption></figcaption></figure>

5. 点击 **添加/ Add。**

新的测试将被添加到模型的测试用例列表中，并将在每次模型在控制台运行或作为管道的一部分运行时自动执行。


# 4. 验证数据处理流程

在发布和部署到生产环境之前，你可以使用 Recurve 的控制台（Console）在开发环境下模拟运行并构建数据模型。通过开发与生产环境的隔离，能够在不影响生产数据的情况下，快速验证数据处理逻辑。

控制台会构建模型并自动执行所有关联的数据测试。您可以检查生成的数据和测试结果，以便迭代改进数据清洗流程。

## 使用控制台

1. 在 **设计/Design** 中，点击底部工具栏的 **控制台/Console**，打开控制台部分。
2. 点击 **选择资产或管道/Choose assets or pipeline**。
3. 在弹出的窗口中，选择 **模型/Models** 并选中指定模型。

   我们可以选择这三个模型来验证它们。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FBH1Zi6bQlc7LxHPjVE34%2FRecurve_console_pop_up.png?alt=media&amp;token=e7a8e978-082e-48c6-82d0-ca0a8beeca19" alt=""><figcaption></figcaption></figure>
4. 点击**保存/Save**。
5. 点击**运行/Run**。

   每个模型将会作为独立任务执行运行，运行顺序将按其依赖关系的顺序。

## 执行结果

任务运行需要一些时间，您可以监控每个任务的执行状态，任务将与其对应的模型一起显示。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2F5thSpaaFDAVk3IIrla82%2FRecurve_console_results.png?alt=media&amp;token=343ec589-6d6e-48d1-b2cc-8f6b506c6335" alt=""><figcaption></figcaption></figure>

如果出现错误，可点击任务以查看详细日志。在 **运行日志/Run logs** 标签页中，你可以查看模型构建过程的错误日志和测试用例结果。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FCXmmr6EskkGLLFnogeOW%2Fimage.png?alt=media&amp;token=c6a1fddb-f3fc-4073-b9a9-733dc327353e" alt=""><figcaption></figcaption></figure>


# 5. 创建数据管道和调度任务

在将模型创建和优化完成后，可以创建一个数据管道，并创建任务来调度工作流的执行。这确保了每次运行时转换的可复现性和可靠性。

## 发布模型

在从模型创建管道之前，您需要先发布模型。打开每个模型，并按照以下步骤操作：

1. 在右上角，点击 **发布/ Publish**。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FW5e3L8VLl1pib22b0eqD%2FRecurve_editor_publish_button.png?alt=media&amp;token=a2696053-fb21-493a-bbac-a8c66273820a" alt=""><figcaption></figcaption></figure>

2. 填写版本号和描述。

   对于第一次发布，我们将保持默认设置。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2Fwp1iNnVXpxypVpJTRoVT%2FRecurve_publish_model_pop_up.png?alt=media&amp;token=c2f3cf61-10e4-4d05-9981-a6cf9c7599ef" alt="" width="375"><figcaption></figcaption></figure>

3. 点击**发布/ Publish**。

数据模型现在已准备好，可以继续创建数据建模管道。

## 创建数据建模管道

请按照以下步骤操作：

1. 切换到 **数据管道/Pipelines** 标签页。
2. 点击 **+** 图标，选择 **创建建模管道/Creating modeling pipeline**。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2F3kAxWCq1thRKB3oPGFYs%2FRecurve_create_new_modeling_pipeline.png?alt=media&amp;token=05d26cad-bb99-4be5-95d7-4c652a26ee09" alt=""><figcaption></figcaption></figure>
3. 为您的数据管道提供名称。
4. 选择该数据管道应包含的数据模型。

   此处，我们添加在前一步设置的三个模型。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2Ft682H8veW2rvrYrcdrKT%2FRecurve_modeling_pipeline_customers.png?alt=media&amp;token=17600a6e-baef-4299-9d76-7af09b50a559" alt=""><figcaption></figcaption></figure>
5. 点击**确认/ Confirm**。

   新建的建模管道将被添加到 **模型/ Models** 文件夹下，并在 DAG 视图中展示。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FKnyzkWVKUwGzjs9sBMa7%2FRecurve_modeling_pipeline_example.png?alt=media&amp;token=f74c698f-ee36-4441-ae7c-89aa9a53ec76" alt=""><figcaption></figcaption></figure>
6. 点击**发布/ Publish**。

## 创建调度任务

数据管道创建并发布后，您可以创建任务来调度执行时间。请按照以下步骤操作：

1. 打开您创建的数据管道。
2. 切换到 **调度/Jobs** 标签页，点击 **创建调度/Create a job**。
3. 填写任务配置。

{% tabs %}
{% tab title="1. 基础设置" %}
填写名称、选择目标环境，并自定义关联的模型变量。

由于我们已经通过控制台执行并验证了模型，现在可以选择 **生产环境** 来在生产数据库上运行数据清洗流程。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FjWvZ7UgZQ2sQkYLb3RT3%2FRecurve_job_create_step_1.png?alt=media&amp;token=48247bb7-b738-43b9-88d4-31ea607647ef" alt=""><figcaption></figcaption></figure>
{% endtab %}

{% tab title="2. 调度设置" %}
填写任务的时间安排和触发类型：

* 标准设置：在特定时间间隔内触发运行。
* 高级设置：使用 crontab 格式指定调度，适用于熟悉 `cron` 调度器的用户。请参考文档： [Cron](https://en.wikipedia.org/wiki/Cron)。
* 手动触发：不进行调度，可以在 **数据管道健康/Pipeline Health** 仪表板中手动触发。请参考： [数据管道健康](/cn-reorc-help-center/jian-kang-jian-ce/shu-ju-guan-dao-jian-kang)。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2F5dhNNlGaOqVO5dxTOYOF%2FRecurve_job_creation_step_2.png?alt=media&amp;token=f91b788f-6cd5-4a99-9abe-3a820131fc13" alt=""><figcaption></figcaption></figure>
{% endtab %}

{% tab title="3. 提醒设置" %}
在此处，您可以配置任务失败时的通知。默认情况下，通知会通过电子邮件发送。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FKgFrbyObkD4JdhOsxgQO%2FRecurve_job_creation_step_3.png?alt=media&amp;token=89e55af5-02f5-451d-9b5e-2360ab8c1bcd" alt=""><figcaption></figcaption></figure>
{% endtab %}
{% endtabs %}

4. 点击**创建/ Create。**

新任务将显示在 **调度/Jobs** 部分，Recurve 将在预定时间执行该任务。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FSHy0XosAR5XwsafSwqWd%2FRecurve_pipeline_jobs_tab_created_job.png?alt=media&amp;token=ea8227af-b1b4-42ff-a82f-d030aace4701" alt=""><figcaption></figcaption></figure>

您可以在 [数据管道健康](/cn-reorc-help-center/jian-kang-jian-ce/shu-ju-guan-dao-jian-kang) 中查看任务的执行状态和进度。

{% hint style="success" %}
恭喜！您已经完成了使用 Recurve 构建数据工作流的过程。
{% endhint %}

下一步，您可以详细探索每个功能和模块：

<table data-view="cards"><thead><tr><th></th><th></th><th></th><th data-hidden data-card-target data-type="content-ref"></th></tr></thead><tbody><tr><td><strong>连接 | Connections</strong></td><td>了解可用的连接</td><td></td><td><a href="/cn-reorc-help-center/lian-jie/mu-biao-shu-ju-ku">连接</a></td></tr><tr><td><strong>数据建模 | Data modeling</strong></td><td>了解数据建模中的核心内容</td><td></td><td><a href="/cn-reorc-help-center/shu-ju-jian-mo/gai-shu">概述</a></td></tr><tr><td><strong>健康监控 | Health tracking</strong></td><td>探索健康监控仪表板</td><td></td><td><a href="/cn-reorc-help-center/jian-kang-jian-ce/shu-ju-guan-dao-jian-kang">数据管道健康</a></td></tr></tbody></table>


# 目标数据库

目标数据库/Destinations 部分包含项目中可用的所有数据源连接。Recurve 提供了广泛的数据源连接器，以满足不同业务的灵活需求和目标。

每个数据源/数据提供方可能需要特定的身份验证方法和参数配置，以确保数据安全和访问权限。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FrsIb3HBGDhQ1XV3pkKKZ%2Fimage.png?alt=media&amp;token=2d9149b7-b413-428f-85bc-fd22ccc2bb70" alt=""><figcaption></figcaption></figure>

以下是 Recurve 支持的数据源列表：

## 数据仓库

* Azure Synapse
* Big Query
* Hive
* Impala

## 数据库

* ClickHouse
* Apache Doris
* Elastic Search
* MongoDB
* Microsoft SQL Server
* MySQL
* HBase Phoenix
* PostgreSQL
* Redshift
* Spark
* StarRocks
* TiDB

## 数据存储

* Azure Blob
* FTP
* Google Cloud Storage
* Aliyun OSS
* OwnCloud
* Amazon S3
* SFTP
* Tencent COS


# Integration

Integration


# 项目连接管理

项目连接是与 Recurve 中特定项目关联的数据连接。对于每个项目连接，您可以定义连接类型，并为**开发**和**生产环境**分别指定目标数据库。此设置确保将修改从开发环境推广到生产环境时的平稳过渡。

尽管一个项目可以拥有多个项目连接，但同一时间只能有一个连接被设为主数据库。这个主数据库也被称为**分析数据库**，它经过优化，适合大批量的数据读取和聚合。项目中的所有模型都会在该数据库下执行和构建。

本指南将向您展示如何创建项目连接并设置分析数据库。

## 创建项目连接

按照以下步骤操作：

1. 打开您的项目，进入 **设置/ Settings > 数据连接/ Data connections**。
2. &#x5728;**“定义连接/ Define connection”**&#x90E8;分，点击 **+ 添加连接/ + Add connection**。
3. 提供连接名称，并为开发和生产环境选择相同的连接类型。

   注意，开发和生产环境必须为相同的连接类型。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2F1rsUTysiJq78f2TPnjES%2FRecurve_project_creation_3_project_connection.png?alt=media&amp;token=aec29734-fc6e-47f2-86a9-840b459d40d8" alt=""><figcaption></figcaption></figure>

## 设置分析数据库

如果你想将其他连接设置为分析数据库，请按照以下步骤操作：

1. 打开您的项目，进&#x5165;**“设置/ Settings”>“数据连接/ Data connections”**。
2. 点击连接源旁边的选中按钮。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2F4iIRYOnh38G8CnRwMAUo%2FRecurve_set_analytics_database_confirm.png?alt=media&amp;token=cdde4361-1144-4e24-af38-94678b7c1828" alt=""><figcaption></figcaption></figure>
3. 在弹出的窗口中点击“确认/ **Confirm**”。


# 概述

Recurve 数据建模简介

数据转换（ETL）是构建有效数据管道的关键步骤之一。在这个阶段，从集中式数据库或数据仓库加载的原始数据被转换成所需的结构和格式，以便分析师可以提取出符合业务需求的关键洞察。

现代数据转换工具通过将软件工程原则应用于分析领域，显著提升了这一过程的效率，如 [*dbt*](https://www.getdbt.com/) (Data Build Tool) 。这些原则包括模块化 SQL 脚本编写、版本控制、验证以及与编排平台的集成。这种方法使得数据转换更加可靠且具有可扩展性。

Recurve 采用了开源 dbt 的最佳实践，并结合自身的设计元素进行优化，为用户提供了一个功能强大的数据转换工作空间，所有操作均在 **数据建模** 模块中完成。

## 组件

如果您之前使用过 dbt，Recurve 数据建模模块中的一些概念对您来说可能会比较熟悉。Recurve 利用了开源 dbt 的多种数据转换技术和组件，并通过直观的资产管理系统对它们进行了增强。

以下是一些操作指南，帮助您在 Recurve 中顺利开始数据建模。

* [**数据源**](/cn-reorc-help-center/shu-ju-jian-mo/shu-ju-yuan)（Sources）：数据源是对数据库中的原始表或在其他项目中定义的模型的引用。这些数据源作为数据转换的输入。
* [**模型**](/cn-reorc-help-center/shu-ju-jian-mo/mo-xing)（Models）：用于处理数据、应用转换并输出结构化数据集的查询。Recurve 目前支持 SQL 语言编写的模型。
* [**Jinja 模板**](/cn-reorc-help-center/advanced_usage/jinja-mu-ban)（Jinja templating）：Jinja 是一种最初用于 Python 生态系统的模板语言。使用 Jinja，您可以在 SQL 转换中加入编程特性，如循环、变量和函数（或宏），从而增强 SQL 的灵活性。
* [**数据血缘**](/cn-reorc-help-center/shu-ju-jian-mo/shu-ju-xue-yuan)（Data lineage）：数据血缘提供了数据在各个转换过程中的可视化流向，从源头到目标。该功能帮助您了解转换如何影响下游输出。
* ***（即将上线）*****数据测试**（Data tests）：数据测试是对项目中的模型和资源所设定的校验条件。通过这些测试，可以验证数据转换的准确性，确保模型输出结果符合预定义的标准。


# 数据源

数据源（Sources）是指数据库中原始表的引用，您可以在模型中使用这些数据源。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2Fk7MmWPC5zbuksK4yr2nt%2FSources_diagram.png?alt=media&amp;token=2469c3e1-3ec1-4bd2-a1d5-07257a507cf4" alt=""><figcaption></figcaption></figure>

在传统的 SQL 转换中，原始表通常通过表名直接引用。这会带来一些问题，例如代码可读性差、表间的依赖管理难。相比之下，数据源提供了一种更结构化和模块化的方式来引用原始表，带来以下几个优点：

* **清晰的数据血缘**：将原始表定义为数据源可以帮助您明确标识外部数据源，从而建立清晰的数据血缘关系，便于追踪数据从源头到转换模型的流动。
* **数据测试**：声明数据源后，您可以实施数据测试，验证数据质量假设，确保后续的转换操作基于可信的数据。
* **改善沟通**：在数据源的元数据中，您可以添加描述、负责人等信息，以明确您的使用场景。这有助于提高透明度，促进跨团队的有效沟通。

## 创建数据源

要创建数据源，请按照以下步骤操作：

1. &#x5728;**“模型/ Models”**&#x6807;签页中，点击 **+** 图标并选&#x62E9;**“添加数据源/Add source”**。
2. 在弹出的窗口中：
   1. 选择连接类型。目前，Recurve 支持从数据仓库中引用数据源。
   2. 选择目标连接。如果您还没有设置过连接，请参考：[项目连接管理](/cn-reorc-help-center/lian-jie/xiang-mu-lian-jie-guan-li)。
3. 点&#x51FB;**“下一步/ Next ”**。Recurve 将显示目标连接中所有可用的表。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FQPXm5cmfkbBrV0IIQ19K%2FRecurve_add_source_select_tables.png?alt=media&amp;token=fa86f5d7-db16-4ab6-9f24-9c52408639ec" alt=""><figcaption><p>从连接中选择表</p></figcaption></figure>

4. 选择所需的原始表或模型。&#x20;
5. 点&#x51FB;**“添加数据源/ Add source ”**。

选定的表将被添加&#x5230;**“数据源/ Sources ”**&#x6587;件夹，并按连接名称进行分组。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FP1PJ7H6CVFFxZzMKUhkO%2Fimage.png?alt=media&amp;token=39d014f1-d980-4bad-bdd5-1cb0694221b4" alt=""><figcaption></figcaption></figure>

您可以通过在编辑器中打开数据源来查看其架构，架构包含字段名（或列名）、数据类型和注释。

## 从数据源中选择

通过将原始表组织为数据源，您可以使用 `{{ source() }}` Jinja 函数在模型中引用它们。 请查阅： [Jinja 模板](/cn-reorc-help-center/advanced_usage/jinja-mu-ban)。

该函数需要两个参数：

* `source_name`: 包含数据源的文件夹名称。
* `table_name`: 表的名称。

例如，如果 `raw_orders` 表被添加到 `jaffle_shop`文件夹下，我们可以这样引用：

```sql
select 
    id as order_id,
    customer as customer_id,
    ordered_at as order_date

from {{ source("jaffle_shop", "raw_orders") }}
```


# 模型

模型（Models）是一种用于从数据源提取数据，进行转换的查询，并生成结构化的数据集。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2F7N13ALjCuAIhY8Uuarsn%2FModels_diagram.png?alt=media&amp;token=249d1a52-c3aa-4245-8e44-30d9dcb4cfe0" alt=""><figcaption></figcaption></figure>

Recurve 当前支持使用 SQL 编写模型。

以下示例展示了 SQL 模型的基本语法：

* 模型的核心是对数据源的常规查询。
* 最终通过一个 SELECT 语句完成数据转换。
* 此外，Jinja 模板语言被集成进来，以便进行引用并增强逻辑处理。请查阅： [Jinja 模板](/cn-reorc-help-center/advanced_usage/jinja-mu-ban)。

```sql
-- Select the total number of orders per customer
select
    customers.customer_id,
    customers.first_name,
    customers.last_name,
    count(orders.order_id) as total_orders
from
    {{ source('jaffle_shop', 'raw_customers') }} as customers
join
    {{ source('jaffle_shop', 'raw_orders') }} as orders
on
    customers.customer_id = orders.customer_id
group by
    customers.customer_id,
    customers.first_name,
    customers.last_name
order by
    total_orders desc
```

当 Recurve 运行您的 SQL 模型时，它会将这些模型编译为可执行的 SQL 查询。这一过程包括解析所有的 Jinja 表达式、基于`ref()` 和`source()` 调用来解析模型和数据源的依赖关系，并结合配置（如物化类型）生成最终的 SQL。

将数据转换逻辑作为模型实现，带来了多种优势：

* 简化操作：可以将复杂的转换拆分为更小的、易管理的步骤。
* 模块化和可复用性：某些转换逻辑可以提取为基础模型，在多个地方复用，使得转换可以逐步构建，而不是从头开始。
* 数据血缘和透明性：模型之间的关系会自动跟踪并展示在数据血缘图中，有助于理解模型依赖，方便调试。请参考： [数据血缘](/cn-reorc-help-center/shu-ju-jian-mo/shu-ju-xue-yuan)。
* （即将上线）测试和验证：您可以为每个模型编写测试，以确保数据质量。在模型运行时与测试一并执行，从而尽早捕捉数据问题。&#x20;

## 创建 SQL 模型

创建 SQL 模型的步骤如下：

1. 在“**模型 / Models**” 选项卡中，点击 **+ 图标** 并选择 “**新建 SQL 模型 / New SQL model**”**。**
2. 为模型提供一个名称，然后点击 “**创建 / Create**”。

   创建的模型将会显示在 **models** 文件夹下。
3. 在模型编辑器中，输入您的 SQL 查询。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FAKmzi35IKNpKyGh4Mjmb%2Fimage.png?alt=media&amp;token=36075899-180a-40a9-9f9d-795c20933974" alt=""><figcaption></figcaption></figure>

示例如下：

```sql
-- select customers from raw_customers table
select id as customer_id
       name as customer_name
from {{ source('jaffle_shop', 'raw_customers') }}
```

4. 点击 “**保存 / Save**” 以确认更改。
5. 点击 “**预览 / Preview**” 以查看查询结果，在 “**结果 / Results**” 选项卡中展示输出。

   <figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FJkQ0qUmb903lmoOtYNcm%2Fimage.png?alt=media&amp;token=41c942db-9de8-4587-8b78-3cf1d8f1d5b8" alt=""><figcaption></figcaption></figure>
6. 要查看模型的编译代码，请点击 “**编译代码 / Compiled code”**。

## 引用模型

在一个模型中引用另一个模型，允许您在现有的转换基础上进行扩展，而无需重复编写。这种模块化的方法使得数据转换更加简洁，逻辑更易于维护和理解。

在模型中，您可以使用 `ref()` 函数来引用其他模型。此函数会在模型之间建立依赖关系，确保模型按正确的顺序构建。

示例如下：

```sql
-- model: stg_orders
select
    id as order_id,
    user_id as customer_id,
    order_date,
    status,
    amount
from {{ source('jaffle_shop', 'orders') }}
```

```sql
-- model: mart_daily_revenue

select
    date_trunc('day', order_date) as date,
    count(*) as number_of_orders,
    sum(amount) as daily_revenue
from {{ ref('stg_orders') }}
where status = 'completed'
group by 1
order by 1 desc
```

在  `mart_daily_revenu`中， `ref('stg_orders')` 函数引用了 `stg_oders` 作为依赖。这个引用使得当前模型能够利用模型的结果，并确保模型构建时按正确的顺序进行。

## 组织模型

由于数据转换可能遵循不同的策略并经过多个阶段，您可以将模型按转换的不同阶段组织到文件夹中，从而帮助保持项目结构的清晰和逻辑性。

要创建新的文件夹，点击现有文件夹的操作按钮，并选择 “**添加子文件夹/** **Add sub-folder**”：

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FeTKWvbA6EuFPuKMcmYB4%2Fimage.png?alt=media&amp;token=915cdc29-727e-40db-a913-5c2084a775a4" alt=""><figcaption></figcaption></figure>

要将模型移动到新文件夹中，点击模型的操作按钮，并选择 “**移动/ Move**”。然后，从列表中选择目标文件夹。&#x20;

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FDduOvrLDhzv5H9pIlVsE%2Fimage.png?alt=media&amp;token=f0327b61-d7fe-4ea3-b02d-d10e451fa626" alt=""><figcaption></figcaption></figure>


# 宏

在 Jinja 中，宏（Macro）类似于编程语言中的函数。它允许你定义可重用的代码块，接受参数、处理逻辑并返回结果。Jinja 宏常用于 SQL 模型中，以封装转换逻辑，避免重复的 SQL 代码，从而提升可维护性。

在 Recurve 项目中，你可以将宏定义为资产，并在不同模块和多个模型中复用。

## 语法

Jinja 宏通过 `{% macro %}` 和`{% endmacro %}` 语句进行定义。与 Python 函数类似，宏接受参数、处理逻辑并返回结果。

示例如下：

```sql
{% macro filter_by_status(min_amount, status='completed') %}
    select *
    from {{ source('jaffle_shop', 'orders') }}
    where status = '{{ status }}'
    and amount >= {{ min_amount }}
{% endmacro %}
```

上面的代码定义了一个名为 `filter_by_status` 的宏，该宏根据参数`min_amount` 和可选参数 `status`的值，从 `orders` 表中查询所有符合条件的订单记录。

## 定义宏

要定义一个项目级宏，请按照以下步骤操作：

1. 在 Recurve 中打开你的项目，进入 **Library** > **Macro。**
2. 点击 “**新建 + Add New”。**
3. 输入宏的名称、描述和 SQL 代码。

<figure><img src="https://3914025029-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FMNJfiu2Or0lnmkm2x228%2Fuploads%2FtL7K3HJmS0LTuOg530jc%2FRecurve_add_a_macro_example.png?alt=media&amp;token=1be153e9-1b2a-4a13-94fe-95cc70bcc137" alt=""><figcaption></figcaption></figure>

4. 点击 **“创建/Add”。**

新创建的宏将显示在 **Library** 的 **Macro** 部分。

默认情况下，创建的宏是启用状态，可以立即在模型中使用。如果需要停用宏，可以通过关闭 “**启用/ Active**” 选项来禁用它。

## 调用宏

在宏被定义并启用后，你可以在项目中的任何模型中调用它。宏通过 `{{ ... }}` 表达式进行调用。

例如，使用 `filter_by_status` 宏，我们可以进一步筛选出高价值的已完成订单。

<pre class="language-sql"><code class="lang-sql"><strong>with filtered_orders as (
</strong>   {{ filter_by_status(min_amount=50, status='completed') }}
),

enriched_orders as (
   select 
       order_id,
       amount,
       order_date,
       customer_id,
       case when amount > 100 then 'high_value' else 'standard' end as order_tier
   from filtered_orders
)

select * from enriched_orders
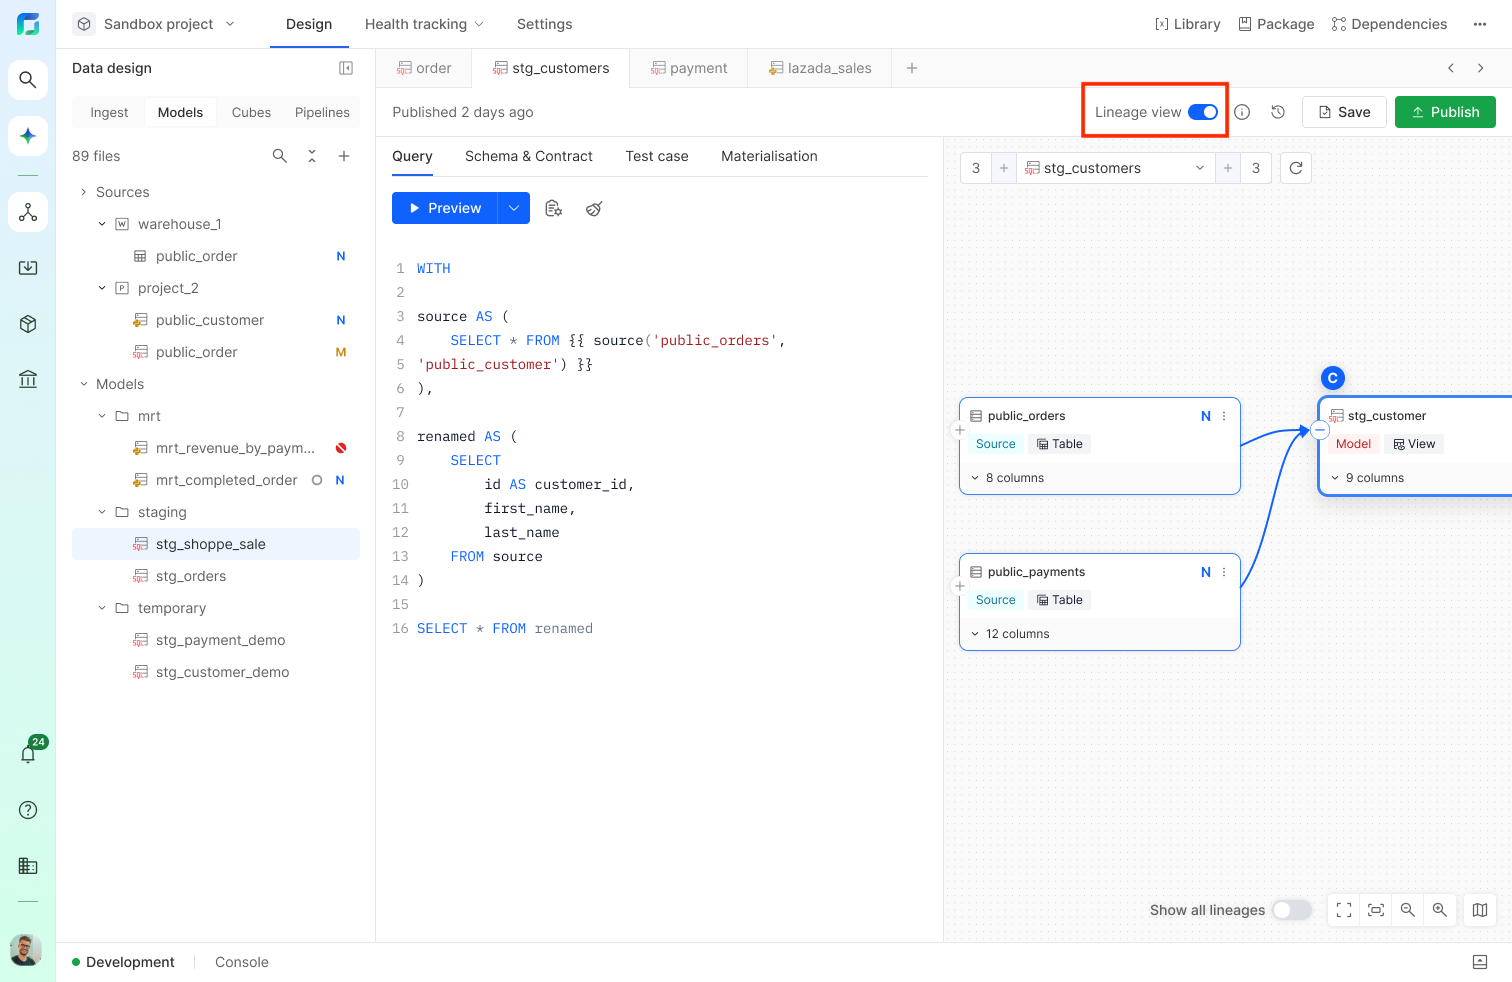
</code></pre>

## 编译结果

```sql
with filtered_orders as (
    -- 按照传入的参数取值渲染可重用的代码
    select *
    from {{ source('jaffle_shop', 'orders') }}
    where status = 'completed'
    and amount >= 50
),

enriched_orders as (
   select 
       order_id,
       amount,
       order_date,
       customer_id,
       case when amount > 100 then 'high_value' else 'standard' end as order_tier
   from filtered_orders
)

select * from enriched_orders
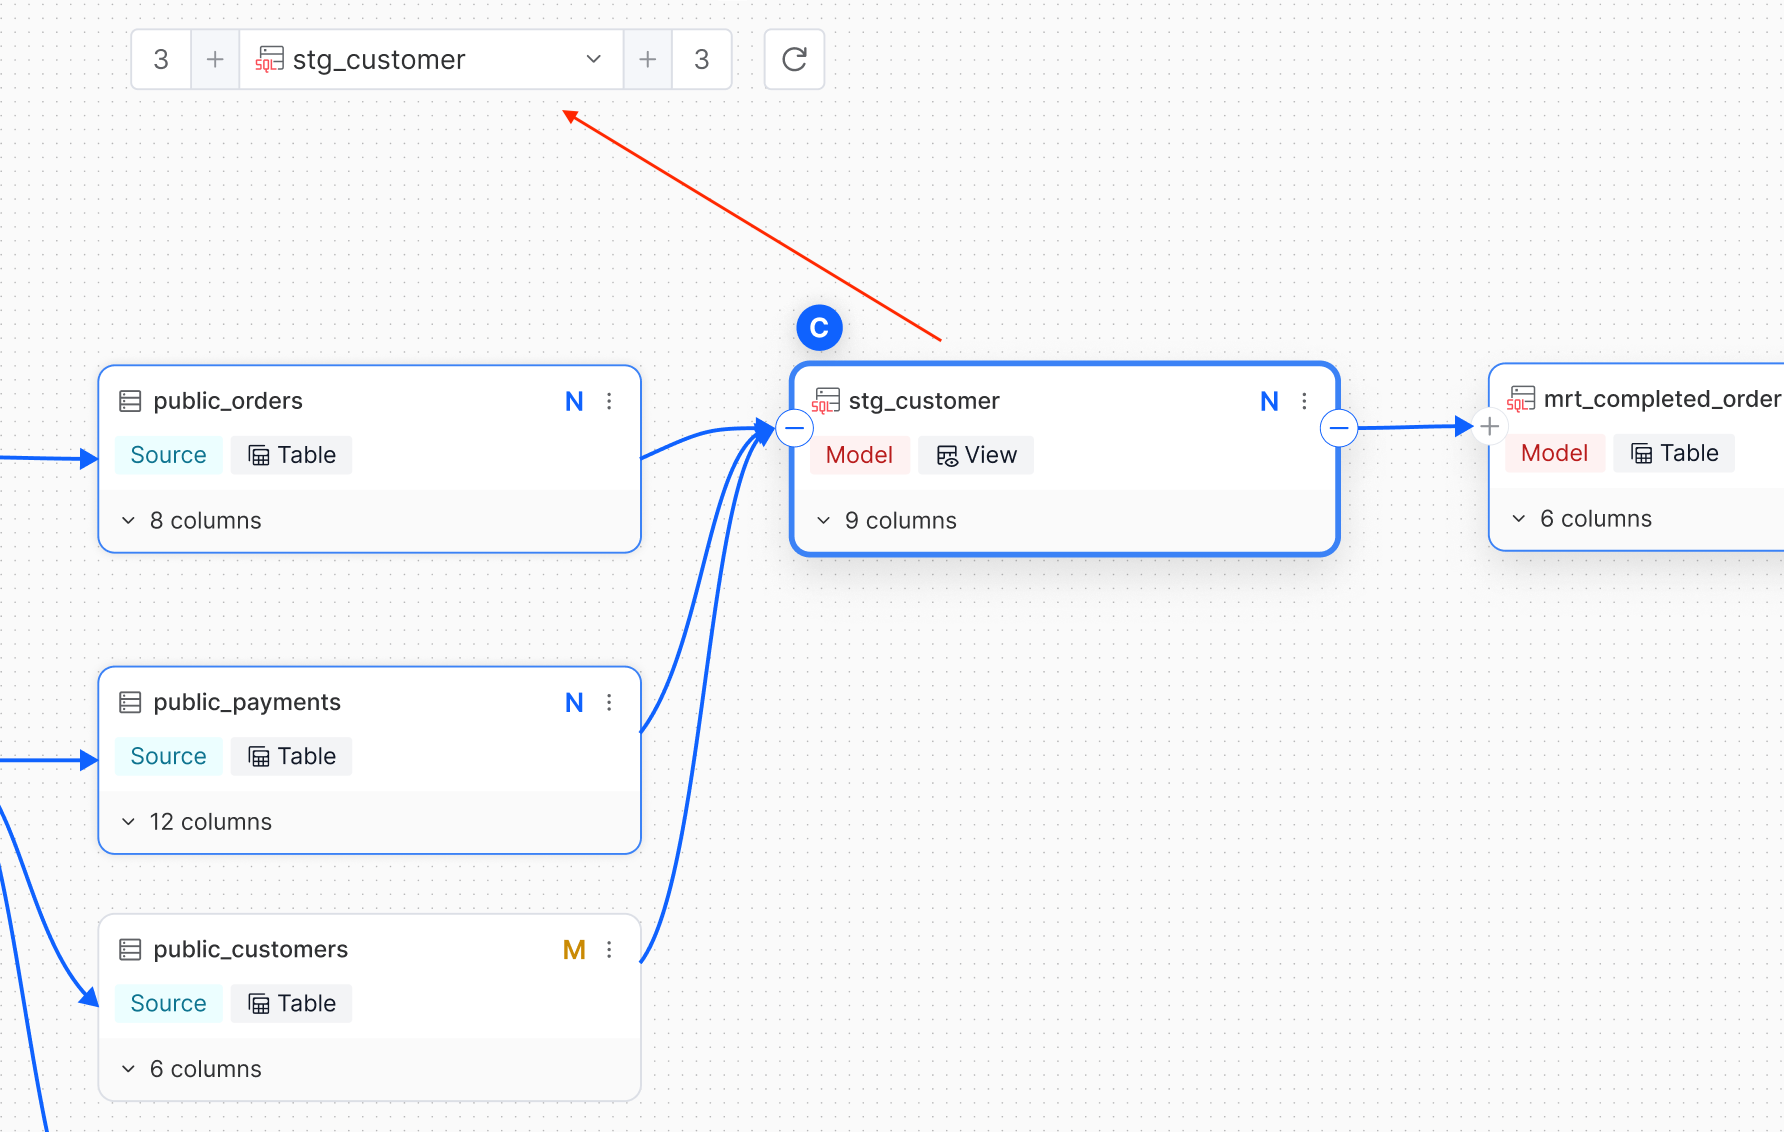
```


# 物化

在模型中运行转换时，你可以定义如何将生成的结果存储或物化（Materialization）到目标数据库中。Recurve 支持以下物化选项：

* 表 (Table)
* 视图 (View)
* 增量 (Incremental)
* 临时 (Ephemeral)

根据你的转换用例，你可以选择不同的物化策略。你可以在 [元数据](/cn-reorc-help-center/zi-chan-guan-li/yuan-shu-ju) 部分查看并配置模型的物化方式。&#x20;

{% hint style="info" %}
默认情况下，所有模型都会物化为表（Table）。
{% endhint %}

## 表 （Table）

**定义：**&#x521B;建一个表并在构建模型时存储结果。每次运行模型时，表会被删除并用最新的数据重新创建。

**使用场景：**&#x5F53;你需要将数据物理存储，并且希望通过更快的查询性能换取额外的存储空间时，可以使用表。

## 视图 （View）

**定义**：在数据库中创建一个视图，视图只是一个存储的查询，不保存数据，而是提供一个虚拟的表环境，便于执行复杂的操作。

**使用场景**：当你不想存储物理表，并且可以接受每次访问视图时重新执行查询的性能开销时，使用视图是一个不错的选择。

## 增量 （Incremental）

**定义**：向已有的表中添加新的或更新的记录，而不是重新创建整个表。

**使用场景**：适用于处理非常大的数据集，每次重建整个表会很低效。增量模式只会处理自上次运行以来新增或更新的数据。

## 临时 （Ephemeral）

**定义**：模型本身不会被物化，而是会将模型片段插入到引用它的下游模型中。类似于将模型片段视为公共表表达式（CTE）。

**使用场景**：适用于不需要存储的中间计算，这些计算只会在下游模型中被引用。


# 模型配置

你可以使用 `config()` 宏来实现更细粒度且更强大的模型控制。

## `config()` 的特点

### **1. 物化设置**

`config()` 宏使用户能够决定模型在分析数据库中的物化方式，常见的物化策略包括：

* **Table（表）**：模型以表的形式创建。
* **View（视图）**：模型以视图的形式创建。
* **Incremental（增量）**：模型以增量方式构建，仅更新自上次运行以来的新数据，提高大数据集的处理效率。

### **2. 主键和分区设置**

使用 `config()` 宏定义的配置可以继承或覆盖其他位置（如模型的元数据）中定义的设置。用户可以在 `config()` 宏中定义多种配置，包括：

* 为增量模型设置主键（unique key）。
* 指定增量策略（incremental strategy）。
* 指定分区（partition）。

不同数据库类型可以使用的 config 配置项有所差异，详见 [数据库特定配置](/cn-reorc-help-center/shu-ju-jian-mo/shu-ju-ku-te-ding-pei-zhi)

### **3. 配置示例**

config() 配置一般放置在模型代码的开头，例如：

```sql
-- models/model_name.sql
{{ config(
    materialized='incremental',
    unique_key='id'
) }}

SELECT *
FROM {{ ref('source_table') }}
```

***

## 配置增量模型

`config()` 宏的一个常见用途是定义数据模型的增量策略。

**增量（Incremental）** 是一种物化方式，每次运行时仅更新新增数据。相比于全量更新的表（Table），增量模型能够减少数据转换所需的时间和资源，适用于周期性更新的大数据集。

在模型的元数据面板中，你可以指定物化选项为 `incremental`。默认情况下，此选项采用 **追加（append）** 的方式，每次构建时仅向表中追加新数据，可能会导致重复数据的写入。

因此，你可以指定以下配置来实现按主键字段增量更新：

* **`unique_key`**：定义数据的唯一标识符，实际运行时会根据主键字段的取值是否已存在，来决定插入新记录还是更新现有记录。
* **`incremental_strategy`**：处理增量更新的方式，常见策略包括：
  * **merge**：基于唯一键更新现有记录并插入新记录。
  * **append**：仅追加新记录，不更新现有记录。
  * **insert\_overwrite**：根据指定条件覆盖现有记录。
* **`is_incremental()`**：用于筛选在运行过程中应增量更新的数据。你可以借助此语法指定增量更新的数据范围

**示例：**

在 `orders`（订单）表中，我们可以实现增量物化，使其仅处理自上次运行以来新增或更新的订单，以减少处理时间并确保表数据保持最新：

```sql
{{ config(
    materialized='incremental',
    unique_key='id',
    incremental_strategy='merge'
) }}

SELECT *  
FROM {{ source("public", "raw_orders") }}  
{% if is_incremental() %}  -- 仅处理新记录
    WHERE ordered_at >= (SELECT MAX(ordered_at) FROM {{ this }})
{% endif %}
```

***

### 数据库特定配置

由于不同数据库平台在优化数据处理方面采用不同的方法，因此某些配置是专门为特定平台设计和应用的。有关这些平台特定配置和行为的详细信息，请参考 **PLATFORM SPECIFIC** 文档。


# 字段列表


# 数据血缘

数据血缘（Data lineage）有助于追踪数据在转换过程中的流动，从源头到模型。它显示了数据集之间的依赖关系及其变换过程，帮助更好地理解数据处理中的各个环节以及变更的影响。

在 Recurve 中，数据血缘通过有向无环图（DAG）进行表示。每次编辑资产并通过 `ref()` 或`source()` 函数引用其他资产时，Recurve 会自动跟踪这些关系，并在 DAG 视图中进行展示。

## 查看数据血缘

要在 Recurve 中查看数据血缘，请打开某个资产的编辑器，并启用 **“血缘视图/ Lineage view”** 选项。&#x20;

在血缘视图中，所有资产将以节点形式展示，通过连接线显示它们之间的关系。你可以点击并拖动节点来调整位置，以获得更加清晰的视图。

左下角的工具栏支持扩展血缘部分、放大或缩小视图，并聚焦当前资产的节点。

<figure><img src="https://content.gitbook.com/content/MNJfiu2Or0lnmkm2x228/blobs/2oOqdXW3N59VdqinarIB/Recurve_data_model_lineage.png" alt=""><figcaption></figcaption></figure>

## 数据血缘导航

### 以中心节点为主

默认情况下，选中的资产/节点会作为中心节点显示。在项目比较大且转换流程复杂时，某个资产可能会有很多关联的节点。通过聚焦一个节点，血缘视图能帮助你查看该资产的信息，以及它与上游和下游模型的关系，从而更好地优化整个转换流程。

<figure><img src="https://content.gitbook.com/content/MNJfiu2Or0lnmkm2x228/blobs/NX1WZQlC8PyjGSIizcoq/Recurve_lineage_view_centric_node.png" alt=""><figcaption></figcaption></figure>

您还可以使用左上角的搜索栏来查找特定资产，并调整当前节点的上游和下游层级数。

### 显示所有血缘

如果你想查看项目中所有资产的完整数据血缘，可以开启 **“显示所有血缘/ Show all lineages”** 选项。

<figure><img src="https://content.gitbook.com/content/MNJfiu2Or0lnmkm2x228/blobs/EOtmai0pfpfEos5Nc6wQ/Recurve_show_all_lineages.png" alt=""><figcaption></figcaption></figure>


# 自动化测试

Data tests are assertions that you make about models and resources in a project. These tests validate the correctness of the transformed data and ensure results from the model meet predefined standards. At its core, a data test is simply a SQL or Jinja query that selects rows meeting a failing condition.

Data test is one of the *dbt* artifacts that Recurve integrates into its data validation capabilities.

There are two types of data tests:

* **Generic test**: a test designed to be reusable across multiple models, columns, or tables. It targets specific data but can be applied broadly to check for common conditions or constraints.&#x20;
* **Singular test**: a custom SQL-based test where you can write a specific SQL query to validate data. It is typically used for more specific or complex checks that are unique to a particular model or situation.

Recurve provides a wide collections of template for built-in generic tests, as well as the flexibility to write custom queries to cover more advanced scenarios. Built-in generic tests provide the the basic but essential validations, such as `NULL` check or referential integrity, while custom generic tests and singular tests can deal with complex business logic.

As with any quality control practice, we recommend starting with most basic testing scenarios before moving to complex cases. You can first apply built-in generic tests to validate the core assumptions about your dataset structure, then add custom tests to reflect specific business rules.

## Test categories

Data tests are associated with categories that reflect relevant business metrics:

<table><thead><tr><th width="159">Category</th><th>Defintion</th><th>Example</th></tr></thead><tbody><tr><td>Freshness</td><td>Check the timestamp to see if the data is up-to-date and made available for the intended use cases.</td><td><p></p><ul><li>A daily sales report should have data of the most recent transactions.</li><li>Raw data is expected to be ingested daily before 6pm.</li></ul></td></tr><tr><td>Volume</td><td>Check that number of rows are properly processed and falls within a specified range.</td><td><ul><li>Updated data should be no less than 1000 records everyday.</li></ul></td></tr><tr><td>Completeness</td><td>Check if there are missing values in datasets.</td><td><ul><li>Timestamp column should not contain <code>NULL</code> values.</li><li>Name column should not contain empty strings.</li></ul></td></tr><tr><td>Validity</td><td>Check if values in a column falls within a specified list or adheres to a defined format.</td><td><p></p><ul><li>String value should be within the list of enums.</li><li>Numeric value should be within the expected data range.</li></ul></td></tr><tr><td>Uniqueness</td><td>Check for undesired duplicates of data within a dataset.</td><td><ul><li>In the <em>order</em> table, no two records should have the same combination of <code>order_id</code> and <code>product_id</code> values.</li></ul></td></tr><tr><td>Consistency</td><td>Check if aggregated data aligns correctly with the expected results.</td><td><ul><li>The total sales amount in <em>monthly_sales</em> is aggregated from daily transactions in <em>daily_sales</em> table. Consistency check should be applied to ensure montly total sales is consistent with the sum of daily sales.</li></ul></td></tr></tbody></table>

## Test severity

A data test applied to an asset returns a list of failing rows as its result. Each test result has a severity level indicating its significance: Passed, Warning, or Error.&#x20;

In the **Severity level** section of a test, you can set thresholds for these levels based on the number of failures:

<figure><img src="https://content.gitbook.com/content/MNJfiu2Or0lnmkm2x228/blobs/QVtnRIfLeFf31EfJAIj2/Recurve_test_template_security_level.png" alt=""><figcaption></figcaption></figure>

For example, a test that checks for data completeness (columns with `NULL` values) can have the following thresholds:

* **Error** if the `NULL` % is greater than 10%.&#x20;
* **Warning** if the `NULL` % is between 0% and 10%.
* **Passed** otherwise.

## Create test from a template

Test creation is centralized in the **Test case template** section, which displays all available test artifacts, including:

* **Templates**: templates for built-in generic tests, organized by their scope (column-level or table-level) and by test category.&#x20;
* **Custom generic tests**: generic tests defined in project library. See: [Custom generic tests](/cn-reorc-help-center/shu-ju-jian-mo/zi-dong-hua-ce-shi/custom-generic-tests).
* **Custom SQL**: singular tests for one-off use cases. See: [Singular tests](/cn-reorc-help-center/shu-ju-jian-mo/zi-dong-hua-ce-shi/singular-tests).

{% hint style="info" %}
Currently, Recurve supports adding tests to a model.
{% endhint %}

Follow these steps to create a test from template:

1. Open your model in the editor.
2. Switch to the **Test cases** tab and click **+ Add new**.
3. In the test template, you can see all the available test templates, including the templates for built-in tests and custom tests. Select a desired template.

   <figure><img src="https://content.gitbook.com/content/MNJfiu2Or0lnmkm2x228/blobs/BTm8o9ZtmVfYLGxCcaxM/Recurve_test_case_template.png" alt=""><figcaption></figcaption></figure>
4. Configure the test case.&#x20;

   The configuration may differ between templates. For example, in the template for **Row Values Freshness Check**, we need to specify the following:

   * Name: the displayed name in the test case list.
   * Description: provide the description to communicate your intentions.
   * Track data from column: specify the column to apply the test condition.
   * Condition (optional): limit the scope of the test to only certain rows based on specific criteria, ensuring that the comparison is meaningful within a defined context.
   * Severity: set the threshold for severity levels. See: [#test-result-and-severity](#test-result-and-severity "mention").
5. Click **Add**.

The new test will be displayed in the **Test cases** tab of the model.

## Test execution

Data tests assigned to a model are executed when you:

* Build and run the model using console. See: [Console](/cn-reorc-help-center/zi-chan-guan-li/console).
* Run a pipeline that involves the model. See: [任务调度](/cn-reorc-help-center/shu-ju-guan-dao/ren-wu-diao-du).


# Custom generic tests

Beyond built-in generic tests, you can write custom generic tests to cover complex testing scenarios.&#x20;

At bottom, generic tests are Jinja macros that return failing rows. These tests are considered project-level asset and can be used across different models in your project.&#x20;

To define a generic test, simply write a macro and wrap it within `{% test %} {% endtest %}` block. A generic test should accept one or both standard parameters:

* `model`: The model or resource where the test is applied.
* `column_name`: If the test validates assumptions about a specific column's data, include the `column_name` parameter.

Here's an example:&#x20;

This `payment_amount_reasonable` test receives four parameters: the model, column name, minimum and maximum amounts. Inside, the validation logic is organized into a CTE (common table expression) that queries all the payment amounts not in the reasonable range.

```sql
-- custom generic test for reasonable payment amount

{% test payment_amount_reasonable(model, column_name, min_amount=0, max_amount=200) %}

with validation as (
    select
        {{ column_name }} as payment_amount
    from {{ model }}
    where {{ column_name }} < {{ min_amount }}
        or {{ column_name }} > {{ max_amount }}
)

select *
from validation

{% endtest %}
```

## Create a custom generic test

To create a custom generic test, follow these steps:

1. In your project, go to **Library** > **Generic Test**.
2. Click **+ Add new**.
3. Define the generic test with the following fields:

   * Generic test name: provide the displayed name for your test.
   * Description: describe the functionality of the test.
   * SQL Code: provide the test code.
   * Category: select the test category that the test should reflect.

   <figure><img src="https://content.gitbook.com/content/MNJfiu2Or0lnmkm2x228/blobs/4XCwauSeqdpex1pSDzYc/Recurve_add_custom_generic_test.png" alt=""><figcaption></figcaption></figure>
4. Click **Add**.

The created generic test is then accessible from **Test case template**. You set up the test the same way as a built-in genertic test. Specify parameter values in the **Configuration** section:

<figure><img src="https://content.gitbook.com/content/MNJfiu2Or0lnmkm2x228/blobs/YH0Agu4F7PTQwVyw8iGn/Recurve_add_custom_generic_test_template.png" alt="" width="563"><figcaption></figcaption></figure>


# Singular tests

Singular tests are simple SQL queries that return failing records of a model or a resource. They are typically used for one-off checks or specific business rules that do not require reusability.

You can use Jinja functions like `ref()` and `source()` to make reference to the target resource.

For example:

```sql
-- In the payment model, check for payment with negative amount

select *
from {{ ref('payment') }}
where amount < 0
```

## Create a singular test

To add a singular test to a model, open the **Test case template** and select the **Custom SQL** template:

<figure><img src="https://content.gitbook.com/content/MNJfiu2Or0lnmkm2x228/blobs/MMjJwoR8vS73miF4rWsr/Recurve_singular_test_template.png" alt="" width="563"><figcaption></figcaption></figure>


# 数据库特定配置


# SelectDB(Doris)

## SelectDB(Doris) 配置项

config 语法格式：[**​**](https://docs.getdbt.com/reference/resource-configs/doris-configs#table-configuration)

```sql
{{ config(
    materialized = "table",
    duplicate_key = [ "<column-name>", ... ],
    partition_by = [ "<column-name>", ... ],
    partition_type = "<engine-type>",
    partition_by_init = ["<pertition-init>", ... ]
    distributed_by = [ "<column-name>", ... ],
    buckets = "int",
    properties = {"<key>":"<value>",...}
      ...
    ]
) }}
```

在 Doris/SelectDB 上建模时，可使用的配置项如下：

| 配置项                 | 描述                                                                                      | Required or not?                     |
| ------------------- | --------------------------------------------------------------------------------------- | ------------------------------------ |
| `materialized`      | How the model will be materialized into Doris. Must be `table` to create a table model. | Required, can be defined in metadata |
| `duplicate_key`     | The key list of Doris table model: 'duplicate'.                                         | Required                             |
| `partition_by`      | The partition key list of Doris.                                                        | Optional                             |
| `partition_type`    | The partition type of Doris.                                                            | Optional (default: `RANGE`)          |
| `partition_by_init` | The partition rule or some real partitions item.                                        | Optional                             |
| `distributed_by`    | The bucket key list of Doris.                                                           | Required                             |
| `buckets`           | The bucket number in one Doris partition.                                               | Required                             |
| `properties`        | The other configuration of Doris.                                                       | Required                             |

## 增量模型

An incremental Doris table, item table model must be 'unique' and is configured using the following syntax:

#### **Incremental table configuration**[**​**](https://docs.getdbt.com/reference/resource-configs/doris-configs#incremental-table-configuration)

```sql
{{ config(
    materialized = "incremental",
    unique_key = [ "<column-name>", ... ],
    partition_by = [ "<column-name>", ... ],
    partition_type = "<engine-type>",
    partition_by_init = ["<pertition-init>", ... ]
    distributed_by = [ "<column-name>", ... ],
    buckets = "int",
    properties = {"<key>":"<value>",...}
      ...
    ]
) }}
```

Available configurations:

| Option              | Description                                                                                                                                                                           | Required or not?            |
| ------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------- |
| `materialized`      | How the model will be materialized into Doris. Must be `table` to create a table model.                                                                                               | Required                    |
| `unique_key`        | The key list of Doris table model :'[Doris unique](https://doris.apache.org/docs/data-table/data-model#uniq-model)'.                                                                  | Required                    |
| `partition_by`      | The partition key list of Doris. ([Doris partition](https://doris.apache.org/docs/data-table/data-partition))                                                                         | Optional                    |
| `partition_type`    | The partition type of Doris.                                                                                                                                                          | Optional (default: `RANGE`) |
| `partition_by_init` | The partition rule or some real partitions item.                                                                                                                                      | Optional                    |
| `distributed_by`    | The bucket key list of Doris. ([Doris distribute](https://doris.apache.org/docs/data-table/data-partition#partitioning-and-bucket))                                                   | Required                    |
| `buckets`           | The bucket number in one Doris partition.                                                                                                                                             | Required                    |
| `properties`        | The other configuration of Doris. ([Doris properties](https://doris.apache.org/docs/sql-manual/sql-reference/Data-Definition-Statements/Create/CREATE-TABLE/?&_highlight=properties)) | Required                    |

## 最佳实践

Here's a sample model using Doris for incrementally update by partition:

```sql
{{ 
  config(
    materialized = "incremental",
    unique_key = ["id"],  -- Specify the unique key for the incremental model
    partition_by = ["date"],  -- Partition by the date column
    partition_type = "RANGE",  -- Specify the partition type (e.g., RANGE, HASH)
    partition_by_init = ["2025-01-01"],  -- Initial partition value
    distributed_by = ["id"],  -- Distribute by the id column
    buckets = 10,  -- Number of buckets for distribution
    properties = {
      "compression": "lz4",  -- Example property for compression
      "replication_factor": "2"  -- Example property for replication factor
    }
  ) 
}}

SELECT
    id AS order_id,
    DATE(ordered_at) AS date,
    order_total,
    ordered_at,
    NOW() AS updated_at
FROM
    {{ source('ecom', 'raw_orders') }}
    
{% if is_incremental() %}
WHERE
    DATE(ordered_at) = '{{ var("dt") }}'  -- Process only current date's data
{% endif %}
```

查看更多用法，可参考 [Doris 官方文档](https://doris.apache.org/docs/dev/ecosystem/dbt-doris-adapter#usage-examples)


---

[Next Page](https://docs.reorc.com/llms-full.txt/1)